
Windows Errors? Fix Them Before They Spread
Repair common Windows errors and clear accumulated junk for a smoother, more stable PC - no reinstall needed.Free scan · no reinstallCrashes, No Sound, or Screen Glitches?
Random freezes, missing sound and display glitches usually trace back to one bad driver. Find and replace yours safely.Free scan · under a minuteiTechGuides is reader-supported. When you buy through links on our site, we may earn an affiliate commission. As an Amazon Associate I earn from qualifying purchases. Learn more
If by “unrestricted AI” you mean running an assistant on your own computer instead of sending prompts to a hosted service, the strongest alternatives are Ollama, llama.cpp, LM Studio, Jan, AnythingLLM and Open WebUI. They solve different problems: some run models, some provide a desktop interface, and some organize document question-answering. None of these tools, by themselves, proves that a model is uncensored, safer or more capable. Privacy depends on the entire path your data takes, including the selected inference endpoint, document extraction, embeddings, tools and any cloud API you connect.
What does “unrestricted AI” mean in a local and private setup?
The phrase combines three separate ideas that should be evaluated independently:
- Refusal behavior: whether a particular model declines certain requests. The software sources considered here do not compare models’ refusals or safeguards.
- Local hosting: whether model inference runs on hardware you control rather than on a provider’s server.
- Alternatives to a hosted service: using a different interface, runtime or provider connection while retaining the ability to choose where processing occurs.
Ollama, llama.cpp, LM Studio, Jan, AnythingLLM and Open WebUI address the second and third meanings. They do not establish the first. A locally downloaded model can still refuse requests, and a model that appears permissive can present safety, legal or operational risks. Evaluate the exact model, version, license and intended use separately from the application that runs it.
What’s actually slowing this PC down?
Pick the symptom - the matching free tool is one click away.
Which local AI tools are alternatives to a hosted chatbot?
Choose according to the job you need done, not a vague “unrestricted” label. The following distinctions come from Open WebUI’s current alternatives and provider documentation, accessed October 25, 2026.
#1 Best Overall

- EVOLUTION AMD RYZEN AI MAX+ 395 MINI PC - GMKtec EVO-X2 is the next evolution in AI mini PC Ryzen Strix Halo series. Thanks to AMD Simultaneous Multithreading (SMT) the core-count is effectively doubled, to 32 threads. Ryzen AI Max+ 395 has 64 MB of L3 cache and can boost up to 5.1 GHz, depending on the workload. The Ryzen AI Max+ 395 is currently rated as the "most powerful x86 APU" on the market for AI computing.
- AI NPU with XDNA 2 ARCHITECTURE - Powered by 16 “Zen 5” CPU cores, 50+ peak AI TOPS XDNA 2 NPU and a truly massive integrated GPU driven by 40 AMD RDNA 3.5 CUs, the Ryzen AI MAX+ 395 is a transformative upgrade and delivers a significant performance boost over the competition. The Ryzen AI Max+ 395 excels in consumer AI workloads like the llama.cpp-powered application: LM Studio. Shaping up to be the must-have app for client LLM workloads, LM Studio allows users to locally run the latest language model without any technical knowledge required and unleash their creativity and productivity.
- AMD RADEON 8090S iGPU GAMING PC - The AMD Radeon RX 8060S offers all 40 CUs with up to 2.9 GHz graphics clock and uses the new RDNA 3.5 architecture. The powerful iGPU is positioned between an RTX 4060 and 4070 laptop GPU and therefore enables gaming in FHD at maximum details in most demanding games. The 8060S can also utilize the full 64GB pool, which is perfect for running LLMs such as Deepseek 32B, which runs comfortably on this machine.
- EIGHT CHANNEL LPDDR5X - LPDDR5X is a new ground breaking memory small form factor installed on-board. With blazing speeds up to to 8000MT/s, it runs 1.5x faster than the DDR5 SODIMMs; 90% better performance over DDR5 SODIMMs in video conferencing and photo editing; 30% better performance in productivity apps; 4% better performance in digital content workloads.
- QUAD SCREEN 8K DISPLAY SUPPORT - EVO-X2 AI Mini PC support 4-screen 4K/8K output via HDMI 2.1 (8K@60Hz), DisplayPort 1.4 (4K@60Hz), and dual USB 4 40Gbps Transfer speed (supporting PD3.0/DP1.4/DATA). Ideal for gaming, video editing, and multitasking, it provides expansive and crisp multi-display support.
| Tool | Primary role | Local and cloud capability | Best fit | Important qualification |
|---|---|---|---|---|
| Ollama | Local model runner with desktop and command-line options | Runs downloaded models locally; also has an OpenAI-compatible API and distinguishes cloud-hosted models | A straightforward local runtime that other interfaces can call | Its privacy policy covers content processed locally, not every connected service |
| llama.cpp | Technical local inference engine, including efficient GGUF inference | Designed for local execution and exposes a compatible API | Users who want control over model files, quantization and deployment | More hands-on than a turnkey desktop application |
| LM Studio | Desktop app for discovering, downloading and running models | Runs a local server that compatible clients can use | People who prefer a polished graphical workflow | The alternatives guide describes it as proprietary/free; verify the current terms for your deployment |
| Jan | Standalone desktop local-AI application | Local-first desktop workflow | A self-contained desktop experience | Open WebUI’s alternatives table lists it as Apache 2.0; confirm the version you install |
| AnythingLLM | Document question-answering workspace | Can use local models, but document processing may involve separately configured services | Searching and chatting with a private collection of files | Audit extraction, embedding and storage components before promising on-device privacy |
| Open WebUI | Web interface that connects to local and cloud providers | Endpoint selection controls where inference happens; cloud tools and providers remain possible | One interface for several runtimes, models and team workflows | Version-specific licensing includes a branding clause from v0.6.6 |
This is a workflow comparison, not a ranking of speed, output quality, safety or hardware efficiency. The available evidence does not support those rankings.
How does local inference actually protect prompts?
Local inference means the selected model endpoint receives and processes the prompt on your machine or server. It does not automatically mean that every part of the application is local. Open WebUI’s provider documentation states that the selected endpoint determines where inference occurs: selecting a cloud model sends the prompt and included context to that provider.
The complete processing chain
- Interface: your desktop or web client accepts the message, attachments and conversation history.
- Inference server: Ollama, llama.cpp, LM Studio or Jan loads a model and generates a response. If this endpoint is local, generation can stay on your hardware.
- Document extraction: PDFs, scans and office files may be converted to text by a separate extractor or OCR service.
- Embeddings and retrieval: a system such as AnythingLLM or a configured Open WebUI workflow may create embeddings and store them in a vector database. A cloud embedding provider can receive document text even when the language model is local.
- Tools and connectors: search, browsing, code execution, transcription or external APIs can transmit selected content outside the machine.
- Telemetry and logs: the application, operating system or provider may retain limited device, diagnostic or usage metadata.
For a genuinely private workflow, map every hop before uploading sensitive material. “Local model” is a statement about one endpoint, not a guarantee about the interface, plugins or data pipeline around it.
Free tools Windows power users keep installed
One-click scans. No signup required.
Which tool should you choose for your workflow?
Choose Ollama for a simple local runtime and API
Ollama is the practical starting point when you want to download models, run them locally and let another client connect through an API. Open WebUI’s Ollama guide, last updated August 2026, documents desktop and command-line use as well as the OpenAI-compatible interface. A typical setup is to install Ollama, download a model from its library, start the local service and point your chosen interface at that endpoint.
Ollama’s privacy policy, last updated March 2026, says, “Your data stays on your machine.” That is Ollama’s own statement about content processed locally, not an independent audit. The same policy distinguishes cloud-hosted models and notes collection of limited device and usage metadata, so confirm which mode and telemetry settings apply to your installation.
Choose llama.cpp when control matters more than convenience
llama.cpp is an inference engine rather than a polished end-user workspace. It is associated with efficient GGUF model inference and a compatible API. This route suits an administrator who wants to select model files, quantization and server parameters directly, or embed inference into an existing application.
The trade-off is operational work: you must obtain a compatible model file, configure the server, monitor memory use and handle updates yourself. The sources do not establish a universal performance advantage over the other runtimes; test the exact model and build on your hardware.
Choose LM Studio for a graphical desktop experience
LM Studio focuses on discovering, downloading and running local models from a desktop application. It can expose a local API server for compatible clients, making it useful when you want a graphical model catalog but still need Open WebUI or another application on top.
Rank #2
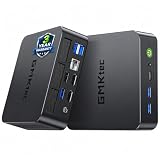
- 97 TOPS AI SUPERCHARGED PERFORMANCE – BUILT FOR THE AI ERA --- Powered by the next-gen Intel Core Ultra 5 226V processor (up to 4.50GHz) built on TSMC’s advanced 3nm N3B process, the K17 delivers an incredible 97 TOPS of total AI performance (40 TOPS NPU + 53 TOPS GPU). Unlike traditional systems that rely solely on CPU/GPU, this triple AI architecture enables real-time local AI processing, faster inference, and smoother multitasking—perfect for AI assistants, local LLMs, content generation, and intelligent workflows without cloud dependency.
- INTEL ARC 130V GRAPHICS – DISCRETE-CLASS POWER, NO GPU REQUIRED --- Experience next-level integrated graphics with the Intel Arc 130V GPU (up to 1.85GHz), delivering up to 53 TOPS AI compute and supporting hardware ray tracing, XeSS AI upscaling, and AV1 encoding. Compared to previous-gen iGPUs, performance is massively improved, enabling smooth AAA gaming, 4K video editing, and real-time rendering—bringing desktop-class graphics power into a compact, energy-efficient mini PC.
- DEDICATED NPU – TRUE LOCAL AI, FASTER & MORE SECURE --- Equipped with Intel AI Boost NPU delivering 40 TOPS of dedicated AI acceleration, the K17 handles AI workloads independently without consuming CPU/GPU resources. From AI noise cancellation and real-time translation to local model deployment and generative AI tasks, enjoy faster response times, lower power consumption, and enhanced data privacy with fully local processing.
- LPDDR5X 8533 MT/s HIGH-BANDWIDTH MEMORY – BUILT FOR HEAVY MULTITASKING --- Featuring 16GB LPDDR5X onboard memory running at blazing 8533MT/s, the K17 provides ultra-high bandwidth for demanding workloads. Compared to traditional DDR4 systems, it ensures faster data throughput, smoother multitasking, and stable large-model loading—ideal for AI applications, creative software, and multi-window productivity without lag.
- DUAL M.2 SSD (GEN5 + GEN4) EXPANSION – UP TO 16TB MASSIVE STORAGE --- Designed for power users, the K17 supports dual M.2 2280 SSD slots (PCIe Gen5×4 + Gen4×2), enabling up to 16TB total storage (8TB×2). Experience ultra-fast read/write speeds for massive datasets, AI model storage, and 4K/8K media files—no more external drives or storage limitations, everything stays fast and accessible.
Open WebUI’s alternatives guide describes LM Studio as proprietary/free. Because licensing and feature terms can change, read the current terms before deploying it for a business, classroom or multi-user installation.
Choose Jan for a standalone desktop assistant
Jan is listed as a standalone desktop option for local AI, with Apache 2.0 identified in Open WebUI’s alternatives table. It is a reasonable choice when you want a self-contained application rather than assembling a runtime and web interface separately. Verify the model formats, operating-system support and current release terms for the model you intend to run.
Choose AnythingLLM for document question-answering
AnythingLLM is aimed at workspaces where the central task is asking questions about a document collection. It can be paired with local inference, but “local model” does not prove that file parsing, OCR, embeddings, indexing or storage are local. Trace those components and disable cloud services when your policy requires that documents remain on-site.
Recommended Free Tools
Choose Open WebUI when you need one interface for many endpoints
Open WebUI can connect to local runtimes such as Ollama and llama.cpp as well as cloud providers. That flexibility is useful for switching models, creating shared workspaces or preserving a familiar chat interface while you test local inference. It also creates a privacy risk if users can select a cloud endpoint without understanding that prompts and attached context leave the network.
Open WebUI’s license documentation describes a branding clause introduced with version 0.6.6. The stated threshold is deployments serving 50 or more users in aggregate, with exceptions described for smaller internal deployments. Treat this as a version-specific licensing requirement: read the project’s current license text and assess your actual deployment before distributing a branded service.
How do you set up a private local AI workflow?
Use this sequence to keep the privacy boundary explicit.
- Define the data boundary. List the documents, prompts and users that may be handled. Decide whether any cloud processing is prohibited or merely restricted to non-sensitive data.
- Select the runtime. Pick Ollama or a desktop app for a simpler path; choose llama.cpp when you need low-level control. Confirm that the model format is supported.
- Install and verify the local endpoint. Start the runtime, load a model and make a test request while disconnected from the internet if your policy permits. Record the local address and whether the service binds only to localhost or to a wider network.
- Connect the interface. In Open WebUI or another client, add the local provider and select it explicitly for each conversation. Do not assume the last-used endpoint is still local after an update.
- Test attachments separately. Send a harmless sample file and inspect which extractor, OCR engine, embedding model and database receive it. A local chat test does not validate document privacy.
- Review tools and integrations. Disable browsing, external search, remote code execution and third-party APIs unless each is approved. If a tool is required, document exactly what text it can transmit.
- Control accounts and logs. Use separate user accounts, protect the model directory and review application logs for prompts, filenames or metadata. Set retention limits where the software supports them.
- Re-test after changes. Repeat the checks after changing models, providers, plugins, embeddings or application versions. A new connector can change the data path without changing the chat screen.
What hardware do local models require?
Local inference runs downloaded model files on your own hardware, but the supplied evidence does not establish validated RAM, GPU, storage or speed recommendations. Requirements vary with model size, quantization, context length, concurrent users and runtime. Check the exact model’s documentation and the runtime’s current requirements rather than buying a computer from a generic “AI-ready” specification.
- Memory: the model weights, runtime overhead and conversation context must fit in available system or graphics memory. Larger context windows increase pressure even when the model file itself fits.
- Storage: keep space for the model, alternate quantizations, temporary downloads, embeddings and document indexes.
- Graphics hardware: supported acceleration can improve responsiveness, but compatibility differs by operating system, driver and runtime build.
- Thermals and power: sustained generation can keep a laptop or small desktop under load; plan ventilation and power delivery for your expected session length.
- Multi-user use: one interactive user and a shared server have different concurrency and memory needs. Do not infer team capacity from a single-user demonstration.
If you are considering a new computer, first choose the model and runtime, then check their published requirements and measure a representative workload. No general hardware tier is established by the sources for all local models.
Rank #3

- 【15W Efficiency for 24/7 Business & AI Workloads】Why pay for power you don't need? The GEEKOM A7's 15W TDP Ryzen 7 7730U processor helps reduce energy use and heat during extended operation. Run cloud AI assistants and AI Agent workflows for summaries, email, research, and scheduled tasks, or power business applications like digital signage, POS terminals, kiosks, and office automation. Four smart power modes—Silent (10W), Balanced (15W), Performance (20W), and High-Speed (30W)—let you match power to the workload, balancing quiet everyday operation with extra performance when needed.
- 【Ryzen 7 7730U – More Than a Low-Power PC】Think low power means less performance? Not here. The Ryzen 7 7730U mini computer packs 8 cores, 16 threads, and up to 4.5GHz, giving you the power to handle multitasking, dozens of tabs, video calls, and creative work smoothly. AMD Radeon Graphics supports 4K playback, multi-display work, photo editing, and casual gaming without a dedicated GPU. Compared with the Ryzen 7 5825U and Ryzen 5 7430U, it delivers up to 20% higher performance for faster response and smoother everyday computing—all in a compact, energy-efficient Mini desktop.
- 【32GB May Be the Smarter Buy】More memory isn’t just about bigger numbers. AI agents, background tasks, browser sessions, and daily apps all use RAM. With 32GB, the GEEKOM mini PC gives you more room for AI-assisted workflows, heavy multitasking, and large projects without constantly closing apps to free up memory. Choose 32GB upfront to skip an immediate upgrade and avoid future upgrade hassles as your needs grow. The 500GB PCIe Gen4 x4 SSD delivers fast storage, with support for up to 64GB RAM and 4TB SSD storage when you need more.
- 【Premium Metal Design, 5 Security Protections &3-Year Coverage】Why settle for plastic? The GEEKOM mini PC features a premium aluminum alloy chassis that resists daily wear and helps dissipate heat during extended use. Five hardware-level security protections help safeguard devices and data. Backed by a 3-year coverage and US-based local repair support, with CE, FCC, CB, and CCC certifications, it delivers long-term reliability and dependable quality for large-scale business and educational deployments.
- 【One Mini PC, All Your Ports】Stay connected with dual USB-C ports, 5 USB 3.2 ports, dual HDMI 2.0, and a 2.5G LAN port for fast, flexible connectivity. The USB-C ports support high-speed data transfer, display output, and peripheral power, while Wi-Fi 6E keeps streaming, file transfers, and online work fast and reliable. From multiple peripherals to high-resolution displays, everything you need stays within easy reach.
Does running a model locally make it unrestricted or safer?
No. Hosting changes where computation occurs; it does not define the model’s refusal policy, training data, safeguards or legal suitability. The tools covered here provide software and provider connections, not a model-by-model safety comparison.
Assess the selected model’s documentation, license and release notes. Test benign boundary cases in a controlled environment, establish an acceptable-use policy and restrict access to sensitive capabilities such as code execution or network tools. Avoid describing a model as “uncensored,” “safe” or “unrestricted” unless current, model-specific evidence supports that precise claim.
How can you verify that a supposedly private workflow stays private?
Verification should be an evidence-based check of network and application behavior, not a label on the product page.
The Tool Desk
Outbyte Driver Updater FREEFix the driver behind crashes, sound loss and screen glitchesFind Drivers →Outbyte PC Repair FREEClear out junk files and repair common Windows errorsFree Scan →- Record the endpoint selected for each model and confirm whether it is a local address or a cloud provider.
- Inspect provider settings for cloud models, remote embeddings, extraction services, browsing and telemetry.
- Run a test with network access restricted and compare which features still work. A failure can reveal an undocumented dependency.
- Review firewall or proxy logs for outbound connections while sending a distinctive, non-sensitive test phrase.
- Check where conversation history, uploaded files, extracted text and vector indexes are stored and who can read them.
- Document retention, deletion and backup behavior for every component, including operating-system backups.
These checks can establish your deployment’s behavior at a point in time; they do not turn a vendor privacy statement into an independent certification. Ollama’s “Your data stays on your machine” wording should therefore be attributed to Ollama and limited to locally processed content.
Independent reader supportYour contribution helps us test, update, and keep practical guides available for everyone.What are the common failure modes and fixes?
The interface sends a prompt to the wrong endpoint
Symptom: a response appears even though the local runtime is stopped, or the provider dashboard shows usage. Fix: inspect the conversation’s selected model, remove unapproved cloud providers, and require users to choose a clearly labeled local endpoint.
Chat is local but document indexing is remote
Symptom: ordinary prompts stay on the machine, but uploading a PDF triggers traffic to an embedding or extraction service. Fix: configure local extraction and embeddings, or prohibit document uploads in that workflow until every component is approved.
The model loads but runs out of memory
Symptom: startup fails, generation stops or the operating system begins swapping. Fix: use a smaller or more aggressively quantized model, reduce context length and close competing applications. Verify the model’s documented requirements before changing hardware.
A team deployment violates licensing terms
Symptom: an Open WebUI installation upgraded to v0.6.6 or later serves a large user population without reviewing the branding clause. Fix: count users in aggregate, read the current license and apply the stated exceptions only when your deployment clearly qualifies.
Rank #4
- EVOLUTION AMD RYZEN AI MAX+ 395 MINI PC - GMKtec EVO-X2 is the next evolution in AI mini PC Ryzen Strix Halo series. Thanks to AMD Simultaneous Multithreading (SMT) the core-count is effectively doubled, to 32 threads. Ryzen AI Max+ 395 has 64 MB of L3 cache and can boost up to 5.1 GHz, depending on the workload. The Ryzen AI Max+ 395 is currently rated as the "most powerful x86 APU" on the market for AI computing.
- AI NPU with XDNA 2 ARCHITECTURE - Powered by 16 “Zen 5” CPU cores, 50+ peak AI TOPS XDNA 2 NPU and a truly massive integrated GPU driven by 40 AMD RDNA 3.5 CUs, the Ryzen AI MAX+ 395 is a transformative upgrade and delivers a significant performance boost over the competition. The Ryzen AI Max+ 395 excels in consumer AI workloads like the llama.cpp-powered application: LM Studio. Shaping up to be the must-have app for client LLM workloads, LM Studio allows users to locally run the latest language model without any technical knowledge required and unleash their creativity and productivity.
- AMD RADEON 8090S iGPU GAMING PC - The AMD Radeon RX 8060S offers all 40 CUs with up to 2.9 GHz graphics clock and uses the new RDNA 3.5 architecture. The powerful iGPU is positioned between an RTX 4060 and 4070 laptop GPU and therefore enables gaming in FHD at maximum details in most demanding games. The 8060S can also utilize the full 64GB pool, which is perfect for running LLMs such as Deepseek 32B, which runs comfortably on this machine.
- EIGHT CHANNEL LPDDR5X - LPDDR5X is a new ground breaking memory small form factor installed on-board. With blazing speeds up to to 8000MT/s, it runs 1.5x faster than the DDR5 SODIMMs; 90% better performance over DDR5 SODIMMs in video conferencing and photo editing; 30% better performance in productivity apps; 4% better performance in digital content workloads.
- QUAD SCREEN 8K DISPLAY SUPPORT - EVO-X2 AI Mini PC support 4-screen 4K/8K output via HDMI 2.1 (8K@60Hz), DisplayPort 1.4 (4K@60Hz), and dual USB 4 40Gbps Transfer speed (supporting PD3.0/DP1.4/DATA). Ideal for gaming, video editing, and multitasking, it provides expansive and crisp multi-display support.
Updates change behavior
Symptom: a provider, model list or privacy setting changes after an upgrade. Fix: pin versions where practical, record configuration, and repeat endpoint and network tests after every runtime, interface or integration update.
Which setup is best for common use cases?
| Use case | Starting point | Why | Boundary to verify |
|---|---|---|---|
| One person experimenting with local chat | Ollama or LM Studio | Both provide accessible ways to obtain and run local models | Model storage, telemetry and any enabled cloud mode |
| Engineering-controlled inference service | llama.cpp or Ollama behind a controlled API | Offers a local endpoint that applications can call | Network binding, authentication, concurrency and logs |
| Desktop user wanting minimal setup | Jan or LM Studio | Standalone graphical workflows reduce assembly work | Current license, supported formats and update behavior |
| Searching a private document collection | AnythingLLM with a local runtime | Provides a document-Q&A workspace | Extraction, OCR, embeddings, vector storage and backups |
| Several runtimes in one chat interface | Open WebUI | Connects local and cloud providers from one interface | Endpoint labeling, user permissions and v0.6.6+ licensing |
What should you remember before choosing an alternative?
Start with the data path, not the marketing label. Select a runtime that matches your technical comfort, use a document workspace only after tracing its indexing pipeline, and treat cloud connections as opt-in destinations rather than invisible implementation details. Finally, evaluate the exact model’s behavior, requirements and license independently: local software can give you control over processing location, but it cannot by itself make a model unrestricted, safe or suitable for every request.
Frequently Asked Questions
Can I use a local model without an internet connection?
Yes, once the runtime, model files and any required interface components are installed. Features that depend on cloud providers, remote embeddings, browsing, account checks or update services will not work offline, so test the specific workflow with network access disabled.
Do these 3 things before closing this tab:
1Scan for outdated or missing drivers - takes under a minute2Clear out junk files and repair common Windows errors3Fix the driver behind crashes, sound loss and screen glitchesIs Open WebUI completely private when it uses Ollama?
Only the inference request to a locally selected Ollama endpoint is local by that fact alone. Open WebUI can also connect cloud models, extraction services, embedding providers and tools, so privacy depends on which endpoints and integrations your instance permits.
What is the difference between a local model runner and a desktop AI app?
A runner such as Ollama or llama.cpp primarily loads models and serves inference, often through an API. A desktop app such as LM Studio or Jan packages model discovery and chat in a graphical interface; some desktop apps also expose a local server.
Do local AI tools remove content safeguards?
No conclusion about safeguards follows from where inference runs. Refusal behavior is determined by the particular model and version, while the software controls execution and connectivity; assess those two layers separately.
Does a local document chatbot keep every file on my computer?
Not necessarily. File parsing, OCR, embeddings, vector indexing, backups and optional tools may be separate services that send content elsewhere. Verify each component’s endpoint and storage location before importing confidential documents.
Quick wins for a faster PC:
Repair Windows errors before they cause bigger problemsFix Now →Fix the driver behind crashes, sound loss and screen glitchesFind Drivers →Quick Recap
Product prices and availability are accurate as of the date/time indicated and are subject to change. Any price and availability information displayed on Amazon at the time of purchase will apply.

