
Recommended Free Tools
iTechGuides is reader-supported. When you buy through links on our site, we may earn an affiliate commission. As an Amazon Associate I earn from qualifying purchases. Learn more
Neither local nor cloud AI wins on every measure. A local large language model (LLM) runs inference on hardware you control, which can keep prompts on that machine and work without a network connection. It also makes you responsible for hardware capacity, security, updates, backups, and electricity. Cloud AI sends requests to a provider’s infrastructure, so it can offer larger models and elastic capacity, but you must evaluate the provider’s data handling, region, contracts, service limits, and connectivity.
The practical choice depends on four things: the quality your task requires, the sensitivity of the data, how heavily and predictably you will use the model, and what hardware and operational support you have. A hybrid design—local for suitable or offline work and cloud for tasks that need more capability—often gives the best fit when policy permits it.
What is the difference between a local LLM and cloud AI?
A local LLM performs model inference on an endpoint, server, or private infrastructure controlled by you or your organization. Cloud AI sends the prompt, files, or other inputs to a provider-hosted service that performs the inference remotely. The distinction describes where computation happens; it does not by itself prove that one option is private, inexpensive, fast, or more accurate.
Local inference
After the model and runtime are installed, the prompt can remain on the computer or server running the model. That reduces the number of outside parties receiving the content, but the operator must protect the device, restrict access, secure local APIs, manage logs and backups, install updates, and control model downloads. Malware, a compromised account, a shared workstation, or an exposed service can still disclose local data.
#1 Best Overall

- Boosts System Performance: 32GB DDR5 RAM laptop memory kit (2x16GB) that operates at 5600MHz, 5200MHz, or 4800MHz to improve multitasking and system responsiveness for smoother performance
- Accelerated gaming performance: Every millisecond gained in fast-paced gameplay counts—power through heavy workloads and benefit from versatile downclocking and higher frame rates
- Optimized DDR5 compatibility: Best for 12th Gen Intel Core and AMD Ryzen 7000 Series processors — Intel XMP 3.0 and AMD EXPO also supported on the same RAM module
- Trusted Micron Quality: Backed by 42 years of memory expertise, this DDR5 RAM is rigorously tested at both component and module levels, ensuring top performance and reliability
- ECC Type = Non-ECC, Form Factor = SODIMM, Pin Count = 262-Pin, PC Speed = PC5-44800, Voltage = 1.1V, Rank And Configuration = 1Rx8
Cloud inference
A cloud request travels to the provider’s infrastructure and returns a generated response. The provider operates the underlying compute and usually handles capacity, hardware replacement, and much of the platform maintenance. You still need to check what the service stores, how it logs requests, where processing occurs, which administrators or subprocessors can access it, and which contractual or regulatory rules apply to your data. Policies differ by service and plan, so there is no universal cloud privacy result.
Hybrid inference
Hybrid routing uses a local model for tasks that are short, offline, policy-constrained, or adequately handled on the device, and sends other tasks to a cloud model when stronger reasoning, longer context, current information, or higher concurrency is needed. Microsoft’s guidance describes checking local readiness and obtaining consent for model downloads or cloud fallback. A hybrid system should show users when data leaves the device and enforce the organization’s policy rather than silently switching routes.
Is a local LLM more private?
It can be, but local execution is not an automatic privacy guarantee. Privacy improves when sensitive prompts never leave controlled hardware, provided that hardware, software, accounts, logs, backups, and network exposure are secured.
The Tool Desk
Outbyte PC Repair FREEClear out junk files and repair common Windows errorsFree Scan →Outbyte Driver Updater FREEFix the driver behind crashes, sound loss and screen glitchesFind Drivers →Map the complete local data path
- Input: Identify whether prompts, uploaded documents, images, and retrieved data are read by the local runtime or by an additional plug-in.
- Storage: Check chat history, temporary files, vector indexes, crash reports, and model-server logs. Encrypt disks and set retention periods instead of keeping every request indefinitely.
- Access: Require operating-system authentication, separate user accounts, least-privilege file permissions, and authentication on any local HTTP or network API.
- Backups: Treat backups and synchronized folders as copies of the prompt data. Apply the same retention and access rules to them.
- Updates and downloads: Verify model files and runtime packages, keep security patches current, and use trusted repositories. A model download or catalog refresh can create network traffic even when inference itself is offline.
- Outbound connections: Block unexpected telemetry and egress where policy requires it, and monitor the runtime so a plug-in cannot quietly send prompts elsewhere.
What Microsoft Foundry Local demonstrates
Microsoft’s Windows AI FAQ states that Foundry Local performs inference on the device and that inference input and output do not leave the machine after setup. The same FAQ identifies network traffic for the initial model download and optional catalog-metadata refreshes. That is a specific behavior of Foundry Local, not evidence that every local-model application has the same traffic pattern.
Cloud privacy questions to ask
Before sending confidential material to a cloud endpoint, obtain written answers about request retention, abuse monitoring, human access, training use, encryption, data residency, deletion, subprocessors, breach notification, and administrator controls. Confirm whether the service tier you selected has different terms from a consumer account. If a policy prohibits provider processing in a particular region or for a particular class of records, a local model may be required even when the cloud service appears technically secure.
Is running an LLM locally cheaper?
Only when the workload uses the hardware enough to justify its total ownership cost. Local inference avoids a per-request service bill but requires suitable hardware and continuing operating effort. Cloud pricing is usage-based in Microsoft’s comparison, so a low-volume user may spend less in the cloud while a heavily utilized, stable workload may favor owned infrastructure.
Include every local cost
- Purchase or lease price of a workstation, GPU server, memory, storage, and any replacement hardware.
- Electricity, cooling, and the cost of keeping the machine available during expected usage hours.
- Model storage, duplicate copies, backup capacity, and secure disposal when a disk is retired.
- Runtime installation, security updates, monitoring, troubleshooting, and integration work.
- Staff time for access control, incident response, model evaluation, and hardware replacement.
- Lost productivity when the device is saturated, unavailable, or being repaired.
Measure the cloud alternative on the same workload
Record requests per day, average and peak input tokens, generated output, context length, file-processing volume, concurrency, and the model or features required. Compare the provider’s charges for that exact pattern with the local machine’s amortized hardware, power, support, and utilization cost. Include minimum commitments, rate changes, storage, networking, and the cost of a second region or backup service if your availability target requires them.
Rank #2
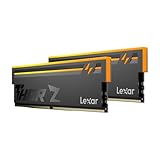
- Unleash Next-Gen Dominance: Experience Lexar DDR5 RAM performance with the Lexar THOR Z Series RGB DDR5 RAM 32GB Kit (2x16GB). Clocking at a blistering 6000MHz with low CL38 latency, this DDR5 desktop memory delivers up to 6000 MT/s for a full-throttle advantage. Whether you're building a high-end gaming rig or a professional workstation, this Lexar 32GB RAM kit ensures your system keeps pace with next-gen titles
- Sleek & Robust Thermal Design: Engineered for both aesthetics and endurance, this Lexar DDR5 RAM 6000MHz features an all-new streamlined design. The solid, sandblasted aluminum heatsink fuses a minimalist, razor-sharp aesthetic with uncompromising thermal control. This Lexar THOR Z Series armor ensures your DDR5 memory stays cool under pressure, delivering sustained peak performance during intense gaming sessions
- Game in Style with Brighter RGB Lighting: Elevate your build's aesthetics with the enhanced customizable RGB lighting on this Lexar RGB DDR5 RAM. Brighter and more vibrant than previous generations, the Lexar THOR Z Series RGB DDR5 RAM allows you to synchronize lighting effects with your components, creating a truly immersive gaming atmosphere that stands out from the crowd
- On-die ECC & PMIC for Rock-Solid Stability: Go beyond speed with reliability. This Lexar DDR5 RAM kit integrates On-die Error Correction Code (ECC) to automatically correct data errors, vastly improving stability and reliability for your critical tasks. The onboard Power Management Integrated Circuit (PMIC) ensures efficient power delivery, boosting the overall power efficiency of your DDR5 desktop memory for a longer-lasting, more stable system
- Seamless Compatibility with Intel & AMD: Worry-free upgrade guaranteed. The Lexar THOR Z Series DDR5 RAM is built for broad compatibility with the latest platforms. It fully supports Intel XMP 3.0 and AMD EXPO one-click overclocking, making it effortless to achieve the rated speeds. Trust Lexar DDR5 RAM to deliver seamless performance with mainstream DDR5 motherboards
How to interpret Lenovo’s 2025 TCO analysis
Lenovo Press’s On-Premise vs Cloud: Generative AI Total Cost of Ownership (2025 Edition), published May 23, 2025, says cloud is suited to short-term or bursty workloads and that on-premises infrastructure can be more cost-efficient at consistent utilization. The analysis focuses on core infrastructure, assumes an on-premises refresh cycle of three to five years, and excludes networking, facility overhead, and routine IT operations. Those boundaries prevent its result from being used as a universal break-even point for an individual, small office, or every model workload. A 2026 edition is indicated on the page, so figures from the 2025 paper should be treated as a dated planning reference.
A simple workload calculation
For a fair estimate, calculate local monthly cost = (hardware cost ÷ useful months) + power and cooling + storage and backup + administration. Calculate cloud monthly cost from the provider’s metered usage and fixed fees for the same requests. Run the estimate at low, expected, and peak utilization; a machine that looks expensive at 10 percent utilization can become economical at 80 percent, while a cloud bill can remain attractive for irregular demand.
Is local AI faster than cloud AI?
It depends on which part of speed you measure. Local inference removes the network trip, but generation is limited by the device’s CPU, GPU, NPU, memory bandwidth, model size, quantization, context length, runtime, and number of simultaneous users. Cloud services add network and queue variability but may run a larger model on specialized accelerators.
Separate the performance measures
| Measure | What affects local results | What affects cloud results |
|---|---|---|
| Time to first token | Model loading, available memory, prompt processing, and local accelerator speed | Network round trip, provider queue, prompt processing, and service load |
| Generation rate | Model size, quantization, hardware, context length, and concurrent sessions | Provider model, allocated hardware, rate limits, and shared service load |
| Completion quality | Model capability, tuning, context window, retrieval setup, and tool support | Selected model, service features, context limits, and system instructions |
| Availability | Power, hardware health, local network, and administrator maintenance | Internet access, provider uptime, quotas, account status, and regional outages |
Benchmark the real prompts and documents your users care about. Measure first-token latency, total completion time, tokens per second, error rate, and answer quality at the same temperature, context, and concurrency. No broadly applicable benchmark establishes a universal speed multiplier or quality winner between local and cloud inference.
Task fit matters more than a generic speed label
Microsoft’s current guidance positions local models for short, constrained, offline, or policy-limited work, while cloud models can fit complex reasoning, long-context tasks, current information, and workloads needing stronger capability. Google’s Android Studio guidance likewise warns that local models in that context may have lower accuracy, higher latency, and fewer features than cloud Gemini models. These are routing heuristics for the cited environments, not guarantees for every model or device.
What hardware does a local LLM need?
Requirements vary by model, runtime, quantization, context length, and concurrency. Microsoft identifies the CPU, GPU, NPU, memory, and storage as the key device resources. Google’s Android Studio documentation provides two concrete examples:
| Model example in Google’s Android Studio guidance | Total RAM | Storage | How to interpret it |
|---|---|---|---|
| Gemma E4B | 12 GB | 4 GB | Requirement for that setup, not a universal minimum for all deployments |
| Gemma 26B MoE | 24 GB | 17 GB | Requirement for that setup, not a universal minimum for all local LLMs |
These figures are examples from Google’s local-model instructions accessed October 25, 2026. Leave additional headroom for the operating system, runtime, context cache, application, and multiple users. A model that technically fits in memory can still swap to disk and become unusably slow.
Rank #3

- Requires overclocking/BIOS adjustments. Maximum speed and performance depends on system components, including motherboard and CPU.
- G.SKILL Flare X5 Series DDR5 U-DIMM Memory Kit, Model: F5-6000J3636F16GX2-FX5
- Non-ECC, DDR5 U-DIMM, 288-pin, for Desktop PC & Gaming
- Includes JEDEC default profile, and AMD EXPO & Intel XMP 3.0 memory overclock profile
- Do not mix memory kits. Memory kits are sold in matched kits that are designed to run together as a set. Mixing memory kits will result in stability issues or system failure.
Memory and accelerator checks
- Confirm total system RAM, not only the memory advertised for graphics.
- Check whether the runtime can use your GPU or NPU and how much dedicated or shared memory it reserves.
- Verify storage capacity for the model, alternate quantizations, tokenizer files, caches, logs, and updates.
- Check supported operating systems, instruction sets, drivers, and runtime versions before downloading a large model.
- For a shared service, estimate memory per concurrent session and the maximum context length, not just the single-user minimum.
If a compatible computer lacks capacity, a memory upgrade may help, but it is not a universal requirement. Verify the motherboard or laptop’s memory type, maximum supported capacity, slot availability, and operating-system limits before buying a kit such as 32GB DDR5. The cited model requirements do not establish DDR5 compatibility for any particular machine.
What’s actually slowing this PC down?
Pick the symptom - the matching free tool is one click away.
How do I set up and evaluate a local LLM?
Use a staged setup so you can stop before committing to expensive hardware or exposing sensitive data.
- Define the workload. Write down representative prompts, document sizes, required context, acceptable latency, quality criteria, and peak simultaneous users. Include an offline or disconnected scenario if one matters.
- Classify the data. Mark which inputs are public, internal, confidential, regulated, or prohibited from leaving a controlled environment. Decide whether cloud fallback is allowed for each class.
- Choose a model and runtime. Compare capability, context window, license terms, quantization options, tool support, and hardware requirements. Google’s Android Studio flow uses a local inference provider such as Ollama or LM Studio and a locally installed model; other applications have different compatibility lists.
- Check the machine. Confirm CPU, GPU or NPU, RAM, storage, drivers, and thermal limits against the selected model’s current documentation. Keep free memory and disk space for the runtime and context cache.
- Install securely. Download the runtime and model from trusted sources, verify checksums when provided, keep the model server bound to localhost until access controls are configured, and disable optional telemetry that policy does not permit.
- Run a quality and latency test. Use the same prompts you will use in production. Record first-token time, completion rate, total time, tokens per second, factual errors, refusal behavior, and memory use.
- Harden the service. Require authentication for network access, encrypt traffic between clients and the server, restrict file-system permissions, rotate credentials, patch the runtime, and define log retention.
- Pilot with realistic concurrency. Add users gradually. Watch for out-of-memory errors, thermal throttling, queue growth, context truncation, and degraded quality when several sessions run together.
- Document rollback. Keep a known-good model and runtime version, record configuration changes, and test how to remove cached prompts and model files when a device is retired.
When should I choose local, cloud, or hybrid AI?
Make the decision from the workload rather than from a blanket preference for one deployment label.
| Situation | Usually a better starting point | Reason to reconsider |
|---|---|---|
| Sensitive records that policy forbids sending to a provider | Local | Local security, logging, backups, and maintenance may exceed the team’s capability |
| Occasional experimentation or irregular demand | Cloud | Recurring volume, data-residency rules, or provider limits can change the calculation |
| Disconnected or intermittently connected site | Local | The selected model may not meet quality or latency needs |
| Long context, advanced reasoning, current web-connected information, or many concurrent users | Cloud | Cost, residency, outage tolerance, or policy may require a local alternative |
| Mixed workloads with clear data classes | Hybrid | Uncontrolled fallback can leak data or create inconsistent answers |
Build explicit routing rules
- Route by data classification first; never send a prohibited category merely because the local model is busy.
- Route by task capability next: define which prompts require long context, tools, current information, or a larger model.
- Set resource thresholds for local readiness, such as free memory, queue length, temperature, and model availability.
- Require user or administrator consent before downloading a model or sending a request to the cloud.
- Display the destination in the interface and record a minimal audit event without retaining the full sensitive prompt.
- Provide a controlled failure mode when neither route is permitted or available.
What are the most common failure modes?
The model fits but is painfully slow
Check for memory pressure, disk swapping, thermal throttling, an unsupported accelerator, an excessive context window, or too many concurrent sessions. Reduce context, use a smaller or appropriately quantized model, close competing applications, or move the workload to hardware designed for sustained inference.
A local server exposes confidential prompts
Many runtimes are convenient on localhost but unsafe when a port is opened to a wider network without authentication. Bind the service narrowly, place it behind an authenticated gateway, encrypt connections, restrict firewall rules, and inspect access logs before allowing remote users.
Do these 3 things before closing this tab:
1Scan for outdated or missing drivers - takes under a minute2Clear out junk files and repair common Windows errors3Fix the driver behind crashes, sound loss and screen glitchesCloud fallback violates policy
Implement a policy check before routing, not after an error. If the local model is unavailable, return a clear message or offer a redacted workflow instead of silently transmitting the original prompt.
Answers differ between local and cloud models
Differences can come from model weights, system prompts, tokenizer behavior, context limits, retrieval sources, tool permissions, and sampling settings. Evaluate both on a fixed test set and tell users which model produced each answer when consistency matters.
Rank #4

- Faster than ever with 5600MHz frequency, new structural composition for better performance.
- Conserve energy with energy-efficient 1.1V working voltage.
- Supports on-die ECC for more stable systems.
- Upgraded capacity for powerful multitasking.
- Lifetime warranty. ※Refer to the latest version on the official website. In case of discrepancies, the official website prevails.
Costs rise unexpectedly
For local systems, inspect utilization, power draw, support time, and replacement assumptions. For cloud systems, inspect token growth, repeated context, file-processing charges, concurrency, retries, and any premium tool or storage fees. Alert on the workload metric that actually drives the bill.
How should an organization govern local and cloud models?
Document ownership for the model, runtime, hardware, credentials, prompts, logs, and incident response. Define approved models and versions, patch deadlines, vulnerability handling, backup and deletion rules, and a process for evaluating a new model before it reaches production.
For cloud use, maintain an inventory of providers, regions, plans, subprocessors, retention settings, and contract terms. For local use, maintain an inventory of devices, exposed endpoints, model files, administrators, and update status. In both cases, test access removal, data deletion, outage behavior, and a compromised-credential scenario.
Review the policy whenever the model, runtime, provider plan, hardware, jurisdiction, or workload changes. A deployment that was acceptable for public text may be unsuitable for source code, customer records, health information, or regulated financial data.
Frequently Asked Questions
Can a local LLM work without an internet connection?
Yes, if the runtime, model files, dependencies, and any required retrieval data are already installed. Disable automatic update and catalog checks for a truly disconnected environment, and create a controlled process for importing security patches and new model versions through removable media or an approved transfer point.
Do quantized local models always give worse answers?
Quantization can reduce memory use and improve throughput, but the quality impact depends on the model, quantization method, prompt, and task. Test the exact quantized build on representative examples; a smaller model that fits entirely in fast memory can outperform a larger model that constantly swaps to disk.
Quick wins for a faster PC:
Clear out junk files and repair common Windows errorsFree Scan →Scan for outdated or missing drivers - takes under a minuteDriver Scan →Can I let coworkers use a model running on my computer?
You can expose it through an authenticated internal service, but a personal workstation is not automatically a reliable server. Define user permissions, encrypt traffic, isolate uploaded files, limit concurrency, monitor resource use, and provide a recovery plan for reboots, updates, and hardware failure.
How often should a local model be updated?
There is no universal interval. Track runtime security advisories and model-specific release notes, test updates against a fixed evaluation set, pin a known-good version in production, and schedule updates when you can roll back without losing prompts, indexes, or configuration.
Quick Recap
Product prices and availability are accurate as of the date/time indicated and are subject to change. Any price and availability information displayed on Amazon at the time of purchase will apply.

