
iTechGuides is reader-supported. When you buy through links on our site, we may earn an affiliate commission. As an Amazon Associate I earn from qualifying purchases. Learn more
Ollama lets you download and run language models on your own computer instead of sending prompts to a hosted service. To use your GPU, install Ollama, install the correct NVIDIA CUDA, AMD ROCm, or Apple Metal driver stack, download a model from Ollama’s current catalog, and start it with ollama run <model>. Ollama chooses an available accelerator automatically; environment variables let you restrict which GPU it can see when several devices are installed or when you need to diagnose CPU fallback.
The practical limits are hardware and storage. NVIDIA support starts at compute capability 5.0 with driver version 550 or newer, AMD support is limited to the Radeon, Radeon Pro, and Instinct devices on Ollama’s current ROCm list, and Apple acceleration uses Metal. Model files can occupy tens or hundreds of gigabytes, so check disk capacity before downloading.
What do I need before running Ollama on a GPU?
You need a supported operating system, a working graphics driver, enough system memory and VRAM for the model you select, and storage for both Ollama and the model files. Ollama provides installers for macOS, Linux, and Windows. GPU support is backend-specific: NVIDIA uses CUDA, supported AMD devices use ROCm, and Apple hardware uses Metal.
The Tool Desk
Outbyte Driver Updater FREEScan for outdated or missing drivers - takes under a minuteDriver Scan →Outbyte PC Repair FREERepair Windows errors before they cause bigger problemsFix Now →- Operating system: Windows 10 version 22H2 or newer, a supported Linux distribution, or a current macOS release compatible with the Ollama installer.
- Graphics driver: Use a current NVIDIA driver for CUDA or the ROCm driver stack for a supported AMD card. Apple acceleration is provided through the operating system’s Metal API.
- Disk space: Windows documentation requires at least 4 GB for the Ollama binary installation. Model downloads are separate and may be tens to hundreds of gigabytes.
- Memory: The model’s quantization, context length, and runtime overhead determine whether it fits in VRAM. If it does not, Ollama can fall back partly or entirely to system memory and become much slower.
- Permissions: You need permission to install software, set user environment variables, and access the GPU device.
There is no single VRAM number that guarantees every model will run. A smaller quantized model may fit on a modest card, while a larger model or a long context can exceed the same card’s capacity. Treat the model’s download size as a lower bound, not as a promise that it will fit in VRAM.
#1 Best Overall
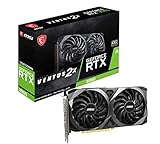
- Strong performance thanks to NVIDIA Ampere with NVIDIA GeForce RTX 3060, 12GB GDDR6, ray tracing and DLSS support
- Display outputs: DisplayPort v1.4a x 3 / HDMI 2.1 x 1
- DUAL FAN COOLING Two fans, combined with a huge heatsink, make the VENTUS series quiet and powerful
- Award winning MSI TORX Fan 3.0 design for high static pressure and effective cooling
- MSI Dragon Center: With just a few clicks, performance can be monitored and optimized in real time
How do I install Ollama on macOS, Linux, or Windows?
Install the package for your operating system, then verify that the command is available. Keep the GPU driver installation separate from Ollama: a successful Ollama installation does not repair a missing or incompatible CUDA or ROCm driver.
macOS and Linux
- Open a terminal.
- Run
curl -fsSL https://ollama.com/install.sh | sh. - On Linux, start the service with
ollama serve. Leave that process running in one terminal. - Open a second terminal and verify the client with
ollama -v.
Linux AMD users may need the additional ROCm package described in Ollama’s Linux installation documentation. Install the package that matches your distribution and driver generation; installing an arbitrary ROCm release can leave the device invisible to Ollama.
Windows
- Open PowerShell with an account that can install applications.
- Run
irm https://ollama.com/install.ps1 | iex. - Confirm that Windows is version 10 22H2 or newer and install current NVIDIA or AMD drivers before testing GPU use.
- Start Ollama from the installed application, then open a PowerShell window and run
ollama run <model>after choosing a model name from the current catalog.
If the command is not recognized immediately after installation, close and reopen the terminal so it reloads the updated PATH. A reboot is also reasonable after a graphics-driver change.
Which GPU backends does Ollama support?
Ollama does not use one universal GPU driver. The vendor and operating system determine the backend, supported device list, and troubleshooting steps.
| GPU family | Acceleration backend | Documented compatibility | Visibility control | Important qualification |
|---|---|---|---|---|
| NVIDIA | CUDA | Compute capability 5.0 or newer; Ollama’s documentation also specifies driver version 550 or newer. | CUDA_VISIBLE_DEVICES |
Check the live supported-card table and driver requirement before buying or upgrading. |
| AMD Radeon, Radeon Pro, and Instinct | ROCm | Only devices on Ollama’s current ROCm support list, on Linux or Windows with the matching driver stack. | ROCR_VISIBLE_DEVICES |
ROCm does not support every AMD GPU; exact model and driver generation matter. |
| Apple silicon and supported Apple systems | Metal | Ollama documents GPU acceleration on Apple devices through Metal. | No CUDA or ROCm variable | The documentation does not set one performance or model-size threshold for every Mac. |
NVIDIA: compute capability and driver version
Ollama’s current GPU documentation states that NVIDIA support starts at compute capability 5.0 and driver version 550 or newer. This is a compatibility floor, not a performance recommendation. A supported older card can run a model, yet deliver a very different experience from a newer card with more VRAM and bandwidth.
A GeForce RTX 3060 with 12 GB is one documented, commonly available option, but support does not imply a fixed model size or token rate. Quantization, context length, system memory, and the rest of the computer determine the result.
AMD: ROCm device and driver matching
AMD acceleration depends on both the exact GPU and the ROCm software stack. Confirm that the model name appears on Ollama’s current Radeon, Radeon Pro, or Instinct list and that your operating system and driver generation are covered. A card that works with a general-purpose graphics driver is not automatically a supported ROCm device.
Quick wins for a faster PC:
Fix the driver behind crashes, sound loss and screen glitchesFind Drivers →Repair Windows errors before they cause bigger problemsFix Now →Scan for outdated or missing drivers - takes under a minuteDriver Scan →Apple: Metal acceleration
On Apple devices, Ollama uses Metal rather than CUDA or ROCm. There is no single published threshold that applies to every Mac, so do not infer a guaranteed model size or tokens-per-second figure from the presence of a Metal-capable GPU. Available unified memory, model quantization, and context length still determine whether a particular model is practical.
How do I download and run a local model?
Model names and tags change as the catalog changes, so select the exact current name shown by Ollama rather than copying an outdated example.
- Open Ollama’s model catalog and choose a model and tag appropriate for your task and hardware.
- Check the displayed download size and leave additional disk space for temporary files and future models.
- Run
ollama run <model>, replacing<model>with the catalog name and tag. Ollama downloads the model if it is not already present, then opens an interactive prompt. - Send a short test prompt and watch for unusually slow generation, an out-of-memory error, or an obvious CPU-only fallback.
- Stop the interactive session with the normal terminal interrupt, then adjust the model, context, storage location, or GPU visibility if the test exposes a limitation.
Use a local model name without a :cloud suffix when you want computation on your computer. Ollama identifies cloud models with the :cloud suffix; those run on Ollama’s servers rather than using your local GPU.
Choosing a model that fits
Model file size, VRAM, system RAM, and context length interact. A quantized model generally requires less memory than a full-precision equivalent, but the exact requirement depends on the model architecture and runtime. Increasing the context window can consume substantial additional memory even when the model file itself fits.
Free tools Windows power users keep installed
One-click scans. No signup required.
Rank #2

- NVIDIA GeForce RTX 3060 12GB GDDR6 dedicated graphics card
- 1710 MHz GPU clock speed and 1807 MHz memory clock speed
- DisplayPort x 3 (v1.4a) and HDMI 2.1 x 1 output interfaces
- 7680 x 4320 maximum display resolution
- Start with a smaller model or shorter context when validating a new installation.
- Prefer a quantization that fits comfortably rather than one that leaves only a few hundred megabytes free.
- Keep enough system RAM for the operating system and other applications if Ollama must offload layers from VRAM.
- Do not treat download size as the maximum memory requirement; runtime buffers and context are additional.
How can I force Ollama to use a particular NVIDIA GPU?
Set CUDA_VISIBLE_DEVICES before starting Ollama or the command that launches it. The variable accepts a comma-separated list, allowing one or more visible devices.
Identify the device
Run nvidia-smi -L. The output includes each GPU’s UUID. UUIDs are more reliable than numeric ordering because device numbers can change when hardware, drivers, or process environments change.
Restrict visibility
In a Linux shell, for example, use CUDA_VISIBLE_DEVICES=GPU-xxxxxxxx-xxxx-xxxx-xxxx-xxxxxxxxxxxx ollama run <model>, replacing the placeholder with the UUID printed by nvidia-smi -L. To expose two selected devices, separate their identifiers with a comma. On Windows PowerShell, set the variable for the session with $env:CUDA_VISIBLE_DEVICES="0" before running Ollama, or use the relevant UUID value supported by your driver tools.
Set the variable before the Ollama process starts. If Ollama is already running as a background service, stop and restart that service after changing the variable; changing a shell variable cannot retroactively move an existing process.
Use an invalid ID to test CPU fallback
For diagnosis, Ollama’s GPU documentation recommends using an invalid GPU ID to force a CPU-only path. If the same model runs, albeit slowly, with the invalid ID but fails with the intended GPU visible, the problem is likely in GPU detection, the driver, or memory capacity rather than the model command itself. Restore a valid device selection after testing.
How can I select an AMD GPU or verify ROCm?
Use rocminfo to enumerate ROCm devices, then set ROCR_VISIBLE_DEVICES to the device you want Ollama to see.
- Install the ROCm version and driver combination supported for your exact AMD GPU and operating system.
- Run
rocminfoand note the device identifiers. - Set
ROCR_VISIBLE_DEVICESbefore launching Ollama, using the identifier for the desired device. - Run a small model first. If it fails, remove the visibility restriction and test again to distinguish a bad device ID from a broader ROCm problem.
If rocminfo cannot see the card, Ollama cannot use it through ROCm. Recheck the supported-device list, kernel or Windows driver, permissions, and the additional ROCm package required by some Linux installations before changing model settings.
How do I move Ollama’s model files to another drive?
Move the model directory when the system drive is too small. Windows documentation recommends setting the user-level OLLAMA_MODELS environment variable to the destination, then restarting Ollama.
What’s actually slowing this PC down?
Pick the symptom - the matching free tool is one click away.
- Create a destination folder on a drive with sufficient free space, such as a dedicated models directory.
- In Windows, open the Environment Variables dialog, edit the user variable named
OLLAMA_MODELS, and enter the full destination path. Do not add quotation marks to the value. - Apply the change and restart the Ollama application or service. A newly opened terminal alone does not restart an already running Ollama process.
- Run a model and confirm that new data is written to the destination before deleting any old copies.
On Linux or macOS, set OLLAMA_MODELS in the environment used to launch the Ollama service, then restart that service. Keep the path on a local, writable filesystem with enough capacity for multiple model versions. Model downloads can reach tens or hundreds of gigabytes, so measure free space against the catalog’s displayed size rather than assuming the binary’s 4 GB requirement covers everything.
Why is Ollama using the CPU instead of my GPU?
CPU fallback usually means the device is not visible, the driver/backend is unsupported, or the model cannot fit in available accelerator memory. Work through the checks in order instead of immediately reinstalling Ollama.
1. Confirm the operating system and driver
- On Windows, verify Windows 10 22H2 or newer.
- For NVIDIA, check the driver version and compute capability against Ollama’s current table; the documented floor is compute capability 5.0 with driver 550 or newer.
- For AMD, verify the exact GPU and ROCm generation, not merely that the card is made by AMD.
- On Apple hardware, confirm that the system supports Metal and that Ollama is running natively for the machine rather than through an incompatible translation layer.
2. Check that the vendor tool sees the device
Use nvidia-smi -L for NVIDIA or rocminfo for AMD. An empty result indicates a driver or permissions problem outside the model command. Fix that first.
Rank #3

- NVIDIA Ampere Streaming Multiprocessors
- 2nd Generation RT Cores
- 3rd Generation Tensor Cores
- Powered by GeForce RTX 3060
- Integrated with 12GB GDDR6 192-bit memory interface
3. Remove an accidental visibility restriction
Inspect CUDA_VISIBLE_DEVICES or ROCR_VISIBLE_DEVICES. An empty value, an incorrect UUID, or an invalid index can hide every GPU. Clear the variable and restart Ollama, then test again.
4. Test with a smaller workload
Run a smaller quantized model or reduce the context length. If that succeeds while the larger model falls back, the installation may be healthy but the workload exceeds VRAM or system-memory limits.
5. Separate GPU failure from model failure
Force CPU mode with an invalid GPU ID as a diagnostic comparison. A CPU run confirms that the model and command are valid; it does not prove that the GPU is configured correctly.
Independent reader supportYour contribution helps us test, update, and keep practical guides available for everyone.How much GPU memory and storage should I plan?
Plan capacity from the model catalog and your intended context, not from a generic “models per GPU” chart. Ollama’s documentation gives a storage warning—model files can be tens to hundreds of gigabytes—but does not publish one universal VRAM requirement for all models.
| Resource | What consumes it | Planning rule |
|---|---|---|
| GPU VRAM or Apple unified memory | Model weights, runtime buffers, and part of the context. | Leave headroom; a model that barely fits may fail when the context grows. |
| System RAM | Operating system, applications, and any layers offloaded from the GPU. | Reserve memory for normal desktop use instead of assigning all of it to Ollama. |
| Disk | Ollama binary, downloaded model files, alternate tags, and temporary data. | Windows requires at least 4 GB for the binary; allow tens to hundreds of GB for models. |
| Network allowance | Initial model downloads and updates. | Download over a reliable connection and avoid starting several very large downloads at once. |
Keeping several tags of the same model can multiply storage use. Delete or relocate models only after confirming that no application or workflow still depends on them.
What setup is best for a first local Ollama deployment?
Choose the backend you can verify and maintain, then start with a model that leaves memory headroom. A supported NVIDIA card with a current driver is often the simplest cross-platform path because CUDA device inspection is straightforward, but AMD and Apple systems can work well when the exact ROCm or Metal conditions are met.
- Choose NVIDIA when you want CUDA tooling, multiple-GPU selection with
CUDA_VISIBLE_DEVICES, and a card on Ollama’s supported list. - Choose AMD when your exact Radeon, Radeon Pro, or Instinct model is listed and you are prepared to maintain the matching ROCm stack.
- Choose Apple when you already own a Metal-capable Mac and value a unified-memory setup; measure the chosen model rather than assuming a universal size or speed.
- Use CPU mode temporarily when validating commands or diagnosing drivers, but expect large models to be slow without a strong GPU.
After installation, validate the stack with a small local model, confirm the intended device is visible, and only then download larger models or move the model directory. That sequence isolates driver, storage, and model-size problems before they become difficult to diagnose.
Frequently Asked Questions
Can Ollama run if I do not have a supported GPU?
Yes. Ollama can run a model on the CPU, although generation is generally much slower, especially for large models. CPU mode is useful for checking that installation and model downloads work before you troubleshoot acceleration.
How do I know whether a model download will fit on my drive?
Use the size shown for the exact model tag in Ollama’s catalog and compare it with free space on the destination drive. Keep additional room for other tags, temporary files, and future updates; the displayed model size is not the only disk usage.
Recommended Free Tools
Does an external GPU guarantee acceleration on a Mac?
No universal guarantee is documented. Ollama describes Apple acceleration through Metal, but compatibility and performance depend on the specific Mac, operating-system support, memory configuration, and model.
Why does changing CUDA_VISIBLE_DEVICES appear to do nothing?
The variable affects processes started after it is set. If Ollama is already running as a background application or service, stop and restart that process before testing the new device selection.
Quick Recap
Product prices and availability are accurate as of the date/time indicated and are subject to change. Any price and availability information displayed on Amazon at the time of purchase will apply.

