
What’s actually slowing this PC down?
Pick the symptom - the matching free tool is one click away.
iTechGuides is reader-supported. When you buy through links on our site, we may earn an affiliate commission. As an Amazon Associate I earn from qualifying purchases. Learn more
CoreWeave has the lowest listed price in the available eight-H100 comparison, but that does not prove it is the cheapest or fastest place to run your workload. A September 2026 third-party snapshot lists an eight-H100 node at $49.24 per hour on CoreWeave, versus $55.04 on AWS, $88.49 on Google Cloud, and $98.32 on Azure. The bundles are not identical, and the available sources do not establish a controlled performance winner, live capacity advantage, queue-time advantage, or provisioning-time advantage. Use the figures as a dated price reference, then compare identical GPU counts, host resources, regions, software, checkpointing, and completion targets before committing spend.
What does the current CoreWeave versus major-cloud price comparison show?
The clearest public comparison is a dated eight-H100 node snapshot checked in September 2026. It reports CoreWeave at $49.24 per hour, AWS at $55.04, Google Cloud at $88.49, and Azure at $98.32. On the face of that table, CoreWeave is about 10.5% below AWS, 44.4% below Google Cloud, and 49.9% below Azure. Those percentages are arithmetic on the reported hourly figures, not a total-cost or performance ranking.

| Provider | Reported eight-H100 node price | Price snapshot | How to interpret it |
|---|---|---|---|
| CoreWeave | $49.24/hour | iTechGuides, checked September 2026 | Lowest listed figure in this comparison; the bundle is not identical to the other providers’ nodes. |
| AWS | $55.04/hour | iTechGuides, checked September 2026 | About $5.80/hour above CoreWeave in the snapshot; CPU, memory, storage, networking, region, and scheduling differ. |
| Google Cloud | $88.49/hour | iTechGuides, checked September 2026 | About $39.25/hour above CoreWeave in the snapshot; do not treat this as a matched-instance benchmark. |
| Azure | $98.32/hour | iTechGuides, checked September 2026 | About $49.08/hour above CoreWeave in the snapshot; the reported node configuration and commercial terms are different. |
The comparison itself cautions that the nodes differ in CPU, system memory, local storage, networking, region, and scheduling terms. A lower rental rate therefore cannot establish a lower cost per trained token, completed fine-tune, inference request, or successful run.
What GPU prices does CoreWeave publish?
CoreWeave’s pricing page, accessed October 25, 2026, publicly lists North American and European configurations. The following North America entries are the most useful reference points for an eight-GPU comparison.
| Configuration | On-demand rate | Spot rate | Pricing context |
|---|---|---|---|
| HGX H100, eight GPUs | $49.24/hour | $19.71/hour | Public North America listing; confirm current regional price and terms before purchase. |
| HGX H200, eight GPUs | $50.44/hour | $20.93/hour | Public North America listing; the H200 rate is for a different accelerator configuration than H100. |
| A100 configuration | $21.60/hour | $9.65/hour | Public North America listing; GPU count and full host bundle must be checked in the live listing. |
Some systems on the same page are sales-led rather than openly priced. Public pricing means that a rate is published; it does not mean that the required capacity is available to your account at the moment you request it. Regional taxes, storage, data-transfer charges, support, committed-use terms, and any account-specific conditions can change the invoice.
The page also states that GPU-based pricing for inference applies exclusively to CoreWeave inference-platform customers and directs prospective users to an account executive. Do not apply the general training-node numbers to an inference service without confirming that eligibility and the applicable rate card.
How do CoreWeave’s prices compare with per-GPU compilations?
A StackPath compilation dated October 18, 2026 lists CoreWeave per-GPU figures of $6.16 per hour for H100, $6.30 for H200, $8.60 for B200, $10.50 for GB200, and $2.70 for A100. These are compiled figures, not independent workload measurements. Multiplying the H100 per-GPU figure by eight gives approximately $49.28 per hour, close to the $49.24 eight-GPU node listing, but the small difference does not make the two sources interchangeable.
The compilation is useful for discovering which accelerator families may have public rates. It is not a complete market average: its script omitted Google Cloud because it could not read a public price list without a key, and it covers multiple vendors with different definitions of a billable GPU, host, region, and commitment. Treat each number as a dated lead that needs confirmation in the provider’s console or quote.
Why does the lowest hourly GPU price not prove the lowest training cost?
Training cost is the product of price and elapsed billable time, adjusted for interruptions, utilization, retries, storage, data movement, and any software or support charges. A cheaper node that trains 25% slower can cost more than a higher-priced node that finishes sooner; a spot node that is interrupted repeatedly can cost more than a stable on-demand run.
For a first-pass estimate, calculate:
Total run cost = (node hourly rate × billable hours) + storage + data transfer + ancillary services + retry cost
For example, 100 uninterrupted hours on the listed CoreWeave HGX H100 node would be $4,924 on demand or $1,971 at the listed spot rate, before storage, transfer, taxes, and retries. Those are arithmetic illustrations, not a promise that a job will complete in 100 hours or that spot capacity will remain uninterrupted.
Crashes, No Sound, or Screen Glitches?
Random freezes, missing sound and display glitches usually trace back to one bad driver. Find and replace yours safely.Free scan · under a minuteWindows Errors? Fix Them Before They Spread
Repair common Windows errors and clear accumulated junk for a smoother, more stable PC - no reinstall needed.Free scan · no reinstallRank #2
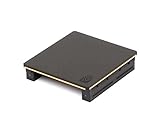
- Part number 900-53651-2500-000 and model: P3651
- This is the 2 slot version for when there is no empty slots between 2 slot cards. If you have one or more empty slots between the cards or the cards are 3 slot this NVLink will not work. See the attached images showing the card layout.
- NVLink 3.0 for any brand of RTX Ampere model graphics cards: 3090, A30, A40, A100 / H100 (Requires three NVLinks), A800, A4500, A5000, A5500, A6000
- This is the same as PNY part number: NVLAMP-2SLOT-BSP and RTXA6000NVLINK-KIT
- This is the same as Dell part number: 0RWJ7Y
Make the comparison at the workload level. Record tokens processed, samples per second, time to a target validation loss, checkpoint frequency, failed-step recovery time, and total wall-clock time. For inference, record requests per second, tail latency, batching policy, output quality, and the cost of keeping replicas warm. Without those measurements, hourly price is only an input.
Are the eight-H100 nodes actually equivalent?
No. The published comparison explicitly warns that the bundles are not identical. Before interpreting a price difference, normalize the following attributes:
- Accelerator: exact GPU model, memory capacity, interconnect topology, and whether all eight GPUs are in one tightly coupled host.
- CPU and host memory: vCPU count, processor generation, RAM capacity, NUMA layout, and whether CPU oversubscription is possible.
- Local storage: boot volume, scratch NVMe capacity, sustained read/write performance, and whether checkpoint storage is local or network-attached.
- Networking: internal bandwidth, RDMA support, topology across nodes, packet limits, and egress pricing.
- Region and locality: physical region, availability zone, data-residency requirements, latency to your dataset, and cross-region transfer.
- Scheduling: on-demand versus spot or preemptible allocation, reservation windows, maximum run duration, and interruption notice.
- Software image: driver, CUDA, framework, communication library, container runtime, and kernel versions.
If one provider’s “eight-GPU node” includes more CPU, faster networking, or local NVMe, its higher hourly rate may buy a shorter run. Conversely, if your job is GPU-bound and insensitive to host resources, those extras may have little value.
Which provider has better GPU availability and provisioning time?
The available pricing pages do not establish a live availability winner. They contain public rates, not an account-specific capacity feed, queue-time dataset, or controlled measurement of provisioning speed. A listing can remain visible while a particular region, GPU type, or quota is exhausted.
Recommended Free Tools
Check capacity at the time and place you will run:
- Choose the exact GPU, count, region, and tenancy model.
- Verify that your account has the required quota and that the requested shape appears as allocatable, not merely documented.
- Record the timestamp, queue delay, provisioning duration, and any capacity error.
- Repeat the check during the hours and days when your production jobs normally launch.
- Test a smaller allocation and a full-size allocation; capacity can differ sharply by shape.
- Ask sales or support about reservations, minimum commitments, maintenance windows, and replacement capacity if the workload is time-critical.
For a fair comparison, run the same launch script in each provider’s target region and save the timestamps. A single successful launch is not a capacity guarantee, so collect several observations or obtain a written reservation.
How should performance be compared across CoreWeave, AWS, Google Cloud, and Azure?
No controlled cross-provider benchmark is established by the available sources. Performance must therefore be measured against your own workload rather than inferred from the price table or the provider name.
Define one reproducible workload
Pin the model or training code revision, dataset shard, sequence length, batch size, precision, optimizer, checkpoint interval, and quality target. Use the same container or rebuild equivalent environments with the same CUDA and framework versions. Capture both steady-state throughput and the time needed to reach the target quality.
Rank #3
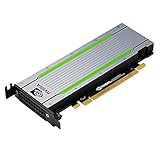
- Video/Sound Cards
- Passive Cooling
Measure the bottleneck, not just GPU utilization
Log GPU utilization, memory use, host CPU load, data-loader wait time, storage throughput, inter-GPU communication, network traffic, and synchronization stalls. High GPU utilization can hide inefficient input pipelines; low utilization can reflect a CPU, storage, or network bottleneck that a different node would solve.
Quick wins for a faster PC:
Scan for outdated or missing drivers - takes under a minuteDriver Scan →Clear out junk files and repair common Windows errorsFree Scan →Fix the driver behind crashes, sound loss and screen glitchesFind Drivers →Include failure and recovery behavior
Measure checkpoint write time, restart time, lost work after interruption, and the success rate of repeated launches. Spot pricing is only useful if your application can tolerate eviction and resume predictably. For inference, include warm-up time, autoscaling delay, tail latency, and the quality impact of quantization or batching.
Report cost per completed objective
Publish the provider, region, GPU count, host specification, software versions, measured wall-clock time, interruptions, and all billable services. Then calculate cost per completed training run, million tokens, or million successful requests. This prevents a favorable hourly number from masking slower convergence or repeated retries.
When is on-demand, spot, or committed capacity the right choice?
| Pricing mode | Best fit | Main risk | Controls to use |
|---|---|---|---|
| On demand | Interactive development, deadlines, and jobs that cannot be interrupted. | Highest listed hourly price and possible quota or regional scarcity. | Set budgets, monitor utilization, and keep checkpoints even when interruption is unlikely. |
| Spot or preemptible | Checkpointed training, batch inference, and experiments that can retry. | Eviction, changing availability, and variable completion time. | Frequent durable checkpoints, automatic resume, retry limits, and a fallback capacity plan. |
| Committed or reserved | Predictable, sustained usage with a stable region and GPU model. | Paying for unused capacity or being locked into a shape that later becomes unsuitable. | Use only after measuring utilization and confirming exit, exchange, and regional terms. |
CoreWeave’s listed H100 spot rate is roughly 60% below its on-demand rate ($19.71 versus $49.24 per hour), while the H200 spot rate is about 58.5% below its on-demand rate ($20.93 versus $50.44). Those discounts compensate for interruption risk; they are not guaranteed savings on a completed project.
How do GPU model and memory change the decision?
An H100, H200, A100, B200, and GB200 are not interchangeable merely because each is marketed for AI workloads. Memory capacity can determine whether a model fits without sharding or offload; memory bandwidth and interconnect affect attention-heavy training; and newer accelerators may reduce elapsed time enough to offset a higher hourly rate.
Free tools Windows power users keep installed
One-click scans. No signup required.
- H100: a common reference point for the eight-GPU comparison; validate memory, interconnect, and host details for the exact node.
- H200: listed by CoreWeave at $50.44/hour on demand and $20.93/hour spot for its North America HGX configuration; choose it when its memory characteristics match the model and software stack.
- A100: listed by CoreWeave at $21.60/hour on demand and $9.65/hour spot; it may suit models that fit comfortably in its memory and do not benefit enough from newer hardware to justify the premium.
- B200 and GB200: the StackPath compilation lists CoreWeave per-GPU figures of $8.60 and $10.50 per hour respectively as of October 18, 2026. Confirm whether the quoted unit is available as the multi-GPU topology your workload requires.
Do not compare a per-GPU number with a complete node number until you know whether CPU, memory, storage, networking, and management fees are included. For distributed jobs, topology and communication performance can matter more than the nominal accelerator generation.
Independent reader supportYour contribution helps us test, update, and keep practical guides available for everyone.What regions and data-transfer costs should be checked?
CoreWeave publishes configurations across North American and European regions, but the appropriate region depends on data residency, user latency, dataset location, and legal requirements. A lower rate in a distant region can be erased by moving terabytes of training data or serving users across an ocean.
Rank #4

- CUDA Cores: 4608 / NVIDIA Tensor Cores: 576 / NVIDIA RT Cores: 72
- GPU Memory: 24 GB GDDR6 with ECC / Bandwidth: 624 GB/Sec
- System Interface: PCI Express 3.0 x16
- Four DisplayPort 1.4 Connectors
- 3D Stereo Support with Stereo Connector
For each provider, write down the region and availability zone, dataset location, object-storage rate, intra-region and inter-region transfer charges, egress policy, and backup location. Keep data and compute in the same region when possible, and test the actual input pipeline rather than assuming that advertised network bandwidth equals application throughput.
What is a defensible provider-selection process?
- Define the objective: target quality, deadline, throughput, latency, or maximum budget.
- Choose a matched shape: same GPU model and count, or document why a different model is expected to achieve the same objective.
- Normalize the bundle: CPU, RAM, local storage, networking, region, software, and billing mode.
- Run a short benchmark: long enough to capture warm-up, steady state, checkpointing, and representative data loading.
- Test capacity: launch repeatedly at realistic times and record quota, queue, provisioning, and interruption behavior.
- Calculate workload cost: include elapsed time, retries, storage, transfer, support, and idle periods.
- Stress the failure path: terminate a spot job or simulate a node loss, then verify automatic recovery and data integrity.
- Set a fallback: maintain a second region or provider if the deadline or service-level objective cannot tolerate a capacity shortfall.
This process can produce a different winner for training, fine-tuning, batch inference, and low-latency serving. The right answer is the provider that meets the stated objective at the lowest risk-adjusted cost, not necessarily the provider with the lowest published rate.
The Tool Desk
Outbyte PC Repair FREEClear out junk files and repair common Windows errorsFree Scan →Outbyte Driver Updater FREEFix the driver behind crashes, sound loss and screen glitchesFind Drivers →What pitfalls can invalidate a cloud-GPU comparison?
- Mixing dates: pricing changes frequently. Put the access date beside every figure; the CoreWeave figures above were accessed October 25, 2026, while the cross-provider snapshot was checked in September 2026.
- Comparing unlike units: an hourly GPU, a complete eight-GPU node, and a managed inference endpoint can include very different resources.
- Ignoring interruption cost: spot savings disappear when checkpoints are infrequent or recovery is manual.
- Counting idle time as performance: include image pulls, environment setup, data staging, and teardown in a production cost estimate.
- Assuming public means available: quota, regional stock, and account approval can block an otherwise published configuration.
- Using a vendor-neutral benchmark that is not workload-neutral: a benchmark optimized for one framework, batch size, or communication pattern may not predict your result.
- Omitting data movement: transfer and storage can dominate a short inference job or a dataset that is repeatedly copied.
What can you conclude today?
CoreWeave is the price leader in the available eight-H100 snapshot, and its public North America rate card provides unusually concrete on-demand and spot figures for H100, H200, and A100 configurations. That is enough to justify a benchmark or quote request, not enough to declare a universal winner. The evidence does not establish which provider has better live capacity, faster provisioning, higher training throughput, lower cost per token, or superior reliability.
Use the published rates to build an initial budget, then validate a matched workload in the region and scheduling mode you will actually use. Keep the timestamp, node specification, software stack, and recovery results with the benchmark so that a future price change does not silently invalidate the decision.
Frequently Asked Questions
Can I lock in the listed CoreWeave price for a long project?
Not from the public rate alone. Ask CoreWeave for the applicable reservation or committed-use terms, including duration, minimum spend, regional restrictions, GPU substitution rules, and what happens if capacity is unavailable.
How much checkpointing is practical for spot training?
Choose an interval based on the cost of recomputing lost work and the time required to write a durable checkpoint. Test restoration on a fresh node, because a checkpoint that exists but cannot be loaded quickly can erase much of the advertised spot savings.
Why might a higher-priced GPU finish a job more cheaply?
Faster kernels, larger memory, better interconnects, or a less constrained input pipeline can reduce billable hours. Compare cost to the same quality or completion target rather than comparing hourly rates in isolation.
Should data residency affect the provider decision?
Yes. A region that satisfies residency rules and keeps data near compute can avoid transfer charges and reduce latency. Document the exact region and backup location in the benchmark record; a multi-region label is not specific enough for compliance or cost analysis.
Quick Recap
Product prices and availability are accurate as of the date/time indicated and are subject to change. Any price and availability information displayed on Amazon at the time of purchase will apply.

