
What’s actually slowing this PC down?
Pick the symptom - the matching free tool is one click away.
iTechGuides is reader-supported. When you buy through links on our site, we may earn an affiliate commission. As an Amazon Associate I earn from qualifying purchases. Learn more
AI inference costs are driven mainly by how often your application calls a model, how many input and output tokens each call uses, which model handles it, and how quickly and reliably the service must respond. For self-hosted models, add GPU capacity and utilization, power, storage, networking, and the engineering needed to operate the system. The most dependable way to cut costs is to measure spend by task, then reduce unnecessary model work without sacrificing answer quality or acceptable latency.
What counts as an AI inference cost?
Inference is the work of using a trained model to answer a prompt, classify a record, generate text, create an embedding, or perform another task. The bill is not necessarily just a model’s advertised price per token: a production feature may also incur retrieval, storage, networking, monitoring, and serving costs.

For a managed API, a useful starting model is:
Cost per successful task = (model charges + related infrastructure charges) ÷ successful tasks completed
Free tools Windows power users keep installed
One-click scans. No signup required.
This is more informative than cost per request. A request that fails, triggers a retry, or produces an unusable result still consumed resources. For an agent that makes several model calls before finishing one task, count those calls together. For self-hosting, include the cost of capacity whether or not it is busy; an idle GPU still contributes to the total cost of operating the service.
#1 Best Overall

- NVIDIA Volta GV100 Architecture — 4,608 CUDA Cores, 640 1st-Gen Tensor Cores delivering 14 TFLOPS FP32 and 112 TFLOPS deep learning performance for AI training, inference, HPC, and scientific computing workloads
- 32GB HBM2 ECC Memory — 900 GB/s Bandwidth — High-bandwidth memory on a 4096-bit bus with ECC error correction provides the memory capacity and throughput required for the largest AI models, simulations, and datasets
- PCIe 3.0 x16 Interface — 250W TDP — Standard PCIe Gen3 connectivity with passive cooling designed for enterprise rack server deployment in HPE ProLiant, Dell PowerEdge, and Supermicro platforms with adequate chassis airflow
- NVLink — Scale to 96GB Unified Memory — Connect two V100 GPUs via NVLink at 300 GB/s bi-directional bandwidth to scale GPU memory from 32GB to 96GB for larger AI training and HPC workloads
- Multi-Precision Computing — Supports FP64 (7 TFLOPS), FP32 (14 TFLOPS), FP16 (112 TFLOPS) and INT8 precision modes for flexible deployment across training, inference, and scientific simulation workloads
There is no universal industry-wide cost per token or savings percentage that applies across providers, models, workloads, and service tiers. Published discounts and savings are useful for identifying options to test, not guarantees of what a particular application will save.
What drives the bill the most?
The main drivers are model choice, token volume, the number of calls per task, service guarantees, and—when you host the model—how efficiently you use the hardware. Costs outside the model can also matter, especially for retrieval-heavy applications or workloads that move large amounts of data.
Model tier and token volume
More capable or premium models generally cost more per token than smaller models. A long system prompt, tool definitions, retrieved documents, and chat history all add input tokens; a long answer adds output tokens. If an application sends the same background instructions and conversation history on every turn, repeated context can become a material cost even when the user’s new question is short.
The Tool Desk
Outbyte Driver Updater FREEScan for outdated or missing drivers - takes under a minuteDriver Scan →Outbyte PC Repair FREEClear out junk files and repair common Windows errorsFree Scan →Calls per completed task
A simple question-and-answer feature may use one model call. An agent may make additional calls to plan, retrieve information, choose a tool, interpret tool results, and produce a final answer. Retries and fallback calls add more work too. In those cases, request volume alone understates demand: measure calls and tokens per successful task.
Latency and reliability requirements
Some managed services offer different processing tiers. Lower-cost asynchronous or interruptible processing can suit work that does not have to finish immediately, while a higher-priority tier may be appropriate when responsiveness matters more than price. Compare the actual service terms: lower cost can come with longer waits, rate limits, or the possibility that work is deferred or interrupted.
Hardware and supporting infrastructure
With self-hosting, accelerator memory and memory bandwidth, utilization, concurrency, and idle capacity shape the economics. Quantization may allow a model to fit on a smaller or less expensive GPU, but quality and throughput still need to be checked on the target workload. Vector search, model storage, artifact registries, observability, networking, and cross-region data egress can add costs around the inference server.
How large can the non-model costs be?
Microsoft Azure’s 2026 cost-driver guidance gives typical bill-share ranges for several parts of an LLM workload. These are guidance ranges, not a universal breakdown: actual shares depend on architecture, volume, region, and the provider’s billing model.
Quick wins for a faster PC:
Scan for outdated or missing drivers - takes under a minuteDriver Scan →Repair Windows errors before they cause bigger problemsFix Now →| Cost category | Typical bill share in Azure’s 2026 guidance | What can drive it |
|---|---|---|
| LLM API tokens | 30–60% | Model tier, input and output token counts, and number of calls |
| GPUs | 20–50% | Accelerator capacity, utilization, concurrency, and idle time |
| Vector search | 5–20% | Retrieval workload and search infrastructure |
| Storage | 3–10% | Models, artifacts, data, and related services |
| Egress | 2–15% | Data transferred out, including across regions |
Those ranges should not be added together as if they describe one representative bill: they are separate typical ranges, and the source does not establish that every workload has each cost or that all categories will land at the high or low end. Use your own billing records to identify which categories exist in your deployment and which ones are material.
Is a managed API cheaper than running your own GPUs?
Neither option is inherently cheaper. An API usually avoids buying and operating accelerators, while self-hosting can make sense when sustained, predictable usage keeps hardware well utilized and the team can manage serving reliably. Compare total cost per useful completed task at your expected scale, not a token price against a GPU rental price.
| Decision factor | Managed API | Self-hosted model |
|---|---|---|
| What you pay for | Provider charges such as model tokens, service tier, and any related services | GPU purchase or rental, memory capacity, power, storage, networking, idle capacity, and operations |
| Minimum practical scale | Can start without operating a GPU fleet; total cost depends on usage and provider pricing | Depends on serving setup, capacity needs, utilization, and whether hardware is purchased or rented; no universal break-even volume is established |
| Latency and tail latency | Depends on model, region, service tier, rate limits, and provider behavior | Depends on hardware, serving runtime, queueing, load, and operations |
| Throughput | Depends on provider limits, tier, model, and request pattern | Depends on accelerator memory and bandwidth, concurrency, batching, and serving configuration |
| Reliability and interruptions | Read service-specific availability, rate-limit, and preemption terms | Your team operates capacity, scaling, and recovery; low-cost or spot capacity can be interrupted |
| Quality and model choice | Choose among models the API provider makes available | Choose and operate a model that fits the hardware and task, with responsibility for testing it |
| Engineering effort | Less accelerator operations work, though integration, evaluation, and cost controls remain necessary | More responsibility for deployment, optimization, scaling, monitoring, and recovery |
| Portability and privacy | Review provider-specific model, data-handling, and regional terms | More control over deployment location and serving stack, alongside more operational responsibility |
For an API comparison, include the exact model, input and output token rates, caching eligibility, batch options, region, rate limits, support tier, and expected request pattern. For self-hosting, include accelerator memory and bandwidth, utilization assumptions, serving-runtime maturity, autoscaling, and the measured quality impact of any precision reduction. The available evidence does not establish a general API-versus-GPU break-even point.
When an API is a sensible starting point
- Traffic is low, spiky, or still uncertain, so owning or reserving GPU capacity could leave expensive idle time.
- You need a managed model quickly and do not have a team ready to operate inference infrastructure.
- The provider offers a suitable model and service tier, and usage-based billing matches the workload.
When self-hosting merits a cost test
- Demand is steady enough to keep the required hardware productively occupied.
- You need control over the model, serving stack, or deployment environment that an API does not provide.
- Your team can measure and maintain quality, throughput, reliability, scaling, and recovery—not just get a model running once.
How do API tiers, caching, and batching change the price?
Managed services can discount work that is reusable or does not need immediate completion, and charge more for higher-priority processing. The savings are provider- and service-specific, so check the applicable model, region, request type, and terms before using a published percentage in a forecast.
| Option | Documented figure | Important qualification |
|---|---|---|
| Google Flex inference | 50% of standard price | Google documentation from 2026; check service eligibility and current terms. |
| Google Batch API processing | 50% of standard price | Google documentation from 2026; asynchronous processing is intended for work that can wait. |
| Google context caching | 90% discount, plus prorated token storage | Google documentation from 2026; the discount concerns eligible cached context, and storage is charged separately. |
| Google Priority inference | 75–100% above standard rates | Google documentation from 2026; this is a premium over standard rates, not a discount. |
These figures are documented examples, not an apples-to-apples price list across providers. In particular, a 90% caching discount should not be read as a 90% reduction in the whole application bill: it applies to eligible cached context, while uncached inputs, outputs, storage, and other charges remain relevant.
Rank #3

- Colour: brown
- Brand: Nvidia
- Packed with features
- Best product in its class
Use caching when the work is genuinely repeated
Provider prompt or context caching can reduce charges for repeated prefixes, such as stable instructions or shared reference material, when the provider supports caching for that workload. It is most useful when the same context is sent repeatedly and cache behavior, minimum sizes, retention, and pricing fit the request pattern. Separately, an application-level response or semantic cache can reuse an earlier answer for a sufficiently similar request, but only when stale results and the privacy implications are acceptable.
Use batch processing when time is flexible
Batch processing is suited to offline evaluations, embedding refreshes, summarization jobs, and index-building tasks when immediate results are unnecessary. Its lower price is only useful if the workload’s deadline can tolerate asynchronous completion and its error handling can cope with delayed results. Keep interactive traffic on a path that meets its latency needs rather than sending it into a cheaper tier indiscriminately.
How can you reduce inference costs without degrading answers?
Start with measurement and quality thresholds, then optimize the largest avoidable source of spend. This order helps distinguish a real saving from a lower bill that simply reflects failed tasks, slower responses, or poorer answers.
Crashes, No Sound, or Screen Glitches?
Random freezes, missing sound and display glitches usually trace back to one bad driver. Find and replace yours safely.Free scan · under a minuteWindows Errors? Fix Them Before They Spread
Repair common Windows errors and clear accumulated junk for a smoother, more stable PC - no reinstall needed.Free scan · no reinstall- Attribute costs to real work. Tag usage by feature, model, endpoint, workflow, tenant, environment, and team. Track spend per active user and per successful task alongside request volume and token use.
- Set acceptance limits. Define the quality, p95 and p99 latency, throughput, error-rate, and reliability requirements each workflow must meet. Evaluate cost per useful answer against those measures, rather than selecting the cheapest configuration by itself.
- Find expensive paths. Identify which features consume the most tokens, make the most calls, retry most often, or spend most on supporting services. Inspect both the typical path and cases that trigger retrieval, tool use, or escalation.
- Route routine work to the smallest adequate model. Try cheaper models first for classification, extraction, routing, and boilerplate, and escalate uncertain or higher-value cases. Microsoft Azure’s 2026 guidance describes routing 60–80% of traffic to a cheaper model as a pattern that can work without measurable quality loss on routine queries; that is not a guaranteed target. Validate routing on your own evaluations and monitor failure rates after deployment.
- Remove unnecessary tokens. Shorten redundant system prompts and tool descriptions, retrieve only relevant material, cap answer length to what the feature needs, and avoid resending unchanged history where the API or application design permits. Check that trimming does not remove instructions or evidence needed for a correct answer.
- Reuse work safely. Apply provider caching to eligible repeated prompt prefixes and consider application-level caches for repeat requests. Put a clear policy around freshness, invalidation, user-specific information, and sensitive data before reusing responses.
- Move flexible jobs to batch. Batch work such as offline evaluations, embedding refreshes, and summarization when the deadline allows. Confirm that the batch tier’s completion behavior and failure handling fit the job.
- Optimize the serving path. For self-hosting, test quantization, compilation, efficient serving runtimes, and batching against representative prompts and concurrency. Change one important factor at a time where practical so regressions and throughput gains can be attributed.
- Right-size and scale capacity. Match GPU memory to the model and context length, measure real utilization, and scale replicas with demand. Noninteractive, restartable workloads may be suitable for scaling toward zero or using interruptible capacity, provided restart and recovery costs are included.
- Recheck the whole outcome. Compare cost per successful task, not just cost per token or GPU-hour. Keep the change only if it meets quality, latency, throughput, error-rate, and reliability requirements.
What do quantization and serving optimizations save?
Quantization stores or computes model values at lower numerical precision, which can reduce memory requirements and sometimes improve the amount of work a GPU can handle. NVIDIA’s 2026 technical guidance says quantization can reduce memory by 25–50% without retraining; that is a vendor technical estimate, not a promise of a matching bill reduction or unchanged quality for every model.
Lower memory use can make a model fit on a smaller accelerator, leave more memory for longer context or concurrent requests, or reduce the need for multiple GPUs. Which outcome lowers cost depends on the bottleneck: reducing memory alone will not necessarily improve throughput if the workload is limited by memory bandwidth, CPU work, network transfer, or low utilization.
Precision options commonly evaluated include FP8, INT8, and 4-bit formats, as well as quantization of the key-value cache. Test each option on the actual task, prompts, context lengths, and concurrency. A candidate that saves memory but causes more incorrect answers, retries, or escalation can increase the cost per useful result.
Rank #4
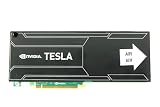
- Bulk Pack without retail box
Compilation and serving-runtime improvements can also increase throughput or reduce resource use, but reported gains are configuration-dependent. AWS reported an example of up to about 2× throughput and up to 50% lower cost in a 2024 SageMaker announcement; this is a vendor-reported result for a particular workload and configuration, not an expected result for every deployment. Google Cloud’s 2026 technical guidance lists quantization, tensor parallelism, and model-memory optimization as practices that can improve latency, throughput, and cost efficiency; the right choice depends on the model and bottleneck.
How do you choose the next optimization to test?
Use a small controlled evaluation rather than changing model, prompt, cache policy, and hardware at once. The best first experiment is the one that targets a large measured cost source while preserving the feature’s requirements.
- If token charges dominate: test a smaller model on routine requests, trim repeated context, cap output length, or use eligible prompt caching.
- If calls per task dominate: inspect agent steps, retrieval, tool calls, retries, and fallbacks; remove work that does not improve the result.
- If GPUs dominate: measure utilization and queueing, then test right-sizing, batching, autoscaling, or lower precision against task-level quality.
- If search, storage, or egress is material: measure those components separately and inspect retrieval volume, retained artifacts, and data movement before changing the model.
- If latency is the constraint: do not assume the cheapest tier is suitable; compare tail latency and reliability under realistic load before routing interactive requests.
Record the baseline and candidate on the same representative evaluation set. Include total charges, successful-task rate, quality, p95 and p99 latency, throughput, error rate, and interruptions. Roll out gradually and retain a fallback path for quality or reliability regressions.
Frequently Asked Questions
How do I estimate an AI inference budget before launch?
Build a forecast from expected task volume, measured calls and token counts per task, and the exact model and service tier you plan to use. Treat it as a range until you have production measurements, because retries, retrieval, and agent steps can make real usage differ from a simple one-call estimate.
Does caching send my data to other users?
Caching behavior and data handling depend on the provider’s service and your own cache design; a shared application cache can expose user-specific answers if its keys or access controls are wrong. Review the applicable provider terms and design cache keys, retention, and invalidation so one user’s private context is not served to another.
Should I batch live chatbot requests to save money?
Only if the product can tolerate asynchronous completion and the service’s timing behavior meets the user’s expectations. A discount is not worthwhile when the added wait or uncertain completion makes the answer unusable.
Quick Recap
Product prices and availability are accurate as of the date/time indicated and are subject to change. Any price and availability information displayed on Amazon at the time of purchase will apply.

