
Outdated Drivers Are Slowing You Down
One free scan finds every outdated or missing driver and matches the right update for your exact hardware.Free scan · exact hardware matchPC Slower Than It Used to Be?
A free scan shows the junk files, broken settings and background clutter dragging Windows down - then fixes them in one click.Free scan · Windows 10 & 11The right way to download website content depends on scope. Use your browser’s save or print function for one page, an offline mirroring tool for a bounded crawl, and an archive’s own download controls for an Internet Archive item. None of these methods guarantees a complete, authorized copy: dynamic content, access controls, copyright, and site terms still matter.
Choose the method that matches what you need
| Goal | Best fit | Main limitation |
|---|---|---|
| Keep one article or page | Browser save or print-to-file | Menus and output formats vary by browser and operating system. |
| Browse a bounded site offline | HTTrack mirror | JavaScript-generated links and content may be missed. |
| Obtain an archived item | Internet Archive Download Options | Some books, collections, and other items are restricted. |
| Preserve a visual record of a page | ScreenshotNeo or a browser screenshot | A screenshot is not the page’s source files or interactive behavior. |
Save a single web page
For a small number of pages, use your browser’s built-in save or print workflow. Save the page when you need its local resources; print to a file when a stable, paginated document is more useful. Because browser labels and formats differ by platform and version, check the menu shown by your installed browser rather than relying on a universal shortcut.


Check the result
- Open the saved file while disconnected from the network.
- Confirm that images, styles, tables, and links you need are present.
- Expect login-only, streaming, script-generated, or server-side features to fail offline.
If you need an image record rather than a functional copy, capture the page as an image or PDF. A screenshot preserves appearance at a moment in time but does not reproduce forms, search, video playback, or other behavior.
Mirror a website with HTTrack
HTTrack is a free, GPL-licensed offline browser utility. Its publisher says it recursively retrieves HTML, images, and other files into a local directory, rewrites links for offline navigation, can update a mirror, and can resume interrupted downloads. Versions are listed for Windows, Linux/Unix, Android, and the command line.
Recommended Free Tools
#1 Best Overall

- Used Book in Good Condition
Basic command-line workflow
- Install HTTrack from its official distribution for your operating system.
- Create a destination directory with enough free space for the expected files.
- Start with a tightly scoped URL and command such as
httrack https://example.com/ --path mydir. - Let the crawl finish, then open the generated local index or HTML file without a network connection.
- Review
hts-log.txtandhts-err.txtfor refused, redirected, or filtered URLs.
The documented default throttle is about 100 KB/s; it can vary with configuration and later versions. HTTrack normally stays on the same host, follows links to any depth, stores project data, logs, and cache in the output directory, and obeys robots.txt. Define boundaries before starting: a whole domain can include downloads, calendars, query-string variants, and very large media files.
Control scope and load
- Begin with a subdirectory or a short list of pages instead of an entire domain.
- Exclude file types or URL patterns you do not need, especially large video and archive files.
- Use a conservative crawl rate and schedule large jobs outside busy periods when the site owner permits it.
- Keep the project directory so an interrupted job can resume and a later run can update the mirror.
Why a completed crawl can still be incomplete
HTTrack discovers links by parsing HTML and CSS; it does not execute JavaScript. A URL assembled only at runtime, content fetched after a user action, and resources injected by script may never be discovered. Broader parsing options can help with awkwardly formatted links that already exist in source, but cannot reveal links that do not exist until code runs.
Mirror versus archival capture
A rewritten local mirror favors convenient offline navigation. HTTrack’s documented WARC output is an archival capture option, and its update reporting can classify files as new, changed, unchanged, or gone. WARC and a browsable mirror serve different purposes; neither is a perfect copy of every dynamic or access-controlled feature.
Download an Internet Archive item
The Internet Archive says that not all items are downloadable. Restricted books and some collections may have no downloadable files. For an item that permits downloads:
Free tools Windows power users keep installed
One-click scans. No signup required.
- Open the item’s page and find the Download Options area.
- Choose the particular file or format you need.
- For multiple files in one format, use the available multi-file option.
- For larger or repeatable jobs, use one of the Archive’s bulk methods, including
wgetor the Internet Archive command-line tool, as described in its help documentation.
Availability is item-specific. A visible item page is not proof that every derivative, book scan, or collection file can be downloaded.
Rank #2
Permissions, robots.txt, and copyright
Robots.txt is guidance, not permission
Google Search Central states: “A robots.txt file tells search engine crawlers which URLs the crawler can access on your site.” Robots.txt primarily manages crawler traffic. It is not a security barrier, does not grant copying rights, and is not guaranteed to control every crawler. Password protection and noindex address different concerns.
Confirm authorization
HTTrack warns that copying a website is the user’s responsibility and recommends responsible-use guidance before targeting a server you do not own. Respect terms of service, authentication barriers, rate limits, and requests from the site operator. Do not treat publicly viewable content as automatically free to reuse or redistribute.
Copyright varies by work and country
The U.S. Copyright Office explains that original website writing, artwork, and photographs may be protected. Its section 117 archival-copy discussion concerns computer programs under specific conditions; it does not create a general right to copy other website works. This U.S.-specific information is not individualized legal advice and does not resolve every jurisdiction or use.
Or skip the browser setup: capture a clean page with ScreenshotNeo
If your practical goal is a reliable visual copy rather than a navigable local mirror, ScreenshotNeo returns a PNG, JPEG, WebP, or PDF from one GET request. Before capture it accepts cookie or consent banners and removes more than 60 known consent platforms, newsletter popups, and chat widgets; each cleanup step can be disabled. Bot checks, CAPTCHAs, blank pages, timeouts, failed loads, and cache hits are not billed, and response headers identify the page verdict and billing status. It also provides an MCP server for Claude, Cursor, and other MCP clients, with take_screenshot, get_page_info, and capture_pdf tools.
See the ScreenshotNeo documentation for parameters. Replace the example URL with the page you are authorized to capture:
cURL
curl -G "https://api.screenshotneo.com/v1/shot" -d access_key=YOUR_API_KEY --data-urlencode url=https://stripe.com -o shot.webpPython
import requests
r = requests.get("https://api.screenshotneo.com/v1/shot", params={"access_key": "YOUR_API_KEY", "url": "https://stripe.com"}, timeout=90)
open("shot.webp", "wb").write(r.content)
Node.js
const q = new URLSearchParams({ access_key: 'YOUR_API_KEY', url: 'https://stripe.com' });
const res = await fetch(`https://api.screenshotneo.com/v1/shot?${q}`);
Options include full-page capture with lazy images loaded, CSS-selector element capture, dark mode, 12 device presets or a custom viewport, retina scale, PDF paper size, margins, landscape and page ranges, HTML/CSS rendering, custom JavaScript and CSS, clicks, selector waits, delays, network-idle waits, ad/tracker/request blocking, custom headers, cookies, user agents, Authorization, timezone and geolocation, transparent backgrounds, resizing, chosen cache TTL, signed public-image links, asynchronous jobs with signed webhooks, bulk capture of up to 100 URLs per call, usage reporting, and an OpenAPI specification. Parameter names used by other screenshot APIs also work, easing migration.
Rank #3
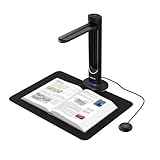
- [48MP Ultra-High Resolution] The K48 is a professional-grade book scanner equipped with a true 48MP Sony CMOS sensor, capable of capturing exceptional detail at 600 DPI — even on A3-sized materials. Used for digitizing books, magazines, documents, and archival materials with stunning clarity.
- [AI-Assisted Page Smoothing] Curved book pages are automatically flattened using intelligent software technology. This causes the removal of finger shadows, background interference, and page curvature — delivering flat, clean scans without any manual post-processing. Double pages are split automatically.
- [Laser Positioning & Auto-Scan] The built-in laser positioning system ensures precise alignment every time. Page turning detection causes the scanner to start capturing automatically as soon as a page is turned — ideal for high-volume digitization where speed matters.
- [Multi-Format OCR & Text-to-Speech] Used for creating searchable PDFs, editable Word/Excel files, or MP3 audio for voice playback. The K48 is capable of recognizing text in multiple languages and converting documents into accessible formats — perfect for education, accessibility compliance, and digital archives.
- [4K Live View & USB 3.0] Stream 4K@30fps video for live presentations, online classes, or real-time document review. USB 3.0 Type-C ensures fast data transfer and stable connection. Used for immediate setup in classrooms, offices, and libraries — plug and play, no drivers needed.
Pricing is Free: 1,000 shots per month with no card; Starter: $5 for 3,000; Growth: $15 for 15,000; Pro: $39 for 60,000; Scale: $99 for 250,000; Business: $249 for 1,000,000. Yearly billing gives two months free, and every feature is on every plan. Sign up for the free plan to get 1,000 screenshots a month with no card.
Troubleshooting downloaded content
The mirror is tiny or missing sections
Check the start URL, scope filters, redirects, and both HTTrack logs. Links created only by JavaScript require a browser-driven capture or a different authorized export.
Pages open but images do not
Confirm that image URLs were allowed, inspect filtered entries in the logs, and test the local copy without network access. Images served after scrolling or through scripts may not have been discovered.
The crawl overwhelms storage or traffic
Stop the job, narrow the path, exclude large extensions, lower concurrency or use a slower rate, and resume from the project directory.
An Archive download is unavailable
The item may be restricted or the collection may limit derivatives. Use only the formats and controls presented in Download Options; do not bypass access controls.
The screenshot is blank or challenged
For a self-managed browser capture, wait for the page and verify that the target is reachable without authentication. With ScreenshotNeo, inspect X-Page-Verdict and X-Billed; failed loads, bot checks, blank pages, timeouts, and cache hits are not billed.
Reliability and storage checklist
- Record the source URL, capture date, tool version, and crawl boundaries.
- Keep logs beside the mirror and verify representative pages offline.
- Hash or otherwise inventory important files if you need change detection.
- Store a WARC when archival fidelity matters, and a mirror when navigation matters.
- Use an external drive only when the mirror or WARC exceeds local storage; it is optional, not a requirement.
Frequently Asked Questions
Can I download a complete modern website?
Not reliably with one method. Static files can be mirrored, but JavaScript-generated content, logins, streaming media, and access-controlled features may remain unavailable.
Does robots.txt allow me to copy a site?
No. It communicates crawler access preferences and traffic management; permission, terms, copyright, and applicable law are separate questions.
What should I keep for an archive?
Keep the browsable mirror for offline navigation and WARC output when an archival capture is important; retain both only when you need both purposes.
Do these 3 things before closing this tab:
1Fix the driver behind crashes, sound loss and screen glitches2Repair Windows errors before they cause bigger problems3Scan for outdated or missing drivers - takes under a minuteQuick Recap
Product prices and availability are accurate as of the date/time indicated and are subject to change. Any price and availability information displayed on Amazon at the time of purchase will apply.

