
What’s actually slowing this PC down?
Pick the symptom - the matching free tool is one click away.
iTechGuides is reader-supported. When you buy through links on our site, we may earn an affiliate commission. As an Amazon Associate I earn from qualifying purchases. Learn more
Choose a GPU when you need broad framework support, changing models, mixed workloads, or local ownership. Choose a TPU when a matrix-heavy model fits Google’s software stack and you can use Google Cloud capacity. Choose a custom accelerator such as AWS Trainium for training or Inferentia for inference when a stable, high-volume workload can repay the porting and platform constraints. Validate the decision with a benchmark of your actual model; peak FLOPS and vendor marketing numbers are not enough.
What you are choosing
These three categories all accelerate machine-learning calculations, but they optimize for different trade-offs. The right choice depends on your model’s operators, memory behavior, software stack, deployment location, scale, and the engineering time available to tune it.
GPU: the programmable generalist
A graphics processing unit is a programmable accelerator available in many generations and form factors. Modern data-center GPUs support high-throughput training and real-time inference, with execution modes such as FP8, INT8, and INT4 for models that can tolerate lower numerical precision. The same programmability also makes GPUs useful for changing architectures, custom operators, multimodal pipelines, simulations, and workloads that mix AI with other parallel computation.
The Tool Desk
Outbyte PC Repair FREERepair Windows errors before they cause bigger problemsFix Now →Outbyte Driver Updater FREEScan for outdated or missing drivers - takes under a minuteDriver Scan →A GPU is not automatically useful for every server. A conventional web application with no graphics or machine-learning workload normally gains nothing from adding one; the accelerator must have parallel work to keep it occupied.
#1 Best Overall

- Graphics Card Interface: Pci E
TPU: a matrix-specialized Google ASIC
A tensor processing unit is Google’s custom application-specific integrated circuit for machine learning. Its matrix-multiply units use a systolic-array architecture: values move through a grid of arithmetic units so large, regular matrix operations can run efficiently. TPU capacity is normally consumed through Google’s cloud stack, including Compute Engine, Google Kubernetes Engine, and Vertex AI.
This specialization can be powerful for dense neural-network workloads, but it creates an architectural assumption. A model written and tuned for a GPU may leave TPU matrix units partly empty, require padding, or need custom kernels before it reaches expected performance.
Custom AI accelerators: specialized economics
A custom AI accelerator is an ASIC designed around a provider’s software, compiler, networking, and infrastructure. AWS Trainium and Inferentia illustrate the category: Trainium is positioned for machine-learning training and Inferentia for inference. These processors can offer attractive economics when the model and traffic pattern are stable, but the benefit is tied to the provider’s instances, SDKs, supported operators, and deployment services.
Outdated Drivers Are Slowing You Down
One free scan finds every outdated or missing driver and matches the right update for your exact hardware.Free scan · exact hardware matchPC Slower Than It Used to Be?
A free scan shows the junk files, broken settings and background clutter dragging Windows down - then fixes them in one click.Free scan · Windows 10 & 11Unlike a local GPU card, a TPU or custom ASIC is generally a cloud-capacity decision. You are selecting an instance family, region, quota, runtime, and software path as well as a chip.
Quick decision table
| Question | GPU | TPU | Custom AI accelerator |
|---|---|---|---|
| Best fit | Changing models, mixed operators, broad frameworks, local or cloud deployment | Dense, matrix-heavy machine-learning models that fit Google’s stack | Stable, high-volume training or inference tied to a provider’s platform |
| Software portability | Broadest ecosystem and mature tools | Porting may require compiler changes, padding, or custom kernels | Depends on the provider SDK, compiler, and supported operators |
| Where you obtain it | Buy a card or rent cloud instances | Usually Google Cloud services and instances | Usually the provider’s cloud instances and managed services |
| Strength | Flexibility and fast experimentation | Efficient dense tensor computation at cloud scale | Specialized cost, throughput, or energy for a repeatable workload |
| Main risk | Power, cooling, drivers, supply, and capital cost for local systems | Migration effort, quota, region availability, and TPU-specific tuning | Vendor lock-in, limited operators, and engineering cost to port and maintain |
| Typical first choice | Teams still exploring architecture or requiring local control | Teams already using Google’s ML services with a matrix-dominant model | Teams with predictable volume and a benchmark proving the advantage |
Match the accelerator to the workload
Training large, dense models
Training spends most of its time in repeated matrix multiplications, attention projections, and convolution-like operations. A TPU can be compelling when those operations fill its systolic arrays and the input pipeline keeps the chips fed. A GPU remains the safer choice when the architecture is evolving, uses uncommon operators, or must run in several environments.
For a custom accelerator, training volume matters. A one-off experiment rarely justifies rewriting data loaders, compiler configurations, and distributed-training code. A fixed model trained continuously at large scale may justify that work if measured cost per training step and time to convergence improve enough.
Online and batch inference
Inference has different constraints from training. Real-time serving is often limited by tail latency, small batch sizes, preprocessing, and postprocessing rather than raw arithmetic. Measure the complete request path, not only device time. A GPU’s low-precision modes can be valuable for INT8 or INT4 inference, while a custom inference ASIC can win when requests are homogeneous and traffic is high enough to keep it busy.
Recommended Free Tools
Batch inference, embedding generation, and offline scoring can use larger batches and tolerate queueing. Those conditions make dense tensor hardware easier to utilize, but memory capacity and data movement still determine whether the theoretical advantage appears in production.
Rank #2

- Professional AI & Creator Workstation: AMD Radeon AI PRO R9700 GPU with 32GB GDDR6 is engineered for AI development, professional content creation, and compute-intensive workloads.
- Massive 32GB Memory Capacity: 32GB of GDDR6 memory on a 256-bit bus provides ample bandwidth for large AI models, 8K video editing, and complex 3D rendering.
- Advanced RDNA 4 with AI Accelerators: 64 Compute Units with 3rd Gen Ray Tracing and dedicated 2nd Gen AI Accelerators for groundbreaking AI performance and visual computing.
- Professional Blower Cooling: Efficient single blower design exhausts heat directly out of the chassis, ideal for multi-GPU workstation and server configurations.
- Enterprise-Grade Thermal Solution: Vapor chamber heatsink with industrial Honeywell PTM7950 thermal interface material ensures reliable cooling under sustained professional loads.
Irregular control flow and mixed workloads
Dynamic shapes, sparse or branching operations, custom post-processing, retrieval logic, and frequent model changes favor GPU programmability. If only a portion of a pipeline is tensor-dense, moving data between host code and a specialized device can consume the time saved by the accelerated portion.
Models that change frequently
Research teams, startups, and products with rapid model iteration should value a short path from a new framework release to a working deployment. The broad GPU ecosystem usually reduces that friction. A specialized device becomes more attractive after the architecture, operators, sequence lengths, and traffic pattern have stabilized.
Memory and data movement matter as much as compute
Compare more than advertised FLOPS. For each candidate, record:
Quick wins for a faster PC:
Scan for outdated or missing drivers - takes under a minuteDriver Scan →Repair Windows errors before they cause bigger problemsFix Now →Fix the driver behind crashes, sound loss and screen glitchesFind Drivers →- Device memory capacity and the model’s peak allocation, including optimizer states, activations, and runtime buffers.
- Memory bandwidth and whether the workload repeatedly rereads weights or activations.
- Host-to-device link speed and the time required to transfer inputs, outputs, and checkpoints.
- Accelerator-to-accelerator interconnect bandwidth and latency for distributed training or serving.
- Whether the model fits on one device or requires sharding, offload, or repeated transfers.
A chip with lower nominal compute can finish sooner if it avoids spilling tensors or communicating across a slow link. In multi-chip jobs, synchronization and all-reduce traffic can dominate arithmetic. Include communication overhead in every comparison rather than multiplying a single-chip result by the number of devices.
Software portability and migration effort
GPU software path
GPU frameworks, kernels, profilers, quantization tools, and deployment libraries cover a broad set of models. This does not eliminate work: you still need compatible drivers, runtime versions, memory tuning, and kernels for unusual operators. The advantage is that a large share of community and vendor tooling already targets GPUs.
Moving PyTorch or CUDA code to a TPU
PyTorch code is not automatically equivalent on a TPU. A framework bridge and compiler must lower every operation to the TPU runtime. GPU-optimized code can expose an architectural mismatch: dimensions may need padding to fill matrix units, unsupported or inefficient operators may require alternate implementations, and custom CUDA kernels must be replaced with TPU-compatible kernels.
Plan a migration as an engineering project. Inventory operators, dynamic shapes, precision requirements, distributed primitives, checkpoint formats, and third-party extensions. Port a small but representative training or serving slice first. Compare numerical results, compilation time, warm-up behavior, steady-state throughput, and failure recovery before committing the whole system.
Using Trainium or Inferentia
A custom accelerator requires the provider’s SDK, compiler, runtime, and supported framework versions. Confirm that your model’s operators, quantization method, sequence lengths, and serving framework are supported in the exact instance generation you intend to use. Keep a GPU fallback during migration so a compiler regression, missing operator, or regional capacity problem does not halt releases.
Rank #3

- NVIDIA Volta GV100 Architecture — 4,608 CUDA Cores, 640 1st-Gen Tensor Cores delivering 14 TFLOPS FP32 and 112 TFLOPS deep learning performance for AI training, inference, HPC, and scientific computing workloads
- 32GB HBM2 ECC Memory — 900 GB/s Bandwidth — High-bandwidth memory on a 4096-bit bus with ECC error correction provides the memory capacity and throughput required for the largest AI models, simulations, and datasets
- PCIe 3.0 x16 Interface — 250W TDP — Standard PCIe Gen3 connectivity with passive cooling designed for enterprise rack server deployment in HPE ProLiant, Dell PowerEdge, and Supermicro platforms with adequate chassis airflow
- NVLink — Scale to 96GB Unified Memory — Connect two V100 GPUs via NVLink at 300 GB/s bi-directional bandwidth to scale GPU memory from 32GB to 96GB for larger AI training and HPC workloads
- Multi-Precision Computing — Supports FP64 (7 TFLOPS), FP32 (14 TFLOPS), FP16 (112 TFLOPS) and INT8 precision modes for flexible deployment across training, inference, and scientific simulation workloads
Local GPU purchase versus cloud capacity
When buying a GPU makes sense
A local GPU is the most straightforward physical purchase. It gives you persistent capacity for development, private data, and predictable workloads without waiting for cloud quota. Budget for the complete system, not just the card:
- Power supply headroom and the card’s sustained electrical draw.
- Case or chassis clearance, airflow, and cooling for long training runs.
- Motherboard slots, host memory, storage, and the required driver versions.
- Noise, maintenance, warranty, and replacement time.
- Capital amortization over the number of useful hours you expect to run it.
Local hardware is less attractive when utilization is sporadic, the model exceeds one workstation, or you need rapid access to several generations of accelerators.
When renting a TPU or custom accelerator makes sense
Cloud capacity avoids purchasing, powering, and cooling hardware. It also supplies managed networking and integrations with training and serving services. The trade-off is variable availability, quotas, region restrictions, instance pricing, storage and network charges, and dependence on the provider’s software lifecycle.
Free tools Windows power users keep installed
One-click scans. No signup required.
Ask whether the required accelerator is available in the region where data may be processed, whether quota can be raised before launch, and whether the provider offers a comparable fallback. A theoretically superior chip that cannot be allocated during a release window is not a reliable production choice.
Build a complete cost model
“Cheaper” is meaningful only after you define the unit of work. Use cost per completed training run, cost per million generated tokens, cost per request at a stated latency target, or another production unit. Include:
- Instance or hardware cost, with the billing unit and any minimum commitment.
- Storage, data transfer, orchestration, and managed-service charges.
- Engineering time for porting, compiler tuning, kernel development, monitoring, and incident response.
- Utilization: an inexpensive instance running at 20% occupancy may cost more per useful output than a dearer instance kept busy.
- Energy and cooling for owned equipment, or energy-related telemetry supplied by the cloud.
- The cost of switching providers if an SDK, model format, or region becomes unavailable.
Do not transfer one vendor’s peak energy or price claim to another workload. Measure energy per useful request or token under the same model, batch size, sequence length, and quality target.
A benchmark that can support the decision
Use the same model architecture, weights, tokenizer, data, precision, sequence length, batch policy, and quality acceptance criteria on every candidate. Google’s accelerator guidance recommends normalizing throughput to tokens per second per chip for comparable language-model runs. That normalization is useful only when the workload and production settings are genuinely equivalent.
- Define the production case. Record training versus inference, target batch size, sequence-length distribution, concurrency, latency percentile, quality threshold, and expected daily volume.
- Prepare equivalent implementations. Use the same preprocessing, postprocessing, checkpoint behavior, and numerical precision. Document any operator replacement or padding required by a device.
- Warm up the system. Separate compilation and cache-building time from steady-state measurements, but report both because cold starts matter for autoscaling and short jobs.
- Measure end-to-end latency. Include queueing, tokenization, host-to-device transfer, device execution, device-to-host transfer, detokenization, and response serialization. Capture p50, p95, and p99 where the service has a latency objective.
- Measure throughput at the real operating point. Test the target batch size and sequence length, then vary concurrency to find the point before tail latency violates the service objective.
- Record memory behavior. Capture peak and steady-state device memory, host memory, fragmentation, activation checkpoints, and any offload or retry events.
- Measure utilization and communication. For multi-chip runs, record arithmetic utilization, input-pipeline stalls, synchronization time, all-reduce or other collective traffic, and idle gaps.
- Calculate unit economics. Convert the measured run time and billed resources into cost per request, training step, completed run, or generated token. Add engineering and operational costs separately rather than hiding them in a chip price.
- Measure energy when possible. Use device or facility telemetry to calculate energy per request or token under the same test conditions. State whether the reading covers only the accelerator or the whole server.
- Repeat after tuning. Give each platform a fair tuning window, record code changes, and preserve the untuned baseline. A large speedup that requires permanent manual intervention may not be operationally worthwhile.
How to read vendor performance claims
Google reported in 2024 that its Trillium generation delivered 4.7× peak compute per chip and more than 67% better energy efficiency than the TPU v5e generation. Those are Google’s generation-over-generation claims for Trillium versus TPU v5e, not a universal GPU-versus-TPU result. They do not establish your latency, cost, or energy outcome without a matched benchmark.
Rank #4
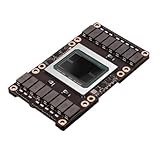
- Robust Design:Constructed to withstand high temperatures, the V100 16GB SXM2 card operates efficiently up to 105℃.
- Advanced Connectivity:Features a SXM2 connector for seamless integration with a wide range of systems, ensuring compatibility.
“A TPU is a custom-designed ASIC engineered to handle the demands of massive matrix operations in ML algorithms.”
That description explains the design intent, not a guarantee for every model. Peak compute assumes the chip is fed with suitable operations, dimensions, precision, and data. A lower peak number can win on a workload that spends less time padding, compiling, transferring, or synchronizing.
A practical decision framework
Start with non-negotiable constraints
- Location and privacy: If data must remain on premises, eliminate cloud-only TPU and custom-ASIC options unless you have an approved private deployment.
- Framework: If a required library, custom kernel, or debugger exists only on one platform, treat that as a hard constraint.
- Latency: Set the tail-latency target before optimizing average throughput.
- Capacity: Check memory per device, interconnect topology, regional quota, and scale-up limits.
- Lifecycle: Estimate how often the model, framework, and compiler will change during the expected hardware life.
Then score the economic case
Benchmark at least one current GPU path and each credible specialized path. Score the measured unit cost, throughput, latency, energy, engineering hours, operational tooling, and fallback options. Keep the scorecard tied to a dated software and pricing snapshot; accelerator generations, instance prices, and framework support change.
Do these 3 things before closing this tab:
1Fix the driver behind crashes, sound loss and screen glitches2Clear out junk files and repair common Windows errors3Scan for outdated or missing drivers - takes under a minuteChoose a default when evidence is incomplete
Select a GPU for an exploratory or mixed workload, for a team that needs local deployment, or when portability is more valuable than a possible specialized gain. Select a TPU when the model is dense and stable, the team already operates in Google’s stack, and the benchmark shows efficient matrix utilization. Select Trainium or Inferentia when the workload is stable, volume is high, the AWS platform is already central to operations, and the measured savings exceed migration and fallback costs.
Common failure modes and fixes
The benchmark reports peak FLOPS but production is slow
Check input stalls, memory bandwidth, host transfers, compilation, kernel coverage, and synchronization. Replace the synthetic test with the full request or training step and report tokens per second at the target batch and sequence length.
The model does not fit despite adequate headline memory
Include optimizer states, activations, temporary buffers, framework overhead, and fragmentation. Reduce precision only if quality remains acceptable; otherwise shard the model, use activation checkpointing, or choose a device with more usable memory.
TPU utilization is low after a GPU-to-TPU port
Inspect tensor dimensions and padding, unsupported operators, input-pipeline stalls, and recompilations caused by dynamic shapes. Consolidate shapes where possible and replace inefficient operations with TPU-compatible implementations before judging the hardware.
A custom accelerator saves device cost but increases total cost
Count porting, compiler debugging, monitoring changes, retraining, incident response, and the GPU fallback retained for safety. Recalculate cost per useful output over the period in which those engineering hours are amortized.
Cloud capacity is unavailable at launch
Request quota early, test more than one region when policy permits, reserve capacity if the service offers it, and maintain a tested fallback implementation. Include failover performance and cost in the production design rather than treating them as an emergency-only concern.
What to document before committing
- The exact accelerator generation, instance type, software versions, compiler flags, and driver or runtime versions.
- The model commit, dataset or traffic sample, precision, batch policy, and sequence-length distribution used for the benchmark.
- Measured latency percentiles, tokens per second per chip, memory, utilization, communication, cost, and energy.
- Known unsupported operators, numerical differences, quality results, and required custom kernels.
- Quota, region, capacity, upgrade, deprecation, and exit plans.
- The GPU or other fallback path that can serve the model if the specialized platform fails.
The durable choice is the platform that meets the production objective with acceptable engineering and operational risk. Hardware specifications are inputs to that decision, not the decision itself.
Quick Recap
Product prices and availability are accurate as of the date/time indicated and are subject to change. Any price and availability information displayed on Amazon at the time of purchase will apply.

