
Do these 3 things before closing this tab:
1Scan for outdated or missing drivers - takes under a minute2Repair Windows errors before they cause bigger problems3Fix the driver behind crashes, sound loss and screen glitchesEdge AI runs inference on or near the device that collects data; cloud AI sends data to centralized infrastructure for processing. Edge can respond locally and keep working through an internet outage, while cloud platforms offer more compute and make large-scale training and analytics easier. Neither is automatically faster, safer, or cheaper for every workload. The right choice depends on response-time needs, connectivity, data sensitivity, model requirements, device costs, and how much operational work your team can support; many systems combine both.
What edge AI and cloud AI mean
Edge AI
Edge AI performs a model’s inference—the step where a trained model analyzes new input—on a device or nearby computer, such as a sensor, camera, industrial gateway, or other local system. The device can act on input without first sending it to a remote service. AWS describes edge AI as AI running on a device close to the end user.
Cloud AI
Cloud AI sends input over a network to a model or service hosted in centralized cloud infrastructure. That infrastructure can draw on larger pools of compute, memory, and storage than a typical edge device, and can serve data and applications from multiple locations with internet access.
These terms describe where processing happens, not a single product or model type. A system can use a small local model for immediate decisions and a cloud model for more demanding analysis.
The Tool Desk
Outbyte Driver Updater FREEFix the driver behind crashes, sound loss and screen glitchesFind Drivers →Outbyte PC Repair FREEClear out junk files and repair common Windows errorsFree Scan →#1 Best Overall

- Build the Most Powerful Embedded AI Platform: Compatible with the Jetson Orin NX module, offering up to 100 TOPS.
- Design for Both Development and Production: Equip with rich set of I/Os: 2x USB3.2, HDMI, Ethernet, M.2 Key M, M.2 Key E, mini-PCIe, 40-pin GPIO, etc
- Support multiple wired and wireless commnucation including Wi-Fi and LTE
- Immediately Go-to-Market: Pre-installed JetPack5.1.3, Linux OS BSP ready
- Certification includes ROHS, CE, FCC, KC, UKCA, REACH
How the trade-offs compare
| Decision factor | Edge AI | Cloud AI |
|---|---|---|
| Response time | Can avoid the network round trip, which is useful when a local decision must happen quickly. Actual performance depends on the device and model. | Includes network travel and service processing, so response time varies with connectivity and service conditions. Microsoft Learn notes that network communication can introduce latency. |
| Internet availability | Can keep performing supported local inference without an internet connection or during degraded connectivity. | Requests generally depend on network access to the service; a disruption can delay or interrupt inference. |
| Data handling | Can keep raw inputs at the collection site or send only selected results. Local storage, software, and access still need protection. | Moves inputs to a centralized service, where centralized controls may help operations but transfer, residency, and compliance requirements still apply. |
| Model and compute capacity | Bound by the device’s compute, memory, storage, and power. A model may need to be compressed, quantized, or replaced with a smaller architecture. | Can draw on more elastic compute and storage for large-model training, large datasets, and complex analytics. |
| Bandwidth | Can filter locally and transmit events, summaries, or embeddings instead of every raw frame or sensor reading. | Continuous raw video, audio, or sensor uploads can require substantial network capacity and incur transfer or ingestion costs. |
| Scaling and operations | Distributes processing across sites, but requires provisioning, updates, monitoring, compatibility work, security, and eventual device replacement across the fleet. | Centralized infrastructure is easier to scale for changing workloads and providers manage much of the infrastructure maintenance, but the design depends on the provider and network. |
| Cost profile | Requires capable hardware at each deployment point; total cost depends on device, energy, maintenance, connectivity savings, and utilization. | Pay-as-you-go usage can scale without installing compute at each site, but recurring service and data-transfer costs can accumulate. |
The comparison is directional, not a universal performance or cost guarantee. AWS and IBM describe edge systems as useful under limited connectivity; NIST identifies constrained resources, communication limits, and additional security vulnerabilities as edge-AI challenges. None of these trade-offs yields a single cost, latency, energy, or carbon figure that applies across workloads.
Where edge AI is a strong fit—and what it costs operationally
Benefits of processing near the source
- Fast local decisions: Removing the remote round trip is valuable for industrial control, robotics, autonomous systems, cameras, and safety monitoring when a system must respond promptly.
- Operation through connectivity loss: A device with the needed model and local inputs can continue supported inference when its network is unavailable. It cannot rely on a cloud-only model or service while disconnected.
- Less raw-data movement: Local filtering can reduce how much raw video, audio, or sensor data leaves the site. Sending only events or summaries may also reduce bandwidth demand.
- Distributed processing: Many devices or sites can handle their own inputs instead of funneling every raw stream to one cloud endpoint.
Liabilities of an edge fleet
Local processing moves responsibility rather than removing it. Each device is an endpoint that may require provisioning, physical protection, patching, model rollout, observability, rollback, compatibility checks, and replacement. Microsoft notes that local users are responsible for updates, compatibility, and vulnerability management. Heterogeneous hardware can make consistent maintenance harder.
Device limits can also constrain model size and capability. NIST highlights resource and communication constraints; teams may need to compress or quantize a model, or select a smaller architecture. A device that cannot run the required model at the required quality is not a suitable edge target merely because it is close to the data.
Rank #2

- The NVIDIA Jetson AGX Orin 64GB Developer Kit makes it easy to get started with Jetson Orin. Compact size, lots of connectors, and up to 275 TOPS of AI performance make this developer kit perfect for prototyping advanced AI-powered robots and other autonomous machines.
- The developer kit includes a Jetson AGX Orin 64GB module, and can emulate all the Jetson Orin modules. It supports multiple concurrent AI application pipelines with the NVIDIA Ampere GPU architecture, next-generation deep learning and vision accelerators, high-speed IO and fast memory bandwidth. Now you can develop solutions using your largest and most complex AI models to solve problems such as natural language understanding, 3D perception, and multi-sensor fusion.
- Jetson runs the NVIDIA AI software stack, and use-case specific application frameworks are available, including Isaac for robotics, DeepStream for vision AI, and Riva for conversational AI. You can save significant time with NVIDIA Omniverse Replicator for synthetic data generation (SDG), and by using NVIDIA TAO toolkit to fine-tune pretrained AI models from the NGC catalog.
- Jetson ecosystem partners offer additional AI and system software, developer tools, and custom software development. They can also help with cameras and other sensors, as well as carrier boards and design services for your product.
- With the computing capability of more than 8 Jetson AGX Xavier systems in a developer kit that integrates the latest NVIDIA GPU technology with the world’s most advanced deep learning software stack, you’ll have the flexibility to create tomorrow’s AI solution as well as today’s.
Where cloud AI is a strong fit—and its liabilities
Benefits of centralized infrastructure
- More elastic resources: Cloud compute and storage support workloads such as foundation-model training, large-scale analytics, and complex natural-language or computer-vision processing.
- Centralized operations: Providers maintain much of the underlying infrastructure and may update hosted services, reducing device-side administration.
- Shared access: Cloud APIs and services can support applications and teams in different locations, subject to internet access and the relevant service’s availability.
Liabilities of sending work to the cloud
A cloud request must travel across a network, so an unstable connection can add delay or interrupt inference. Streaming raw data can raise bandwidth needs and transfer or ingestion charges. Usage-based compute costs can also grow with workload volume and duration; cloud pricing is not automatically less expensive than local hardware.
Recommended Free Tools
Sending sensitive input off-site creates data-movement and governance questions. Confirm where data is processed and stored, who can access it, and which privacy, residency, or sector-specific rules apply. Microsoft specifically flags GDPR and HIPAA considerations. Centralized controls may simplify some administration, but they do not remove the need to assess compliance or secure the transfer.
Cloud architecture also depends on a provider’s service behavior, quotas, regional availability, and API lifecycle. Consider portability and a fallback plan for service changes or outages rather than treating a provider endpoint as an invisible dependency.
Rank #3

- Fanless compact PC: Thermal reference design, wider temperature support -20 ~ 60°C with 0.7m/s airflow
- Designed for industrial interfaces: 2* RJ-45 GbE(1 for POE-PSE 802.3 af); 1* RS-232/RS-422/RS-485; 4* DI/DO; 1* CAN; 3* USB3.2; 1* TPM2.0 (Module optional)
- Hybrid connectivity: Support 5G/4G/LTE/LoRaWAN/GPS(Module optional) with 1* Nano SIM card slot
- Flexible mounting: Desk, DIN rail, wall-mounting, VESA
- Certifications: FCC, CE, RoHS, UKCA
How to choose for a specific workload
Start with the task and its failure conditions, not a blanket preference for “edge” or “cloud.” Answer these questions with the people responsible for the application, infrastructure, security, and compliance:
- What response time is required? Set a workload-specific target and determine whether a network round trip is acceptable. For control or safety tasks, identify what the system should do if a remote response arrives late.
- What must happen offline? Decide whether the application must continue during an outage, and which functions can degrade or stop. Verify that local hardware can run the required model and retain any needed configuration.
- How sensitive is the input? Map whether raw data can leave the collection site, what needs to be retained, and which privacy, residency, or sector rules apply. Keeping data local can reduce exposure through transmission, but does not secure the device by itself.
- What model capability is needed? Evaluate the model’s memory, compute, and storage demands against available devices, then check accuracy and response time on the actual workload. Use cloud resources when the task needs capabilities local hardware cannot support.
- What is the full operating cost? Compare device purchase and replacement, power, maintenance, connectivity, bandwidth, storage, service usage, and data transfer. The result depends on workload volume and utilization, not just the price of a device or cloud request.
- Who owns updates and security? Identify responsibility for patching, model versions, access control, monitoring, incident response, and rollback across both devices and cloud services.
- How often will the model or data change? Account for rollout cadence, device compatibility, and how to validate a new model before it reaches the full fleet.
Compare the options under the same workload assumptions. A useful evaluation records the model, hardware, network conditions, deployment region, duty cycle, security configuration, and expected load. Without those details, a claimed latency, energy, or cost comparison may not predict your deployment.
What’s actually slowing this PC down?
Pick the symptom - the matching free tool is one click away.
Why a hybrid edge-cloud design is often practical
A hybrid design assigns work according to urgency, sensitivity, and compute need. Keep immediate control and privacy-sensitive preprocessing local; send selected events, aggregates, or uncertain cases to the cloud; and use cloud capacity for training, fleet-wide analytics, evaluation, or larger fallback models.
Rank #4
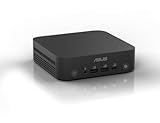
- Unleash Pure Power: Featuring AMD Ryzen AI 300 Series Processors with 6 ultra-fast cores, designed for powerful, efficient multitasking
- Next-Level AI: Cutting-edge XDNA2 NPU with up to 50 TOPS—5x faster AI performance than before for responsive, dynamic computing
- Immersive 4K Visuals: AMD Radeon 800M Graphics delivers breathtaking detail across up to four 4K displays
- Ultrafast and Versatile connectivity: Enjoy ultrafast connectivity with Wi-Fi 7 and Bluetooth 5.4 and benefit from a versatile array of connectivity options, including 6 USB ports, dual 2.5G LANs, and dual DisplayPort
- Sleek, Durable Design: The Ultra-thin (0.6L), eco-conscious chassis runs reliably, 24/7, sets a new standard for thin and light computing performance, and features a toolless design that allows for effortless customization
Microsoft documents a local-first pattern that tries a local model and falls back to a cloud endpoint when the local model is unavailable, the device is unsupported, consent is absent, or the task needs a larger model. That fallback should be explicit: define what happens if the network is down, the cloud response misses its deadline, or policy forbids sending the input. A design that claims offline resilience but requires a cloud response for its essential action does not provide that resilience.
Measure before committing to a deployment
There is no universal percentage by which edge AI is faster, cheaper, more energy-efficient, or lower-carbon than cloud AI. Those outcomes vary with the model, device, network, workload, utilization, and security configuration. Test representative inputs on the intended hardware and cloud region, under realistic network and duty-cycle conditions. Measure response time, accuracy, availability, bandwidth, energy, operating effort, and total cost over the period that matters to the deployment.
Quick Recap
Product prices and availability are accurate as of the date/time indicated and are subject to change. Any price and availability information displayed on Amazon at the time of purchase will apply.

