LM Evaluation Harness
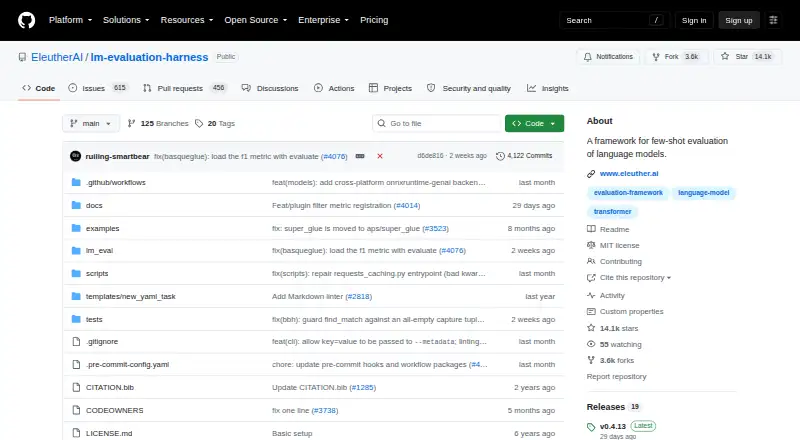
LM Evaluation Harness: A broad, research-focused harness for repeatable benchmark evaluation across local and API models. Ranked #19 of 29 in LLM Evaluation Tools by our editors (7.4/10); pricing: Open source; best for academic benchmark evaluation of language models.
At a glance
- Editor score7.4 / 10
- PricingOpen source
- Best forAcademic benchmark evaluation of language models
- Paid fromFree
- Deployment optionsSelf-hosted
- Facts checked20 Sep 2026
Where it wins
- Over 60 standard benchmarks with hundreds of subtasks and variants
- Supports local models, commercial APIs, custom prompts, and custom metrics
- Runs through command-line and Python APIs with YAML task definitions
Where it doesn't
- Self-hosted deployment places environment management with the user
- Focused on standardized evaluation rather than broader review workflows
- Its academic breadth may exceed the needs of simple model comparisons
Our verdict on LM Evaluation Harness
LM Evaluation Harness is an open-source Python framework for evaluating generative language models across standardized tasks. It is aimed at researchers, model developers, and organizations comparing model capabilities with repeatable evaluation setups. The framework supports local models and commercial model APIs, including OpenAI and TextSynth, while its model ecosystem includes Hugging Face Transformers, GPT-NeoX, Megatron-DeepSpeed, and vLLM. Evaluations can be run through command-line or Python APIs, making it suitable for both scripted research workflows and programmatic experiments.
Its main strength is breadth. The published feature set covers over 60 standard academic benchmarks, with hundreds of subtasks and variants, plus configurable YAML task definitions, custom prompts, and custom evaluation metrics. That combination gives research teams room to adapt benchmark runs without abandoning a common evaluation framework. TruthfulQA evaluation is also documented, supporting truthfulness-oriented testing. Integrations with Hugging Face PEFT and Weights & Biases extend its fit within model development and experiment-tracking workflows, while vLLM provides a fast, memory-efficient inference option for supported use cases.
The trade-off is that LM Evaluation Harness is primarily a self-hosted evaluation framework rather than a hosted review environment. Teams should be prepared to manage the runtime, model access, API credentials, benchmark configuration, and execution process themselves. Its documented focus is academic benchmarking and configurable metrics, so it is a stronger choice for researchers and model developers who need broad standardized comparisons than for teams seeking a packaged workflow centered on human review, LLM judging, or CI/CD. Choose it when benchmark coverage and backend flexibility matter most; consider another tool when evaluation needs extend beyond that research-oriented scope.
Your product? Our editors can test LM Evaluation Harness in depth and publish a review, labelled as paid · from $149/mo →
LM Evaluation Harness pricing
LM Evaluation Harness fact sheet
| Free plan | Not verified |
|---|---|
| Paid from | Free |
| Deployment options | Self-hosted |
| Custom metrics | Yes |
| LLM-as-a-judge | Not verified |
| Safety evaluations | Yes |
| Human review workflows | Not verified |
| Prompt versioning | Not verified |
| CI/CD integration | Not verified |
| Deployment | Self-hosted |
| Support | Community, Docs |
| Built for | Solo, Small business, Mid-market, Enterprise (editorial estimate) |
| Integrations | 6 integrations: Hugging Face Transformers, vLLM, OpenAI API, TextSynth, Hugging Face PEFT, Weights & Biases |
| Pricing | Open source |
| Website | github.com |
| Facts checked | 20 Sep 2026 |
LM Evaluation Harness integrations
LM Evaluation Harness lists 6 integrations on its own site.
- Hugging Face Transformers
- vLLM
- OpenAI API
- TextSynth
- Hugging Face PEFT
- Weights & Biases
Alternatives to LM Evaluation Harness
- DeepEvalA broad open-source toolkit for evaluating LLM apps, agents, RAG pipelines, and chatbots.9.4
- PromptfooA broad evaluation toolkit for teams that need testing, security scans, and CI/CD gates.9.3
- GalileoA mature evaluation platform spanning offline testing, production tracing, and runtime controls.9.1
See all LM Evaluation Harness alternatives →
Also Ranked In
LM Evaluation Harness is ranked in 2 of our directories.
Used LM Evaluation Harness? Be the first to review it
The editor score above is our own research. What this page doesn't have yet is a reader's view — what you used LM Evaluation Harness for, what worked and what didn't. No stars are seeded and no review is paid for; an editor reads every one before it appears.
Write a reviewTwo minutes · verified accounts only · read by an editor before it appears
Featured on iTechGuides
LM Evaluation Harness is listed in our LLM Evaluation Tools directory. Add the badge to your site — it links back to this page.
<a href="https://www.itechguides.com/products/lm-evaluation-harness/"><img src="https://www.itechguides.com/best/badge/lm-evaluation-harness.svg" alt="Featured on iTechGuides" width="230" height="46"></a>
Reviewed by iTechGuides Editors · Editorial team · Updated Oct 2026
Advertiser disclosure: iTechGuides is reader-supported. Vendors can pay for top positions in our rankings and for a place on other products' pages, and we may earn a commission when you click some links. Bought places stand at the number bought; this page and our disclosure say so. Paying vendors may get a fuller, more detailed review from our editors, and that review can change their score. How we rank.
Last updated · How we research and update