Holistic Evaluation of Language Models (HELM)
Holistic Evaluation of Language Models (HELM): A broad, free benchmark framework for reproducible model comparisons and safety analysis. Ranked #25 of 39 in AI Model Evaluation Software by our editors (6.6/10); pricing: Free plan; best for standardized public model benchmark comparisons.
At a glance
- Editor score6.6 / 10
- PricingFree plan
- Best forStandardized public model benchmark comparisons
- Free planYes
- Paid fromFree
- Safety & bias checksYes
- Founded2022
- Facts checked19 Nov 2026
Where it wins
- Broad standardized datasets spanning capability, safety and specialist domains
- Unified connectors for OpenAI, Anthropic Claude and Google Gemini
- Public leaderboards plus multidimensional metrics for transparent comparisons
Where it doesn't
- Self-hosted deployment requires managing the evaluation environment
- Documentation is the listed support channel
- Benchmark focus may not fit teams seeking production monitoring workflows
Our verdict on Holistic Evaluation of Language Models (HELM)
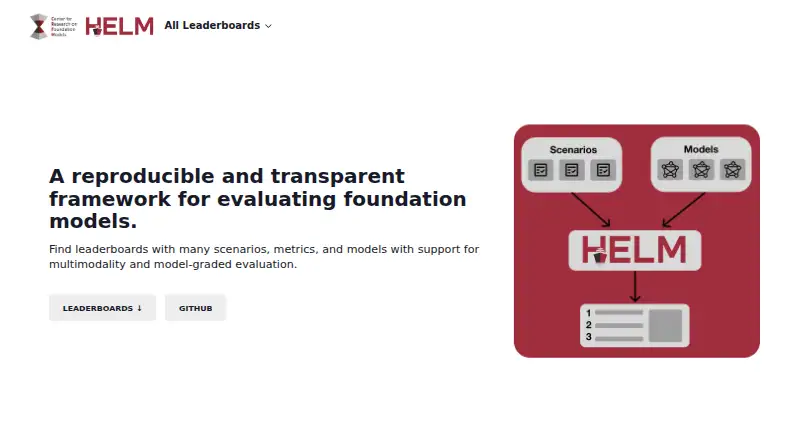
Holistic Evaluation of Language Models (HELM) is an open-source Python framework from Stanford CRFM for evaluating language and multimodal foundation models. It is designed for researchers, model developers and organizations that need standardized comparisons across capabilities, safety, vision-language, text-to-image, audio-language, medical and enterprise evaluations. Command-line execution, result summarization and a local web interface support both repeatable runs and detailed inspection of prompts and responses.
HELM’s main strength is breadth within a common evaluation structure. Its published benchmarks include MMLU-Pro, GPQA, IFEval and WildBench, while its metrics cover dimensions such as efficiency, bias and toxicity in addition to model capability. Connectors for OpenAI, Anthropic Claude and Google Gemini provide a shared interface across major providers. Public leaderboards and reproductions of published capability, safety and domain leaderboards make results easier to compare, while local inspection helps teams review individual outputs rather than relying only on aggregate scores.
The trade-off is operational scope. HELM is deployed self-hosted and centers on benchmark execution, result analysis and public comparison, so teams looking for a managed service or broader production observability should consider a different category of tool. Documentation is the listed support channel, placing more responsibility on the team running the framework. The project entered maintenance mode on June 1, 2026, although its repository and documentation remain available. Choose HELM when reproducibility, standardized datasets and multidimensional public benchmarks are priorities; look elsewhere when active feature development, hosted operations or production-focused workflows matter more.
Holistic Evaluation of Language Models (HELM) pricing
Holistic Evaluation of Language Models (HELM) fact sheet
| Free plan | Yes |
|---|---|
| Paid from | Free |
| Evaluation types | capabilities, safety, vision-language, text-to-image, audio-language, medical, enterprise |
| Safety & bias checks | Yes |
| Regression benchmarks | Not verified |
| Human review workflows | Not verified |
| Included evaluation runs | Not verified |
| Deployment option | Self_hosted |
| Model providers | OpenAI, Anthropic, Google |
| Deployment | Self-hosted |
| Platforms | Web |
| Support | Docs |
| Built for | Solo, Small business, Mid-market, Enterprise (editorial estimate) |
| Integrations | 3 integrations: OpenAI, Anthropic Claude, Google Gemini |
| Pricing | Free plan |
| Website | crfm.stanford.edu |
| Facts checked | 19 Nov 2026 |
Holistic Evaluation of Language Models (HELM) integrations
Holistic Evaluation of Language Models (HELM) lists 3 integrations on its own site.
- OpenAI
- Anthropic Claude
- Google Gemini
Alternatives to Holistic Evaluation of Language Models (HELM)
- LangSmithA broad LangSmith toolkit for tracing, evaluating, and improving LLM applications.9.4
- RagasA flexible, self-hosted toolkit for metric-driven LLM evaluation.9.1
- BraintrustGoverned evaluation, tracing, and regression controls for teams operating AI applications.8.9

See all Holistic Evaluation of Language Models (HELM) alternatives →
Used Holistic Evaluation of Language Models (HELM)? Be the first to review it
The editor score above is our own research. What this page doesn't have yet is a reader's view — what you used Holistic Evaluation of Language Models (HELM) for, what worked and what didn't. No stars are seeded and no review is paid for; an editor reads every one before it appears.
Write a reviewTwo minutes · verified accounts only · read by an editor before it appears
Featured on iTechGuides
Holistic Evaluation of Language Models (HELM) is listed in our AI Model Evaluation Software directory. Add the badge to your site — it links back to this page.
<a href="https://www.itechguides.com/products/holistic-evaluation-of-language-models-helm/"><img src="https://www.itechguides.com/best/badge/holistic-evaluation-of-language-models-helm.svg" alt="Featured on iTechGuides" width="230" height="46"></a>
Reviewed by iTechGuides Editors · Editorial team · Updated Nov 2026
Advertiser disclosure: iTechGuides is reader-supported. Vendors can pay for top positions in our rankings and for a place on other products' pages, and we may earn a commission when you click some links. Bought places stand at the number bought; this page and our disclosure say so. Paying vendors may get a fuller, more detailed review from our editors, and that review can change their score. How we rank.
Last updated · How we research and update