
Free tools Windows power users keep installed
One-click scans. No signup required.
Measure the time it takes to produce finished, usable work—not just the speed of an AI’s first response. Compare equivalent tasks with and without AI, include prompting, review, editing and rework, and assess quality alongside duration. The result should describe the specific tasks, people, tool and period you measured, not promise a universal productivity gain.
Define what you are measuring
“AI productivity” is too broad to serve as a useful metric. Start with a defined workflow: name the task, the people doing it, the AI tool and version, and the conditions under which the work happens. Drafting a routine customer response, for example, is a different use case from preparing a complex report. Choose metrics to fit the use case, because the relevant evaluation depends on the context in which an AI system operates, as NIST’s measurement and evaluation guidance explains.


Write down the task’s starting point and what counts as done. A practical endpoint might be a result that meets an existing acceptance criterion and is ready for its intended use. Decide in advance whether you will track elapsed time, active work time, or both; label the measure clearly and use the same definition for each workflow.
Compare equivalent work fairly
Compare tasks that are similar enough for the time difference to be meaningful. If AI-assisted work consists mostly of simple cases while the non-AI group handles the difficult ones, the comparison may reflect task mix rather than the tool. Record relevant differences in task complexity, user experience and workload.
What’s actually slowing this PC down?
Pick the symptom - the matching free tool is one click away.
Random assignment to AI-assisted and non-AI workflows can reduce some sources of bias when it is feasible and appropriate. If that is not practical, consider matching similar tasks or introducing the tool in phases, documenting how the groups or periods differ. These are practical study-design options, not a single experiment that NIST prescribes for every team. NIST’s Measure playbook emphasizes choosing valid measures and considering confounding factors.
Track the complete path to usable work
For the AI-assisted workflow, count the work needed to get from task start to a finished result. Depending on the task, that can include preparing context, writing prompts, waiting for responses, checking facts, editing, correcting errors and handling later rework. Apply the same start and end rules to the non-AI workflow.
A fast first draft is not necessarily time saved. If a person spends less time writing but more time checking or repairing the output, that effort belongs in the comparison. Record downstream corrections when they occur outside the initial task window; otherwise, the apparent time advantage may simply shift work to another person or a later stage.
Measure quality as well as time
Before comparing results, choose a quality rubric or acceptance criterion that fits the task. Apply it consistently to both workflows. Track correction or rework when relevant, and report those results alongside time. A shorter completion time alone does not establish an improvement if the work is less accurate, fails acceptance, or creates extra downstream effort.
NIST cautions that indicators should validly measure the concept being claimed and that confounding can produce misleading associations. Its ARIA Pilot Evaluation Report describes model testing, red teaming and field testing as distinct levels of evaluation, and discusses measurement trees for assessing application validity. For a workplace trial, the practical implication is to define what “good work” means in the actual application rather than treating speed as a proxy for quality.
Report the comparison with its limits
Share enough detail for colleagues to understand what the result does—and does not—show. Include the task population, sample, tool and version, measurement period, comparison method, time results, quality or rework findings, and important differences between groups. Report uncertainty where you can; task difficulty and individual variation can affect averages. Statistical models may help evaluators interpret variance in benchmark settings, as discussed in NIST’s 2026 overview of statistical models for AI evaluation.
Rank #4
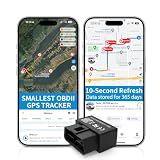
- 【5-day Free Trial】After the trial, continue subscription for $6.49/month with a 1-year plan ($77.88 total) or $8.99 month-to-month. SIM & data included.
- 【Plug & Play OBD2 GPS Tracker】Installs in seconds by plugging into your car’s OBDII port. Compact and lightweight (1.53" x 1.77" x 0.87", 1.2 oz), it’s a discreet hidden GPS tracker that won’t interfere with legroom or drain your car battery.
- 【Track Speed and Driver Behavior】Receive instant alerts for speeding, geo-fence breach, vehicle crashes, hard braking or rapid acceleration. Speeding threshold is customizable. Ideal teen driver GPS or elderly vehicle tracker.
- 【10-Second Real time, No Extra Charge】The fast refresh provides fleet manager or parents with accurate and real time location. Color-coded routes show speed changes visually.
- 【12-month Data History】All tracking data is securely stored with full confidentiality, allowing you to review up to 1 year of trip history.
A concise reporting format is: “For [defined task group] during [period], AI-assisted tasks took [measured time] versus [comparison time], with [quality/rework result] under [method].” Fill in those fields with observed team data. Keep conclusions within the scope of the tasks and conditions tested; a result from one workflow does not establish the same effect across an organization.
Independent reader supportYour contribution helps us test, update, and keep practical guides available for everyone.What published results can—and cannot—tell you
In a 2023 randomized experiment involving midlevel professional writing tasks, Noy and Zhang found a 40% decrease in average task time and an 18% increase in output quality for participants using ChatGPT. Those figures describe that experiment’s setting, not a forecast for every team, task or AI tool. Read the study’s abstract for its design and results.
Quick wins for a faster PC:
Repair Windows errors before they cause bigger problemsFix Now →Fix the driver behind crashes, sound loss and screen glitchesFind Drivers →Microsoft Research’s AI and Productivity Report—First Edition presents task-completion speed relative to comparison-group baselines and includes self-reported quality findings. Interpret its results study by study, with each task and comparison in view, rather than combining them into one estimate of team productivity.
There is no universal percentage of time saved established by these sources. NIST’s TEVV-Athlon Framework is a draft framework for customizing AI assessments to organizational objectives; its status was checked on October 7, 2026, and it should not be presented as finalized guidance.
Quick Recap
Product prices and availability are accurate as of the date/time indicated and are subject to change. Any price and availability information displayed on Amazon at the time of purchase will apply.

