
AI tokens are model-specific units used to process what you send to an AI and what it generates in reply. A token might be a character, part of a word, a whole word, or punctuation. Token counts help explain context limits and API usage, but there is no exact universal conversion from words to tokens.
What is an AI token?
Before an AI model processes text, its tokenizer divides that text into tokens. Common words may be kept whole, while longer or less common words may be split into pieces; spaces and punctuation can affect the split, too. As Google’s Gemini documentation puts it, “A token can be a single character like z or a whole word like cat.”
The exact tokenization depends on the model and its tokenizer. OpenAI notes that the same text can produce different counts depending on the model, encoding, and language. A token is therefore a unit of model input or output—not a fixed amount of text shared by every AI service. Google’s Gemini token guide and OpenAI’s token guide explain these differences.
How many words is one token?
There is no exact word-to-token conversion. As rough English-language estimates, OpenAI says one token is about four characters or three-quarters of a word. Google’s Gemini guide estimates about four characters per token, or 60–80 English words per 100 tokens. These are planning heuristics, not guarantees: actual counts depend on the specific model, text, language, and task.
Windows Errors? Fix Them Before They Spread
Repair common Windows errors and clear accumulated junk for a smoother, more stable PC - no reinstall needed.Free scan · no reinstallOutdated Drivers Are Slowing You Down
One free scan finds every outdated or missing driver and matches the right update for your exact hardware.Free scan · exact hardware match#1 Best Overall

- COMPLETE COUNTER SET: MTG abilities keywords counter wheel 123-piece MTG counter set includes keyword tokens and numeric (+X/-X)counters for comprehensive gameplay tracking. MTG bounty counters covering all essential MTG gameplay needs for formats like Commander, Modern, Draft, and more.
- SLEEK & FUNCTIONAL DESIGN: MTG token tracker circular wheel design with 7.5-inch diameter allows easy access to different counters. Features a stylish black base with alternate artwork for stat counters mtg(flying, vigilance, trample, etc.) and color-coded numeric counters for quick identification.
- GAME COMPATlBlLITY: Perfect accessory for MTG card games, mtg counters includes essential keyword counters like First Strike Flying, Defender, and Vigilance
- ORGANIZATION SYSTEM: TCG abilities keywords counter wheel Keeps counters neatly organized and readily accessible during gameplay, with clear icons and symbols for quick identification. MTG life counter helps track complex board states efficiently, reducing errors and keeping matches running smoothly.
- PERFECT FOR PLAYERS & COLLECTORS : Sturdy construction ensures counters stay securely in place during gameplay, while remaining easy to remove and adjust as needed.A must-have upgrade for serious MTG competitors and mtg spindown life counter an excellent gift for fellow MTG enthusiasts.
Do not apply those estimates as a reliable calculator for code, other languages, or image, audio, and video inputs. For a particular request, use the selected service’s token counter if available.
Why does my prompt use more tokens than its word count?
A usage count may cover much more than the visible text you typed. An API request can include system instructions, conversation history, message roles and boundaries, tool definitions, schemas, and attached files or images. Those structures and inputs can affect the model’s total input, even though a simple word counter does not include them.
Google documents tokenization for API inputs that include images, video, audio, and other non-text modalities. OpenAI’s counting guide also describes counting request structure, tools, schemas, images, and files. The complete request—not just the pasted prompt—is the useful unit to measure. OpenAI’s API token-counting guide describes counting a full Responses API input.
Rank #2

- MULTI-CURRENCY COIN AND TOKEN COUNTER: Counts different currency coins, token and chips for retail stores with adjustable thickness and diameter range (diameter range 14-34 mm, thickness range: 1.0 – 3.4 mm)
- BUILT TO COUNT LARGE QUANTITIES: Comes with batching options, off-sorting, auto-stop function, and anti-jamming function with a high speed of up to 2000 coins per minute (based on dimes)
- FEATURES: Facilitates counting, packaging, bagging coins or tokens. It has a total Hopper capacity of 4000 coins (1500 coins Internal Hopper + 2500 coins External Hopper Tray) based on dimes.
- COMPACT AND PORTABLE: Built-in handle for easy transportation. The external hopper easily folds over to make it compact and easy to store or transport.
- EASY TO USE AND RELIABLE: AB610 is a great option for retail stores, entertainment venues, amusement facilities, coin laundries, gas stations, vending businesses, and many other environments. Includes a 3 Year Warranty
What token categories can appear in usage?
Many APIs distinguish input tokens from output tokens. Input covers what the model receives; output covers what it generates. Depending on the provider, model, and endpoint, usage details may also report cached input, reasoning or thought tokens, tool-use tokens, or modality-specific counts. The field names and categories are not standardized across services.
What’s actually slowing this PC down?
Pick the symptom - the matching free tool is one click away.
Visible answer length is not always the same as output-token usage. OpenAI notes that output usage can include generated tokens that are not visible as answer text, such as reasoning or formatting in some cases. Google’s Gemini documentation describes usage fields for input, output, thought, cached content, tool use, and total tokens. Check the response fields for the exact API and model rather than assuming every service reports the same breakdown.
What does a context window mean?
A context window is a model-specific token capacity for processing a request or conversation. It is not a universal limit shared by all AI models. Google defines Gemini’s context window as the combined input and output limit. OpenAI says reasoning tokens count toward the context window for some models.
Rank #3
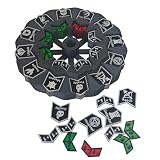
- COMPLETE COUNTER SET: MTG abilities keywords counter wheel 123-piece MTG counter set includes keyword tokens and numeric (+X/-X)counters for comprehensive gameplay tracking. Covering all essential MTG gameplay needs for formats like Commander, Modern, Draft, and more.
- SLEEK & FUNCTIONAL DESIGN: MTG token tcracker circular wheel desian with 7.5-inch diameter allows easy access to different counters. Features a stylish black base with alternate artwork for keywords (flying, vigilance, trample, etc.) and color-coded numeric counters for quick identification.
- GAME COMPATlBlLITY: Perfect accessory for MTG card games, includes essential keyword counters like First StrikeFlying, Defender, and Vigilance
- ORGANIZATION SYSTEM: TCG abilities keywords counter wheel Keeps counters neatly organized and readily accessible duringgameplay, with clear icons and symbols for quick identification. Helps track complex board states efficiently, reducing errors and keeping matches running smoothly.
- PERFECT FOR PLAYERS & COLLECTORS : Sturdy construction ensures counters stay securely in place during gameplay, whileremaining easy to remove and adjust as needed. A must-have upgrade for serious MTG competitors and an excellent gift for fellow MGT enthusiasts.
That means a long conversation or large request can leave less room for the model’s response. Check the current documentation for the chosen model and endpoint, and leave capacity for the expected output instead of treating the entire window as available for input. Google’s Gemini documentation and OpenAI’s token guide describe provider-specific context details.
How can I check how many tokens I used?
For an API request, count the full intended input before sending it when the provider offers a counter, then inspect the usage reported after the response. For everyday AI chat, available usage details depend on the product; API-level counters and billing reports should not be assumed to exist in every consumer app.
- Before sending: Use the provider’s counter with the complete payload. OpenAI documents an input-token counting endpoint for supported Responses API inputs, including text, messages, images, files, tools, and conversations. Google documents a
count_tokensmethod for Gemini input. - After receiving a response: Inspect the API response’s usage fields for input, output, and any additional categories the endpoint reports.
- For account-level tracking: Review the provider’s usage dashboard or account data when available. OpenAI’s help documentation describes both response-level usage fields and its Usage Dashboard.
Official instructions are available in OpenAI’s token-counting guide, Google’s Gemini token guide, and OpenAI’s usage and counting explanation.
Rank #4

- Complete Game Management Kit: Master your board state with a massive 167-piece set. This all-in-one bundle includes 80 dry-erase token cards, 80 matching circular counters, 5 vibrant colored markers with built-in erasers, and 2 cleaning cloths. Perfect for streamlining complex interactions in your favorite tactical card games.
- Effortless Customization & Reusability: Say goodbye to messy paper scraps. These high-quality cards feature a smooth dry-erase surface, allowing you to quickly draw custom creatures, note down temporary stats, or track life totals. Simply wipe clean with the included cloths and they are ready for the next round or session.
- Color-Coded for Instant Recognition: Stop the confusion during heated battles. With 5 distinct colors (Red, Blue, Green, Yellow, Black) and unique corner illustrations, you can easily categorize tokens, status effects, and triggers. The color-matched markers and counters ensure every player can identify the board state at a glance.
- Portable & Tournament Ready: Designed with standard dimensions (2.48inch x 3.46inch ), these token cards fit seamlessly alongside your existing deck. The compact 1.38inch counters are perfect for stacking on cards to track buffs or damage without cluttering the table. Ideal for home game nights or local competitive events.
- Durable Quality for Endless Sessions: Crafted from premium, wear-resistant materials, our tokens and counters are built to withstand heavy shuffling and frequent writing. The markers feature fine tips for detailed drawing and integrated erasers for quick on-the-fly adjustments, providing a professional upgrade to your gaming experience.
Do tokens determine what I pay?
For API products with billing enabled, token usage can contribute to cost. The billable categories and rates depend on the provider, model, endpoint, and billing arrangement; input, output, cached input, reasoning, media, or tools may be treated differently. Check the current pricing page for the exact model and endpoint, then use actual request usage rather than a rough word-count estimate.
This does not mean every AI subscription or consumer app charges per token. Billing rules for an API should not be inferred from a consumer plan. Google’s Gemini documentation and OpenAI’s API documentation explain token usage in their respective products, not a universal billing rule for every AI service.
What to compare when choosing an AI service
There is no universal provider ranking based on tokens. If token limits, measurement, or usage cost matter to your work, compare the details for the particular model and endpoint:
Quick Recap
- The tokenizer and how it handles your language and type of content.
- Which inputs are counted, including message structure, tools, files, images, audio, or video.
- Which usage categories are reported, such as input, output, cached, reasoning or thought, tool use, and modality-specific usage.
- How the context window is defined and which tokens consume it.
- Whether the provider supports pre-request counting and post-request usage inspection.
- Which categories are billed and the current rates for the model and endpoint you plan to use.
Product prices and availability are accurate as of the date/time indicated and are subject to change. Any price and availability information displayed on Amazon at the time of purchase will apply.

