
Recommended Free Tools
Ein lokal installiertes Ollama-Modell verarbeitet Prompts auf deinem Rechner; laut Ollama werden lokale Prompts und Daten nicht an das Unternehmen zurückgesendet. Das gilt jedoch nicht automatisch für Cloud-Modelle oder für einen lokalen Server, den du im Netzwerk erreichbar machst. Für ein möglichst abgeschottetes Setup: nutze zunächst die Standardadresse 127.0.0.1:11434, deaktiviere bei Bedarf Cloud-Funktionen und öffne den API-Zugriff nicht ungeprüft nach außen.
Was „lokal“ bei Ollama für deine Privatsphäre bedeutet
Entscheidend ist, wo das gewählte Modell ausgeführt wird. Ollama sagt, dass es Prompts und Daten nicht sieht, wenn ein Modell lokal läuft. Für Cloud-Modelle erklärt das Unternehmen dagegen, dass es Prompts und Antworten zur Bereitstellung des Dienstes verarbeitet, sie aber nicht speichert oder protokolliert und nicht zum Training nutzt. Das sind Angaben des Anbieters, keine unabhängige Datenschutzprüfung. Ollamas FAQ
Auch die API-Dokumentation unterscheidet die beiden Wege: Der lokale Server ist unter http://localhost:11434/api erreichbar; direkter Cloud-Zugriff erfolgt über https://ollama.com/api. Laut Dokumentation benötigen lokale Aufrufe keinen API-Schlüssel, Cloud-Aufrufe hingegen schon. Da ein lokaler Ollama-Server auch Cloud-Modelle verwenden kann, beweist eine Installation auf dem eigenen Rechner allein nicht, dass jede Anfrage lokal verarbeitet wird. Ollama-API-Dokumentation
Cloud-Funktionen bei Bedarf vollständig ausschalten
Wenn du Cloud-Modelle und Websuche ausschließen möchtest, dokumentiert Ollama zwei Einstellungen. Setze entweder die Umgebungsvariable OLLAMA_NO_CLOUD=1 oder trage disable_ollama_cloud: true in ~/.ollama/server.json ein. Starte den Ollama-Server danach neu. Cloud-Modelle und Websuche stehen dann nicht mehr zur Verfügung. Ollama: Cloud security
Windows Errors? Fix Them Before They Spread
Repair common Windows errors and clear accumulated junk for a smoother, more stable PC - no reinstall needed.Free scan · no reinstallCrashes, No Sound, or Screen Glitches?
Random freezes, missing sound and display glitches usually trace back to one bad driver. Find and replace yours safely.Free scan · under a minute#1 Best Overall

- EVOLUTION AMD RYZEN AI MAX+ 395 MINI PC - GMKtec EVO-X2 is the next evolution in AI mini PC Ryzen Strix Halo series. Thanks to AMD Simultaneous Multithreading (SMT) the core-count is effectively doubled, to 32 threads. Ryzen AI Max+ 395 has 64 MB of L3 cache and can boost up to 5.1 GHz, depending on the workload. The Ryzen AI Max+ 395 is currently rated as the "most powerful x86 APU" on the market for AI computing.
- AI NPU with XDNA 2 ARCHITECTURE - Powered by 16 “Zen 5” CPU cores, 50+ peak AI TOPS XDNA 2 NPU and a truly massive integrated GPU driven by 40 AMD RDNA 3.5 CUs, the Ryzen AI MAX+ 395 is a transformative upgrade and delivers a significant performance boost over the competition. The Ryzen AI Max+ 395 excels in consumer AI workloads like the llama.cpp-powered application: LM Studio. Shaping up to be the must-have app for client LLM workloads, LM Studio allows users to locally run the latest language model without any technical knowledge required and unleash their creativity and productivity.
- AMD RADEON 8090S iGPU GAMING PC - The AMD Radeon RX 8060S offers all 40 CUs with up to 2.9 GHz graphics clock and uses the new RDNA 3.5 architecture. The powerful iGPU is positioned between an RTX 4060 and 4070 laptop GPU and therefore enables gaming in FHD at maximum details in most demanding games. The 8060S can also utilize the full 64GB pool, which is perfect for running LLMs such as Deepseek 32B, which runs comfortably on this machine.
- EIGHT CHANNEL LPDDR5X - LPDDR5X is a new ground breaking memory small form factor installed on-board. With blazing speeds up to to 8000MT/s, it runs 1.5x faster than the DDR5 SODIMMs; 90% better performance over DDR5 SODIMMs in video conferencing and photo editing; 30% better performance in productivity apps; 4% better performance in digital content workloads.
- QUAD SCREEN 8K DISPLAY SUPPORT - EVO-X2 AI Mini PC support 4-screen 4K/8K output via HDMI 2.1 (8K@60Hz), DisplayPort 1.4 (4K@60Hz), and dual USB 4 40Gbps Transfer speed (supporting PD3.0/DP1.4/DATA). Ideal for gaming, video editing, and multitasking, it provides expansive and crisp multi-display support.
Ollama-API: localhost als Sicherheitsgrenze verstehen
Ollama dokumentiert: “Ollama binds 127.0.0.1 port 11434 by default.” Ollama-FAQ Die Adresse 127.0.0.1 ist die Loopback-Adresse: Der Dienst ist standardmäßig für Programme auf demselben Rechner erreichbar, nicht automatisch für andere Geräte im Heimnetz. Das ist der richtige Ausgangspunkt, wenn nur lokale Nutzung nötig ist.
Warum das Öffnen des Zugriffs die Lage ändert
Die Einstellung OLLAMA_HOST kann die Bindeadresse ändern. Damit lässt sich der Server beispielsweise für andere Geräte erreichbar machen; auch Reverse-Proxys und Tunnel sind technische Möglichkeiten, die Ollama dokumentiert. Sie sind keine Sicherheitsgarantie. Die herangezogenen Ollama-Dokumente bestätigen keine eingebaute Authentifizierung für direkt exponierte lokale API-Aufrufe. Behandle daher jede Änderung von localhost als bewusste Ausweitung der Angriffsfläche, nicht als harmlose Komfortoption. Ollama-FAQ · API-Dokumentation
Rank #2

- Unlock next-generation AI computing with AMD Ryzen AI Max+ 395 processor featuring 16 cores, 32 threads, up to 5.1GHz boost clock, and integrated Ryzen AI engine delivering up to 126 TOPS AI performance. EVO-X3 is designed for local AI models, content creation, development, and professional workloads.
- OCuLink External GPU Expansion – Upgrade Beyond a Mini PC: Take your graphics performance further with a dedicated OCuLink (PCIe 4.0 x4) interface. Connect an external GPU dock to add desktop-class graphics power for AAA gaming, AI acceleration, 3D rendering, video production, and advanced creative applications. EVO-X3 gives you the flexibility of a compact PC with workstation-level expansion capability.
- AI NPU with XDNA 2 ARCHITECTURE - Powered by 16 “Zen 5” CPU cores, 50+ peak AI TOPS XDNA 2 NPU and a truly massive integrated GPU driven by 40 AMD RDNA 3.5 CUs, the Ryzen AI MAX+ 395 is a transformative upgrade and delivers a significant performance boost over the competition. The Ryzen AI Max+ 395 excels in consumer AI workloads like the llama.cpp-powered application: LM Studio. Shaping up to be the must-have app for client LLM workloads, LM Studio allows users to locally run the latest language model without any technical knowledge required and unleash their creativity and productivity.
- AMD RADEON 8090S iGPU GAMING PC - The AMD Radeon RX 8060S offers all 40 CUs with up to 2.9 GHz graphics clock and uses the new RDNA 3.5 architecture. The powerful iGPU is positioned between an RTX 4060 and 4070 laptop GPU and therefore enables gaming in FHD at maximum details in most demanding games. The 8060S can also utilize the full 128GB pool, which is perfect for running LLMs such as Deepseek 70B Q8, which runs comfortably on this machine.
- EIGHT CHANNEL LPDDR5X - LPDDR5X is a new ground breaking memory small form factor installed on-board. With blazing speeds up to to 8000MT/s, it runs 1.5x faster than the DDR5 SODIMMs; 90% better performance over DDR5 SODIMMs in video conferencing and photo editing; 30% better performance in productivity apps; 12% better performance in digital content workloads.
- Ändere
OLLAMA_HOSTnicht, wenn kein anderer Rechner auf die API zugreifen muss. - Vermeide eine direkte Freigabe der API ins öffentliche Internet.
- Wenn Zugriff im Heimnetz erforderlich ist, begrenze ihn auf vertrauenswürdige Geräte und sichere den vorgelagerten Zugang mit Authentifizierung und Netzwerkregeln. Ein Proxy oder Tunnel allein ersetzt diese Kontrollen nicht.
Exponierte Endpunkte werden automatisiert gesucht
Eine am 24. September 2026 veröffentlichte arXiv-Preprint-Studie von Karina Elzer, Niklas Netterstrøm Johansen und Emmanouil Vasilomanolakis untersuchte vier Honeypots, die eine Ollama-API ohne echtes Modell nachbildeten. Über 84 Tage registrierten die Autoren 290.887 Interaktionen von 2.793 eindeutigen Quell-IP-Adressen. Sie berichten unter anderem von automatisierter Suche und Fingerprinting sowie Versuchen mit Path Traversal, SSRF, RCE- und Kryptomining-Payloads, Ressourcenerschöpfung, Prompt Injection und Datenextraktion. Das sind Messwerte dieser vier Honeypots, keine Schätzung aller Ollama-Installationen und kein Beleg, dass jede exponierte Instanz kompromittiert wird. Elzer, Johansen und Vasilomanolakis, 2026
Independent reader supportYour contribution helps us test, update, and keep practical guides available for everyone.Installation planen: Speicher und Hardware
Modellordner und freien Speicher berücksichtigen
Modelldateien belegen Platz auf dem Laufwerk. Ollama nennt diese Standardpfade: ~/.ollama/models unter macOS, /usr/share/ollama/.ollama/models bei der Linux-Installation laut FAQ und C:Users%username%.ollamamodels unter Windows. Mit OLLAMA_MODELS kannst du einen anderen Speicherort festlegen, etwa ein separates Laufwerk. Plane den benötigten Platz anhand der Modelle, die du tatsächlich verwenden willst; die Dokumentation empfiehlt keine pauschale Laufwerkskapazität. Ollama-FAQ
Do these 3 things before closing this tab:
1Repair Windows errors before they cause bigger problems2Fix the driver behind crashes, sound loss and screen glitches3Clear out junk files and repair common Windows errorsRank #3
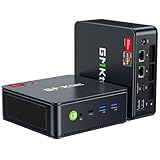
- VALUE & PERFORMANCE MINI PC - GMKtec Nucbox M6 Ultra Series is equipped with the powerful AMD Ryzen 5 7640HS processor. This CPU is an upper mid-range processor (APU) of the Phoenix product family. It has 6 SMT-enabled Zen 4 cores (12 threads) running at 4.3 GHz base speed to turbo boost 5.0 GHz.With a TDP Boost of 45W-60W, the Ryzen 7640HS CPU is more energy efficient and delivers a 30% Performance increase over previous AMD Ryzen 7 6800H, 6600U.
- 32GB DDR5 RAM & 1TB PCIe SSD - Installed with DDR5 32GB RAM SO-DIMM Dual Channel (2x16GB), the Nucbox M6 Ultra mini pc support expansion to 128GB RAM. Featured with 1TB M.2 2280 PCIe 3.0 SSD, support dual slot expansion to PCIe 4.0 8TB SSD. (Upgrades not included)
- GAMING PC - The Radeon 760M iGPU has 8 CUs (512 shaders) running at up to 2,600 MHz. This desktop computer can play moderate gaming at a steady FPS, it also HW-encodes and HW-decodes the most widely used video codecs such as AV1, HEVC and AVC.
- DUAL NIC LAN 2.5G RJ45 - Fast Network Speeds: Enjoy up to 2500Mbps data transmission speed without worrying about lagging. Ideal for working, gaming, and surfing the internet. Great for Untangle, Pfsense or as a server office PC.
- TRIPLE 4K DISPLAY - Unlock unparalleled productivity with support for three simultaneous displays, including a stunning 8K@60Hz via USB4, plus 4K@60Hz through both HDMI 2.0 and DisplayPort, transforming your workspace into a command center for multitasking and immersive entertainment.
CPU oder unterstützte GPU
Eine GPU ist optional. Ollamas Dokumentation führt unterstützte NVIDIA- und AMD-Hardware samt Plattform- und Treiberhinweisen auf und nennt Metal für Apple-Geräte. Ob Beschleunigung verfügbar ist, hängt also von GPU, Betriebssystem und Treibern ab. RAM und VRAM begrenzen, welche Modelle geladen und wie viele Anfragen gleichzeitig verarbeitet werden können. Es gibt deshalb keine pauschale Mindest-VRAM-Zahl, die für alle Modelle und Einsatzzwecke gilt. Wähle zuerst ein konkretes Modell und berücksichtige gewünschte Kontextlänge, Betriebssystem und vorhandene Hardware. Ollamas Hardware- und Plattformhinweise · Ollama-FAQ
Quick Recap
Best Value

- 🚨 Your Productivity AI Companion: Built for designers, editors, creators and studios, IT13 Max blends cloud AI inspiration with local NPU acceleration while keeping files private. For stable 24/7 workflows, it features quiet cooling, solid construction, original-grade SSD flash and rigorous testing. Backed by a 3-year warranty, it is a reliable Productivity AI Companion
- ➊ 3-Year Warranty + Precision Engineering for Long-Term Reliability & Business Use: From design to components, GEEKOM maintains highest quality standards. Each unit undergoes rigorous reliability testing for stable, long-term operation. Backed by a 3-year official warranty – peace of mind for home and business. Stable, durable, reliable. More than performance – a trusted partner (𝙂𝙚𝙩 𝘽𝙧𝙖𝙣𝙙-𝘿𝙞𝙧𝙚𝙘𝙩 𝙎𝙪𝙥𝙥𝙤𝙧𝙩: 𝙂𝙀𝙀𝙆𝙊𝙈 𝙊𝙛𝙛𝙞𝙘𝙞𝙖𝙡 𝙒𝙚𝙗𝙨𝙞𝙩𝙚)
- ➋ Intel Core Ultra 9 185H (TDP 65W) 2–3× AI Power for Developers & Engineers:2× faster graphics, 2–3× higher AI power, 20–30% faster video editing than i9. Run LLMs, computer vision, and ML workloads locally – no cloud latency, no privacy concerns. From AI inference to model training, this mini PC handles it all. For scientists, engineers, developers, and creatives – a ready-to-deploy productivity machine for intensive workloads
- ➌ Why pay more for less? 16GB DDR5 (higher bandwidth, better stability)+1TB SSD. Outperforms traditional desktops at a lower cost. Run office apps, edit 4K video in DaVinci Resolve (Linux or Windows), or handle heavy creative workloads – smooth and responsive. Desktop power, mini PC convenience. Smaller, more efficient, space-saving
- ➍ Silent Operation with IceBlast 3.0 for Hospitals, Schools & Shared Environments: Tired of loud fans disrupting patient care or classrooms? IT13 MAX with IceBlast 3.0 delivers 65W sustained performance while whisper-quiet – 40% quieter than typical mini PCs. Deploy in hospital nurse stations, school computer labs, or work late without waking family. High-performance computing – without the noise
Rank #4

- 【High-Performance APU】The MS-S1 MAX features an AMD Ryzen AI Max+ 395 APU, integrating a Zen 5 architecture CPU (up to 5.1GHz, 16C/32T, 64M L3 Cache), an RDNA 3.5 GPU, and an NPU (50 TOPS). The total system output is 126 TOPS. It provides powerful parallel computing capabilities for demanding AI workflows. It is ideal for running local LLMs, multimodal models, and computationally intensive tasks
- 【128GB UMA Memory】Equipped with up to 128GB of LPDDR5x-8000MT/s unified memory, it enables the CPU and GPU to access a shared, high-bandwidth memory pool with extremely low latency. Ideal for large-scale AI inference, 3D workloads, and complex timelines in video editing. It eliminates traditional VRAM bottlenecks, ensuring smoother data transfer during high-intensity computations. The UMA design maximizes performance stability under high loads
- 【Flexible Expansion】The MS-S1 MAX features USB4 V2 (up to 80Gbps), dual 10GbE LAN, HDMI 2.1 (up to 8K60), a full-length PCIe x16 expansion slot, and dual M.2 slots supporting up to 16TB RAID 0/1. Wi-Fi 7 provides stronger signal coverage and a more stable wireless experience. The slide-out design facilitates upgrades and maintenance. It easily adapts to personal, studio, or rack-mount enterprise environments
- 【High-Efficiency Cooling System】Utilizing an aerospace-grade aluminum alloy chassis, copper base plate, six heat pipes, dual turbine fans, and advanced PCM thermal conductive material, it maintains stable cooling performance even under continuous load. This system supports 130W continuous power and 160W peak power operation, with a built-in 320W power supply. It boasts multiple global certifications including CCC, FCC, UL, CE, and UKCA, ensuring stable and reliable operation in various environments
- 【Cluster Design】Two MS-S1 MAX units can be configured as a dual-unit cluster to run a large 235B Q4 model locally, achieving an output speed of 10.87 tok/s. Supporting 2U rack deployment, multiple MS-S1 MAX units can be cascaded into a distributed cluster to create a high-efficiency AI computing center. A cluster of four MS-S1 MAX units successfully ran a DeepSeek-R1 671B Q4 large model. A reserved cluster power-on interface allows for unified start-up and shutdown
Checkliste für ein möglichst privates Setup
- Modellweg prüfen: Nutze ein lokales Modell, wenn Anfragen lokal bleiben sollen; eine lokale Installation schließt Cloud-Modelle nicht automatisch aus.
- Cloud-Funktionen abschalten, falls nötig: Setze
OLLAMA_NO_CLOUD=1oder aktivieredisable_ollama_cloud: truein~/.ollama/server.json, danach den Server neu starten. - Bindeadresse beibehalten: Lass Ollama auf
127.0.0.1:11434, wenn nur Anwendungen auf demselben Rechner zugreifen sollen. - Freigaben bewusst absichern: Falls andere Geräte Zugriff benötigen, beschränke den Zugang auf vertrauenswürdige Clients und setze Authentifizierung sowie Netzwerkbegrenzung vor die API; veröffentliche sie nicht ungeschützt im Internet.
- Ressourcen vorab prüfen: Berücksichtige Modellgröße und verfügbaren Speicherplatz sowie RAM oder VRAM, Betriebssystem und Treiber.
Product prices and availability are accurate as of the date/time indicated and are subject to change. Any price and availability information displayed on Amazon at the time of purchase will apply.

