
Red Hat AI Factory with NVIDIA is a jointly supported software platform, not a single physical factory or turnkey appliance. Announced on February 24, 2026, it combines Red Hat AI Enterprise and the Red Hat hybrid-cloud platform with NVIDIA AI Enterprise, accelerated-computing software and infrastructure. The goal is to move model, retrieval-augmented generation (RAG), agent and inference workloads from experimentation into supported production across on-premises, cloud and edge environments.
What Red Hat AI Factory with NVIDIA is
Red Hat describes the offering as a co-engineered enterprise AI foundation. Red Hat supplies OpenShift, AI engineering capabilities and enterprise operations; NVIDIA contributes AI software, models, microservices, networking and accelerated-computing technologies. The result is intended to give organizations one supported architecture for developing, customizing, deploying and operating AI applications across a hybrid cloud.
The announcement does not mean Red Hat and NVIDIA opened a data center or are selling one standardized machine. Infrastructure is assembled through supported servers, GPUs, networking and software configurations. Red Hat named Cisco, Dell Technologies, Lenovo and Supermicro among the systems manufacturers supporting the platform, but that does not certify every model or configuration from those companies.
What the platform includes
Red Hat software
- Red Hat OpenShift: the Kubernetes-based hybrid-cloud platform used to run and manage workloads on bare metal, virtualized infrastructure and public or private clouds.
- Red Hat AI Enterprise and Red Hat AI capabilities: tools and services for AI engineering, model work, application deployment and enterprise operations.
- Red Hat AI Inference Server: an inference option documented in the deployment architecture.
- Red Hat quickstarts: starting points for building AI and agent applications.
NVIDIA software and hardware integration
- NVIDIA AI Enterprise: the enterprise AI software layer integrated with Red Hat AI Enterprise.
- NVIDIA NIM: deployable inference microservices for serving models.
- NVIDIA NeMo: tools for model development and customization.
- CUDA-X libraries: accelerated libraries used by AI and data workloads.
- GPU Operator: the OpenShift operator used to install and manage NVIDIA GPU software.
- Network Operator: an optional component for NVIDIA networking capabilities.
- DOCA and related networking software: technologies for accelerated data-center and infrastructure functions.
- NVIDIA Blueprints: reference patterns for agent development and other AI workflows.
- NVIDIA Dynamo and llm-d: technologies identified for distributed model serving.
How it works with OpenShift
NVIDIA’s deployment guide describes an OpenShift-centered workflow. Exact commands and supported versions depend on the current hardware and software support matrices, so administrators should use the release-specific documentation rather than treating this sequence as a universal installation script.
Do these 3 things before closing this tab:
1Scan for outdated or missing drivers - takes under a minute2Clear out junk files and repair common Windows errors3Fix the driver behind crashes, sound loss and screen glitches#1 Best Overall

- NVIDIA Volta GV100 Architecture — 4,608 CUDA Cores, 640 1st-Gen Tensor Cores delivering 14 TFLOPS FP32 and 112 TFLOPS deep learning performance for AI training, inference, HPC, and scientific computing workloads
- 32GB HBM2 ECC Memory — 900 GB/s Bandwidth — High-bandwidth memory on a 4096-bit bus with ECC error correction provides the memory capacity and throughput required for the largest AI models, simulations, and datasets
- PCIe 3.0 x16 Interface — 250W TDP — Standard PCIe Gen3 connectivity with passive cooling designed for enterprise rack server deployment in HPE ProLiant, Dell PowerEdge, and Supermicro platforms with adequate chassis airflow
- NVLink — Scale to 96GB Unified Memory — Connect two V100 GPUs via NVLink at 300 GB/s bi-directional bandwidth to scale GPU memory from 32GB to 96GB for larger AI training and HPC workloads
- Multi-Precision Computing — Supports FP64 (7 TFLOPS), FP32 (14 TFLOPS), FP16 (112 TFLOPS) and INT8 precision modes for flexible deployment across training, inference, and scientific simulation workloads
- Prepare OpenShift. Build or obtain an OpenShift cluster on supported bare-metal, virtualized, private-cloud or public-cloud infrastructure.
- Provide NVIDIA access. Obtain the required NVIDIA AI Enterprise entitlement and configure an NVIDIA NGC API key. The key is required to pull NVIDIA AI Enterprise container images, including NIM images.
- Install GPU software. Deploy the NVIDIA GPU Operator in the cluster so GPU drivers and related components are managed as Kubernetes resources.
- Add networking components when needed. Install the NVIDIA Network Operator if the workload requires the documented accelerated networking features.
- Deploy the workload. Use Red Hat AI capabilities, quickstarts or NVIDIA Blueprints to package and run development, RAG, fine-tuning, evaluation and application services.
- Deploy inference. Choose the appropriate serving path, such as Red Hat AI Inference Server or NVIDIA NIM, and configure model, GPU, storage, networking and observability settings for the workload.
- Scale distributed serving where required. The architecture identifies llm-d and NVIDIA Dynamo for distributed serving patterns; capacity and performance still have to be validated against the organization’s own models and service-level objectives.
Which AI workloads it targets
Agent development
Teams can start with NVIDIA Blueprints and Red Hat quickstarts to build agentic applications. These are reference patterns and development aids, not a promise that every agent design will be production-ready without additional engineering, security review and evaluation.
RAG and fine-tuning
The documented workflow supports connecting models to enterprise data for retrieval-augmented generation and customizing models through fine-tuning. Data location, access controls, vector-store design, retention and regulatory requirements remain the customer’s responsibility.
Model evaluation
Evaluation is a distinct stage in the stack. Organizations can test quality, safety and task performance before promoting a model or agent to production, but the platform does not establish a universal accuracy threshold.
Rank #2
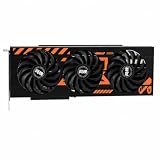
- GPU-Modell: Gefoce RTX 3080
- Memory Type: GDDR6X Memory Capacity: 20GB Memory Bus Width: 320bit Output Interfaces: 3*DP + HDMI Core Clock: 1710MHz Memory Clock: 19Gbps Power Interface: 8+8pin Recommended Power Supply: 850W or higher
Inference and distributed serving
Red Hat AI Inference Server and NVIDIA NIM provide documented inference routes. llm-d and NVIDIA Dynamo address distributed-serving patterns. Actual latency, throughput, GPU utilization and reliability depend on the model, quantization, prompt sizes, concurrency, hardware and network design.
Where it can run
OpenShift supports the deployment patterns described for Red Hat AI Factory with NVIDIA, including:
| Environment | What it means for a deployment |
|---|---|
| On premises | Organizations operate servers, GPUs, networking, data and cluster lifecycle in their own facilities. |
| Private cloud | The stack runs in an organization-controlled cloud environment with its own security and policy boundaries. |
| Public cloud | OpenShift can be deployed on providers named in the guide, including AWS, Microsoft Azure and Google Cloud, subject to current support requirements. |
| OpenStack | OpenShift deployments can use OpenStack-based infrastructure where the required versions and hardware are supported. |
| Edge | Smaller or distributed sites can be considered, but capacity, connectivity, hardware qualification and operational support must be checked for the specific design. |
What an enterprise should evaluate before buying
Workload and data placement
Decide which data and services must remain on premises, which can run in a public cloud, and whether the same controls and model versions must span both.
Rank #3
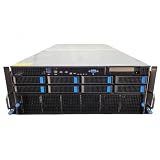
- No Processor Installed; Supports 2x AMD EPYC 9004 Series Processors
- No Memory Installed; Supports 24x DDR5 4400/4800 Regsitered Memory Modules
- 8x 3.5" Trays; (Bring Your Own SATA/NVMe Drives)
- 4x H200 NVL Tensor Core 141GB HBM3e PCI Express 5.0 x16 GPU Accelerator Card
- In Original Packaging; Includes Rails and ASUS GPU Cables
Existing investments
Inventory OpenShift clusters, NVIDIA GPUs, networking, storage, identity, monitoring and platform-operations skills. Reusing these investments may simplify adoption, while missing capabilities can materially change the project scope.
Model and application requirements
Define whether the priority is private-data RAG, fine-tuning, agent development, batch processing or interactive inference. Record model sizes, context lengths, concurrency and availability targets.
PC Slower Than It Used to Be?
A free scan shows the junk files, broken settings and background clutter dragging Windows down - then fixes them in one click.Free scan · Windows 10 & 11Crashes, No Sound, or Screen Glitches?
Random freezes, missing sound and display glitches usually trace back to one bad driver. Find and replace yours safely.Free scan · under a minuteSecurity and governance
Require an explicit design for tenant isolation, secrets, image provenance, data access, audit logs, model-risk controls, vulnerability response and regulatory obligations. A supported software stack does not automatically satisfy an organization’s compliance requirements.
Rank #4

- 【Brilliant AI Performance for production】 on-device processing with up to 100 TOPS AI performance with low power and low latency, Due to the high thermal demands of Super mode, only the J30 Series supports upgrading to Super mode via the JetPack 6.2 update
- 【Hand-size edge AI device】 compact size at 130mm x120mm x 58.5mm, includes NVIDIA Jetson Orin NX 16GB production module, a cooling fan with a heatsink, enclosure, and a power adapter. Support desktop, wall mount, fit in anywhere
- 【Expandable with rich I/Os】4x USB 3.2, HDMI 2.1, 2xCSI, 1xRJ45 for GbE, M.2 Key E, M.2 Key M, CAN, and GPIO
- 【Accelerate solution to market】pre-installed Jetpack with NVIDIA JetPack 5.1 on the included 128GB NVMe SSD, Linux OS BSP, 128GB SSD, support Jetson software and leading AI frameworks and software platforms
- 【Comprehensive certificates】FCC, CE, RoHS, UKCA
Capacity and service levels
Benchmark the intended workload on the proposed GPU and network configuration. Vendor statements about higher performance, lower cost, better utilization or faster deployment are claims about the platform’s intended benefits, not independent comparative measurements established by the cited materials.
Commercial and operational ownership
Clarify who supplies servers and GPUs, who licenses and supports each software layer, how upgrades are coordinated, and who responds when a problem crosses the Red Hat, NVIDIA and hardware boundaries. Public pricing, a complete bill of materials and a full licensing comparison were not provided in the announcement materials.
Independent reader supportYour contribution helps us test, update, and keep practical guides available for everyone.How procurement and implementation may be organized
Red Hat’s datasheet says buyers can engage an OEM, solution provider or distributor. Red Hat Consulting and Training are also identified as implementation and enablement options. Those routes can help with architecture, deployment and skills, but the right channel depends on the chosen hardware, region, contract terms and existing Red Hat agreement.
The Tool Desk
Outbyte PC Repair FREEClear out junk files and repair common Windows errorsFree Scan →Outbyte Driver Updater FREEFix the driver behind crashes, sound loss and screen glitchesFind Drivers →Best Value

- Supercomputer performance directly to your desk in a compact, energy-efficient design, enabling enterprise-scale AI and high-performance computing right where you need it.
- The power of Grace Blackwell architecture, delivering up to 1 petaFLOP of AI performance for local model fine-tuning, inference, and analytics, accelerating your time-to-solution.
- Designed from the ground up to build and run AI, delivering seamless integration of the full NVIDIA AI software stack —so you can develop locally and deploy anywhere.
- NVIDIA DGX Spark gives you the freedom to experiment, prototype, and innovate faster by augmenting laptop, desktop, cloud, or data center resources. With more power to learn, prototype, test, and innovate, NVIDIA DGX Spark delivers exceptional ROI for increased productivity.
- Use NVIDIA DGX Spark to unlock new ideas and experiment with large models (up to 200 billion parameters at FP4) directly on your desktop with 128GB of unified memory. Empower rapid testing, validation, and iteration—driving innovation in a secure, high-performance setting.
What the announcement does—and does not—prove
| Established by the announcement and deployment materials | Not established by those materials |
|---|---|
| The offering was announced February 24, 2026 and was described as available at announcement. | A single physical AI factory, appliance or fixed hardware configuration. |
| Red Hat AI 3.5 is currently described on Red Hat’s product page as generally available and included in the offering. | That every OEM model or GPU configuration has identical certification or commercial terms. |
| Red Hat AI Enterprise and NVIDIA AI Enterprise are integrated in a jointly supported software solution. | Independent benchmarks proving superior cost, speed, utilization or latency. |
| The documented stack covers development, RAG, fine-tuning, evaluation, inference and distributed serving patterns. | A guarantee that any particular model or agent will meet a customer’s service-level objective. |
| OpenShift deployment patterns include bare metal, virtualized infrastructure and named public and private clouds. | Public pricing, a complete hardware bill of materials or a universal licensing comparison. |
Statements from the companies
Justin Boitano, NVIDIA’s vice president of Enterprise AI Platforms, said the platform is intended to provide a software foundation for production-grade infrastructure and software spanning the hybrid cloud. Chris Wright, Red Hat’s chief technology officer and senior vice president of Global Engineering, described it as a way to move from experimentation to enterprise-wide production using a stable hybrid-cloud foundation. These are executive statements from the vendors, not independent validation.
The Bottom Line
Red Hat AI Factory with NVIDIA is best understood as a jointly supported OpenShift-centered software stack for enterprise AI—not a physical factory. Its value will depend on how well the integrated Red Hat and NVIDIA layers fit an organization’s existing infrastructure, governance model, workloads and measured production requirements.
Quick Recap
Product prices and availability are accurate as of the date/time indicated and are subject to change. Any price and availability information displayed on Amazon at the time of purchase will apply.

