StyleTTS 2
StyleTTS 2: A research-focused TTS model for expressive synthesis, adaptation, and custom training. Ranked #122 of 222 in Text-to-Speech Software by our editors (3.0/10); pricing: Open source; best for researchers training and adapting speech models.
At a glance
- Editor score3.0 / 10
- PricingOpen source
- Best forResearchers training and adapting speech models
- Paid fromFree
- Facts checked20 Sep 2026
Where it wins
- Supports single-speaker and multispeaker speech synthesis
- Enables zero-shot speaker and speaking-style replication
- Includes fine-tuning and custom-language training support
Where it doesn't
- Distributed as source code for local deployment
- Coverage is limited to Windows, Linux, and self-hosted use
- Cloned-voice use requires disclosure without permission
Our verdict on StyleTTS 2
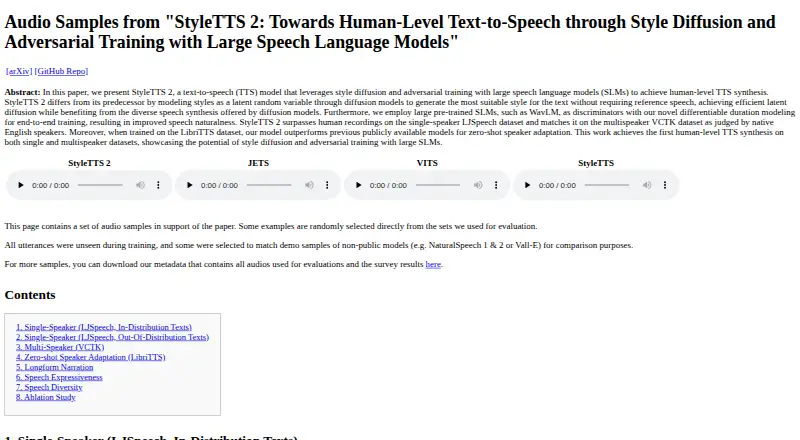
StyleTTS 2 is an open-source text-to-speech model for researchers and developers building local speech-synthesis workflows. It supports single-speaker and multispeaker synthesis, zero-shot speaker adaptation from reference audio, voice and speaking-style replication, and model fine-tuning for new speakers. Pretrained LJSpeech and LibriTTS checkpoints provide starting points for inference and training, while custom datasets and languages are also supported.
Its main distinction is the combination of style diffusion and adversarial training with speech language models. Style diffusion supports latent speech-style generation, giving the project a research-oriented approach to expressive speech rather than a narrow single-voice synthesis workflow. Reference-audio adaptation and replication extend that focus to speaker identity and delivery style, while the included training and inference code supports experimentation with new speakers, datasets, and languages.
StyleTTS 2 is a better fit for teams that want source code, pretrained checkpoints, and self-hosted control than for buyers seeking a hosted subscription service. The project is distributed for local deployment across Windows, Linux, and self-hosted environments, so its value depends on a development workflow around models and code. Voice replication also comes with a disclosure condition: synthesized speech must be disclosed when using pretrained models unless permission exists to use the cloned voice. Choose it for research, adaptation, and custom model training; choose a hosted commercial TTS service instead if you need a managed product experience.
Your product? Our editors can test StyleTTS 2 in depth and publish a review, labelled as paid · from $149/mo →
StyleTTS 2 pricing
StyleTTS 2 fact sheet
| Free plan | Not verified |
|---|---|
| Paid from | Free |
| Commercial use | Not verified |
| Voice cloning | Yes |
| API access | Not verified |
| Languages | Not verified |
| Maximum input | Not verified |
| Export formats | Not verified |
| Platforms | windows, linux, self_hosted |
| Deployment | Self-hosted |
| Platforms | Windows, Linux |
| Support | Community, Docs |
| Built for | Solo, Small business, Mid-market, Enterprise (editorial estimate) |
| Pricing | Open source |
| Website | styletts2.github.io |
| Facts checked | 20 Sep 2026 |
Alternatives to StyleTTS 2
- ElevenLabsAffordable voice cloning with multilingual generation, dubbing, streaming, and API access.9.4
- Google Cloud Text-to-SpeechA broad, API-only TTS service for developers building voice-enabled products.9.3
- Azure AI SpeechA broad, production-ready TTS platform for teams building voice applications.9.2


See all StyleTTS 2 alternatives →
Used StyleTTS 2? Be the first to review it
The editor score above is our own research. What this page doesn't have yet is a reader's view — what you used StyleTTS 2 for, what worked and what didn't. No stars are seeded and no review is paid for; an editor reads every one before it appears.
Write a reviewTwo minutes · verified accounts only · read by an editor before it appears
Featured on iTechGuides
StyleTTS 2 is listed in our Text-to-Speech Software directory. Add the badge to your site — it links back to this page.
<a href="https://www.itechguides.com/products/styletts-2/"><img src="https://www.itechguides.com/best/badge/styletts-2.svg" alt="Featured on iTechGuides" width="230" height="46"></a>
Reviewed by iTechGuides Editors · Editorial team · Updated Oct 2026
Advertiser disclosure: iTechGuides is reader-supported. Vendors can pay for top positions in our rankings and for a place on other products' pages, and we may earn a commission when you click some links. Bought places stand at the number bought; this page and our disclosure say so. Paying vendors may get a fuller, more detailed review from our editors, and that review can change their score. How we rank.
Last updated · How we research and update