
Pydantic Evals
Pydantic Evals: A flexible open-source choice for Python teams defining LLM evaluations in code. Ranked #16 of 30 in AI LLM Evaluation Tools by our editors (7.9/10); pricing: Free plan; best for python teams wanting code-defined evaluations.
At a glance
- Editor score7.9 / 10
- PricingFree plan
- Best forPython teams wanting code-defined evaluations
- Free planYes
- Paid fromFree
- Safety evaluationsYes
- Facts checked22 Sep 2026
Where it wins
- Supports deterministic, custom, LLM-judge, performance, span, and trajectory checks
- Defines datasets and test cases in Python, YAML, or JSON
- Works across listed providers including OpenAI, Anthropic, Gemini, and Bedrock
Where it doesn't
- Requires running the Python package locally in a self-hosted setup
- Verified integrations center on Pydantic Logfire and OpenTelemetry
- Pydantic Logfire visualization is a separate service with separate pricing
Our verdict on Pydantic Evals
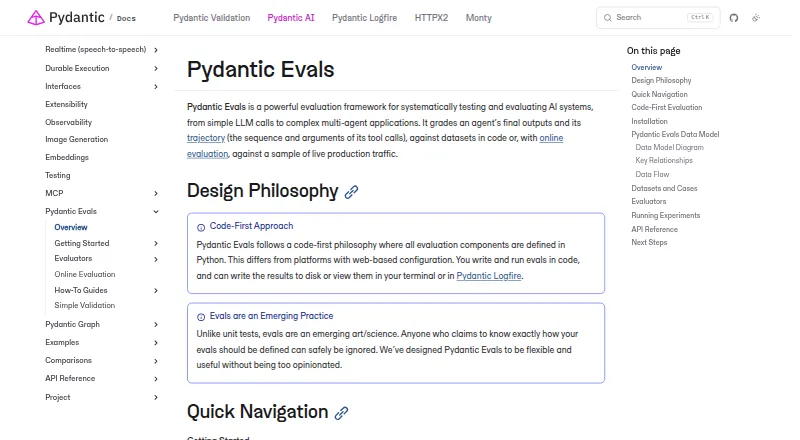
Pydantic Evals is an open-source Python framework for testing and evaluating AI systems, from individual LLM calls to multi-agent applications. It is aimed at development teams that want datasets, test cases, tasks, evaluators, and experiments defined in code or serialized as YAML and JSON. The framework supports deterministic checks, custom metrics, LLM-as-a-judge evaluation, performance checks, span-based evaluation, agent-trajectory analysis, online evaluation of live functions, safety evaluations, prompt versioning, and API access. Its natural audience is Python teams that prefer a programmable evaluation workflow over a separately hosted SaaS product.
Evaluation depth is the main reason to consider it. Built-in deterministic evaluators can cover repeatable checks, while custom evaluators, G-Eval, LLM judges, report evaluators, duration checks, and span-based analysis support more flexible review criteria. Agentic trajectory evaluation extends the scope beyond isolated model responses. The published provider coverage includes OpenAI, Anthropic, Gemini, xAI, Bedrock, Cerebras, Cohere, Groq, Hugging Face, Mistral, OpenRouter, and other listed Pydantic AI providers. Results can be printed or serialized, and the optional Pydantic Logfire integration adds visualization and observability around experiments and runs.
The trade-off is operational rather than feature-related: Pydantic Evals is a library that runs locally, so teams need to manage the Python environment and self-hosted workflow themselves. Its ecosystem fit is centered on Pydantic Logfire and OpenTelemetry rather than a broad set of verified integrations. Teams that want code-defined control, multiple evaluation methods, and provider flexibility should consider it. Teams seeking a fully hosted evaluation workspace or a wider prebuilt integration ecosystem should look elsewhere.
Your product? Our editors can test Pydantic Evals in depth and publish a review, labelled as paid · from $149/mo →
Pydantic Evals pricing
Pydantic Evals fact sheet
| Free plan | Yes |
|---|---|
| Paid from | Free |
| Evaluation methods | Deterministic checks; custom evaluators; LLM judges; G-Eval; performance checks; report evaluators; span-based evaluation; agentic trajectory evaluation |
| Model support | OpenAI; Anthropic; Gemini; xAI; Bedrock; Cerebras; Cohere; Groq; Hugging Face; Mistral; OpenRouter; and other listed Pydantic AI providers |
| Safety evaluations | Yes |
| Deployment | Self-hosted |
| Prompt versioning | Yes |
| API access | Yes |
| Deployment | Self-hosted |
| Support | Docs |
| Built for | Solo, Small business, Mid-market, Enterprise (editorial estimate) |
| Integrations | 2 integrations: Pydantic Logfire, OpenTelemetry |
| Pricing | Free plan |
| Website | pydantic.dev |
| Facts checked | 22 Sep 2026 |
Pydantic Evals integrations
Pydantic Evals lists 2 integrations on its own site.
- Pydantic Logfire
- OpenTelemetry
Alternatives to Pydantic Evals
- DeepEvalA code-first toolkit for testing LLM apps, agents, tools, safety, and regressions.9.4
- Arize PhoenixA free, open-source toolkit covering traces, evaluations, prompts, datasets, and costs.9.3
- PromptfooA broad evaluation and security toolkit for teams testing AI systems in development.9.2

See all Pydantic Evals alternatives →
Used Pydantic Evals? Be the first to review it
The editor score above is our own research. What this page doesn't have yet is a reader's view — what you used Pydantic Evals for, what worked and what didn't. No stars are seeded and no review is paid for; an editor reads every one before it appears.
Write a reviewTwo minutes · verified accounts only · read by an editor before it appears
Featured on iTechGuides
Pydantic Evals is listed in our AI LLM Evaluation Tools directory. Add the badge to your site — it links back to this page.
<a href="https://www.itechguides.com/products/pydantic-evals/"><img src="https://www.itechguides.com/best/badge/pydantic-evals.svg" alt="Featured on iTechGuides" width="230" height="46"></a>
Reviewed by iTechGuides Editors · Editorial team · Updated Oct 2026
Advertiser disclosure: iTechGuides is reader-supported. Vendors can pay for top positions in our rankings and for a place on other products' pages, and we may earn a commission when you click some links. Bought places stand at the number bought; this page and our disclosure say so. Paying vendors may get a fuller, more detailed review from our editors, and that review can change their score. How we rank.
Last updated · How we research and update