MLflow GenAI Evaluation
MLflow GenAI Evaluation: A flexible, trace-based evaluation framework for teams building regression tests. Ranked #4 of 28 in AI Agent Evaluation Tools by our editors (8.9/10); pricing: Free plan; best for open-source teams building trace-based regression tests.
At a glance
- Editor score8.9 / 10
- PricingFree plan
- Best forOpen-source teams building trace-based regression tests
- Free planYes
- Paid fromFree
- Tool-call checksYes
- Facts checked21 Sep 2026
Where it wins
- Combines LLM judges with configurable and code-based scorers
- Evaluates traces, tool calls, safety issues, and human feedback
- Supports regression tests and CI/CD workflows
Where it doesn't
- Verified SDK coverage is Python
- The built-in Safety judge is limited to Databricks managed MLflow
- Support is centered on community resources and documentation
Our verdict on MLflow GenAI Evaluation
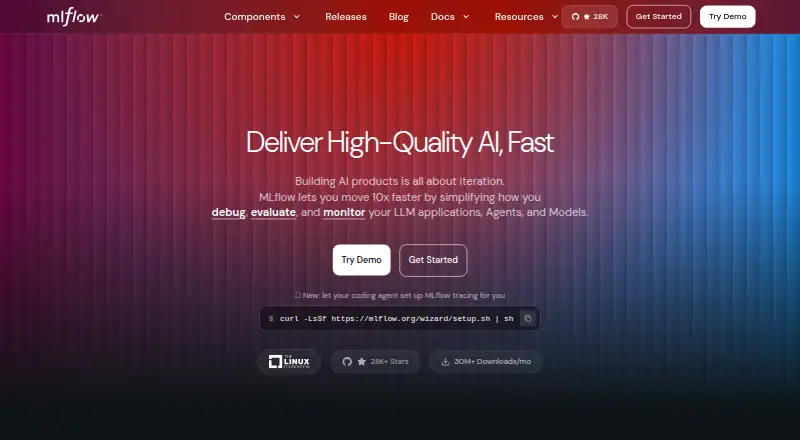
MLflow GenAI Evaluation is an open-source framework for testing LLM applications and AI agents. It fits teams that need repeatable evaluation across datasets, manually defined test cases, or recorded traces. The framework supports built-in LLM judges, custom LLM judges with configurable instructions, and code-based custom scorers. It is available through web, API, and self-hosted deployments, with cloud and self-hosted options. Solo developers and organizations of different sizes can use it, while open-source teams with trace-based regression workflows are the clearest fit.
Its evaluation coverage is broad for an agent-focused tool. Teams can check correctness, relevance, safety, groundedness, and tool-call behavior, including argument checks. Evaluation datasets can be created from traces or defined manually, and logged traces can be evaluated automatically. Human feedback and annotation support add a review path when automated judgments need additional context. Results are recorded in the MLflow Tracking Server and reviewed in its web UI. Integrations include LangChain, LangGraph, OpenAI, Anthropic, Google, Bedrock, LlamaIndex, AutoGen, CrewAI, and PydanticAI.
Regression testing is a central strength: evaluations can run in CI/CD workflows, helping teams compare changes against established cases or traces. MLflow can be self-hosted or used through managed services such as Databricks. The documented built-in Safety judge is currently limited to Databricks managed MLflow, while safety analysis is also available through MLflow issue detection. Verified SDK coverage is Python, so teams standardizing on another language may need a different evaluation layer. Choose MLflow GenAI Evaluation for open-source flexibility, hybrid scoring, and trace-based regression work; consider alternatives if broader verified SDK language coverage or a different support model is essential.
Your product? Our editors can test MLflow GenAI Evaluation in depth and publish a review, labelled as paid · from $149/mo →
MLflow GenAI Evaluation pricing
MLflow GenAI Evaluation fact sheet
| Free plan | Yes |
|---|---|
| Paid from | Free |
| Evaluation methods | Hybrid |
| Tool-call checks | Yes |
| Trace ingestion | Yes |
| Safety evaluations | Yes |
| Regression runs | Yes |
| SDK language support | Python |
| Dataset limit | Not verified |
| Deployment | Cloud, Self-hosted |
| Platforms | Web |
| Support | Community, Docs |
| Built for | Solo, Small business, Mid-market, Enterprise (editorial estimate) |
| Integrations | 100+ integrations: LangChain, LangGraph, OpenAI, Anthropic, Google, Bedrock … See all → |
| Pricing | Free plan |
| Website | mlflow.org |
| Facts checked | 21 Sep 2026 |
MLflow GenAI Evaluation integrations
MLflow GenAI Evaluation lists 100+ integrations on its own site — the 10 named here are the ones its pages call out.
- LangChain
- LangGraph
- OpenAI
- Anthropic
- Bedrock
- LlamaIndex
- AutoGen
- CrewAI
- PydanticAI
See all MLflow GenAI Evaluation integrations →
Alternatives to MLflow GenAI Evaluation
- DeepEvalA developer-focused evaluator for testing agents, tools, safety, and regressions.9.4
- AgentClashAgentClash tests agent behavior with replayable evidence, sandboxing, safety checks, and CI gates.9.3
- Future AGI AI Evaluation SDKBroad evaluation coverage with SDKs, tracing, simulations, and CI/CD quality gates.9.2
See all MLflow GenAI Evaluation alternatives →
MLflow GenAI Evaluation vs the competition
- MLflow GenAI Evaluation vs DeepEval
- MLflow GenAI Evaluation vs AgentClash
- MLflow GenAI Evaluation vs Future AGI AI Evaluation SDK
- MLflow GenAI Evaluation vs Galileo
- MLflow GenAI Evaluation vs Braintrust
- MLflow GenAI Evaluation vs Noveum
Compare MLflow GenAI Evaluation with any tool side by side →
Also Ranked In
MLflow GenAI Evaluation is ranked in 3 of our directories.
Used MLflow GenAI Evaluation? Be the first to review it
The editor score above is our own research. What this page doesn't have yet is a reader's view — what you used MLflow GenAI Evaluation for, what worked and what didn't. No stars are seeded and no review is paid for; an editor reads every one before it appears.
Write a reviewTwo minutes · verified accounts only · read by an editor before it appears
Featured on iTechGuides
MLflow GenAI Evaluation is listed in our AI Agent Evaluation Tools directory. Add the badge to your site — it links back to this page.
<a href="https://www.itechguides.com/products/mlflow-genai-evaluation/"><img src="https://www.itechguides.com/best/badge/mlflow-genai-evaluation.svg" alt="Featured on iTechGuides" width="230" height="46"></a>
Reviewed by iTechGuides Editors · Editorial team · Updated Oct 2026
Advertiser disclosure: iTechGuides is reader-supported. Vendors can pay for top positions in our rankings and for a place on other products' pages, and we may earn a commission when you click some links. Bought places stand at the number bought; this page and our disclosure say so. Paying vendors may get a fuller, more detailed review from our editors, and that review can change their score. How we rank.
Last updated · How we research and update