GLM-TTS
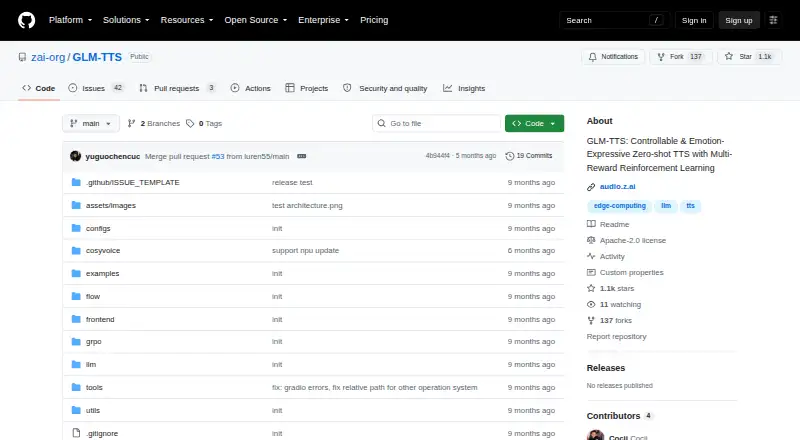
GLM-TTS: A research-focused TTS system for expressive cloning, streaming, and pronunciation control. Ranked #125 of 222 in Text-to-Speech Software by our editors (3.0/10); pricing: Open source; best for researchers experimenting with expressive voice cloning.
At a glance
- Editor score3.0 / 10
- PricingOpen source
- Best forResearchers experimenting with expressive voice cloning
- Paid fromFree
- Facts checked20 Sep 2026
Where it wins
- Clones voices from 3–10 seconds of prompt audio
- Controls emotion, prosody, and phoneme-level pronunciation
- Supports streaming inference, CLI use, and a Gradio web interface
Where it doesn't
- Language support is centered on Chinese-English mixed text
- Self-hosted deployment can require technical setup
- Output export is limited to WAV
Our verdict on GLM-TTS
GLM-TTS is an open-source text-to-speech synthesis system from Zhipu AI for researchers and developers exploring expressive speech generation. It combines a large language model for speech tokens with a flow-matching model and vocoder for audio production. Its core focus is zero-shot voice cloning from 3–10 seconds of prompt audio, with additional controls for emotion, prosody, pronunciation, and Chinese-English mixed text.
The standout feature set is aimed at experimentation rather than basic narration. GLM-TTS supports streaming inference for real-time audio generation, multiple inference and sampling modes, and emotion and prosody control through multi-reward reinforcement learning. Phoneme-level pronunciation control accepts hybrid phoneme and text input, which gives technical users more influence over how words are spoken. Command-line inference and an interactive Gradio web interface provide two ways to work with the system, while WAV is the listed export format.
Deployment is available through a web interface or self-hosting, with the project distributed as a research and development system. That makes GLM-TTS a fit for teams comfortable working with command-line inference, local interfaces, and model-based experimentation. It is less suitable for buyers seeking a broad multilingual production platform, a range of hosted plans, or a wider set of output formats. Choose it for expressive voice-cloning research, streaming generation, and fine pronunciation control; choose an alternative if broader language coverage or a more managed deployment model matters more.
Your product? Our editors can test GLM-TTS in depth and publish a review, labelled as paid · from $149/mo →
GLM-TTS pricing
GLM-TTS fact sheet
| Free plan | Not verified |
|---|---|
| Paid from | Free |
| Commercial use | Not verified |
| Voice cloning | Yes |
| API access | Not verified |
| Languages | Not verified |
| Maximum input | Not verified |
| Export formats | WAV |
| Platforms | web, self_hosted |
| Deployment | Self-hosted, Browser extension |
| Platforms | Web |
| Support | Community, Docs |
| Built for | Solo, Small business, Mid-market, Enterprise (editorial estimate) |
| Pricing | Open source |
| Website | github.com |
| Facts checked | 20 Sep 2026 |
Alternatives to GLM-TTS
- ElevenLabsAffordable voice cloning with multilingual generation, dubbing, streaming, and API access.9.4
- Google Cloud Text-to-SpeechA broad, API-only TTS service for developers building voice-enabled products.9.3
- Azure AI SpeechA broad, production-ready TTS platform for teams building voice applications.9.2


See all GLM-TTS alternatives →
Used GLM-TTS? Be the first to review it
The editor score above is our own research. What this page doesn't have yet is a reader's view — what you used GLM-TTS for, what worked and what didn't. No stars are seeded and no review is paid for; an editor reads every one before it appears.
Write a reviewTwo minutes · verified accounts only · read by an editor before it appears
Featured on iTechGuides
GLM-TTS is listed in our Text-to-Speech Software directory. Add the badge to your site — it links back to this page.
<a href="https://www.itechguides.com/products/glm-tts/"><img src="https://www.itechguides.com/best/badge/glm-tts.svg" alt="Featured on iTechGuides" width="230" height="46"></a>
Reviewed by iTechGuides Editors · Editorial team · Updated Oct 2026
Advertiser disclosure: iTechGuides is reader-supported. Vendors can pay for top positions in our rankings and for a place on other products' pages, and we may earn a commission when you click some links. Bought places stand at the number bought; this page and our disclosure say so. Paying vendors may get a fuller, more detailed review from our editors, and that review can change their score. How we rank.
Last updated · How we research and update