
Dynamic CSS classes create two different scraping problems: a class name may change between releases, or the element may not exist until JavaScript renders it. The reliable solution is to identify a stable contract—semantic HTML, an accessible role or label, an ID, or a deliberate data-* attribute—and then decide whether to parse the original HTML or a browser-rendered DOM. This guide shows both workflows, with Python examples, validation, and recovery tactics when a site changes.
What “dynamic CSS class” means
“Dynamic” is commonly used for two separate conditions. They require different fixes.


Generated or unstable class names
A build system may emit names such as card_x7k2p, or append a hash whenever CSS is rebuilt. The element is present in the downloaded HTML, but the token is an implementation detail and may change without changing the data you need.
Matching that token alone makes a scraper brittle. A redesign, a new deployment, or a different rendering path can silently return zero or the wrong number of elements.
Quick wins for a faster PC:
Clear out junk files and repair common Windows errorsFree Scan →Fix the driver behind crashes, sound loss and screen glitchesFind Drivers →#1 Best Overall
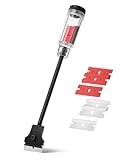
- Bates long reach extension scraper comes with a 11-inch handle for extended reach and includes 3 double-edged plastic blades and 3 metal blades for versatile use.
- The scraper is made from durable materials, ensuring reliable performance and long-lasting use for a variety of tasks.
- The 11-inch handle provides enhanced leverage and control, making it ideal for hard-to-reach areas or demanding scraping jobs.
- The interchangeable blades offer flexibility, with plastic blades designed for delicate surfaces and metal blades for tougher scraping tasks.
- This tool is perfect for removing paint, adhesives, stickers, and other residues, making it a must-have for home improvement and professional projects.
Client-side content
Some pages send only a shell in the initial response. JavaScript then fetches products, comments, prices, or table rows and inserts them into the DOM. No selector can find content that is not present yet. You need a browser that executes the page code, wait for a meaningful state, and then inspect the rendered DOM.
Choose the right extraction path
| Question | Original HTML plus Beautiful Soup | Browser-rendered DOM with Playwright |
|---|---|---|
| Is the target in the initial response? | Yes | Not required, but also works |
| Does JavaScript create the target? | No | Yes |
| Runtime cost and complexity | Low | Higher: browser startup, waiting and possible anti-bot challenges |
| Best use | Static pages, server-rendered HTML and feeds | Interactive or JavaScript-rendered pages |
Inspect one representative URL first. Compare the response source with the DOM shown in browser developer tools. If the data is already in the response, use a direct HTTP request. If it appears only after scripts run, use browser automation or an endpoint the page calls, where access is permitted by the site.
Find a stable locator before writing code
- Define the field. Decide whether you need a product title, price, author, link, or another specific value.
- Inspect the element and its context. Look at parents, siblings, labels and repeated records, not only the highlighted class.
- Prefer meaning over appearance. Use a semantic element, an accessible role and name, an ID, or an explicit attribute such as
data-testid,data-product-idoritemprop. - Use classes as a secondary clue. A short class selector can be useful when it remains stable across representative pages, but do not rely on a generated token alone.
- Avoid structural chains. Selectors such as
main > div:nth-child(2) > div > spanencode the current nesting and position. A wrapper insertion can break them or select a different field. - Check cardinality. A list expected to contain 20 records should not silently produce zero, one, or 200. Treat unexpected counts as an error.
Playwright’s documentation recommends prioritizing user-facing attributes and explicit contracts such as page.getByRole(). That guidance is useful for scraping too: a locator that describes what a user sees is usually more durable than a styling token.
Parse stable or changing classes in static HTML with Beautiful Soup
When the required markup is in the HTTP response, Beautiful Soup can search by class with class_ or use CSS selectors through select(). The examples below tolerate an additional generated class by requiring a stable attribute and checking the result.
The Tool Desk
Outbyte Driver Updater FREEFix the driver behind crashes, sound loss and screen glitchesFind Drivers →Outbyte PC Repair FREEClear out junk files and repair common Windows errorsFree Scan →Install the parser
python -m pip install requests beautifulsoup4Prefer a data attribute
from urllib.parse import urljoin
import requests
from bs4 import BeautifulSoup

URL = "https://example.com/catalog"
response = requests.get(
    URL,
    headers={"User-Agent": "Mozilla/5.0 (compatible; catalog-reader/1.0)"},
    timeout=30,
)
response.raise_for_status()
soup = BeautifulSoup(response.text, "html.parser")

records = []
for card in soup.select('[data-product-id]'):
    title_node = card.select_one('[data-field="name"], h2, h3')
    link_node = card.select_one('a[href]')
    if title_node is None:
        continue
    title = title_node.get_text(" ", strip=True)
    href = urljoin(URL, link_node["href"]) if link_node else None
    records.append({
        "id": card.get("data-product-id"),
        "title": title,
        "url": href,
    })

if not records:
    raise RuntimeError("No product records found; inspect the response HTML and locator.")
print(records)
The selector does not care whether the same card also has card_x7k2p or card_q91mz. The explicit product attribute is the contract.
When only a class is available
Use the least fragile selector you can and verify it on several pages or captures. Beautiful Soup’s class_ argument matches a class token, while a CSS selector can express multiple classes.
from bs4 import BeautifulSoup

html = """<article class='product a8f3'>
  <h2 class='name k19z'>Keyboard</h2>
</article>"""
soup = BeautifulSoup(html, "html.parser")

# Matches the stable-looking token if it is genuinely observed to persist.
for article in soup.find_all("article", class_="product"):
    name = article.select_one("h2.name")
    if name:
        print(name.get_text(" ", strip=True))
If the site changes product itself, there is no magic parser option that restores certainty. Reinspect the markup and replace the locator with a semantic or explicit identifier.
Use Playwright when JavaScript creates the content
Playwright supports CSS, XPath and locator APIs. Prefer role, label, text or test-id locators when they express the target clearly; use CSS when the page exposes a useful attribute that is not covered by those APIs.
Install and launch Chromium
python -m pip install playwright
playwright install chromium
Wait for a meaningful state, then extract
from playwright.sync_api import sync_playwright

URL = "https://example.com/catalog"

with sync_playwright() as p:
    browser = p.chromium.launch(headless=True)
    page = browser.new_page()
    page.goto(URL, wait_until="domcontentloaded", timeout=60_000)

    # Replace this with a stable element that proves the records are ready.
    page.locator('[data-product-id]').first.wait_for(state="visible", timeout=30_000)

    cards = page.locator('[data-product-id]')
    count = cards.count()
    if count == 0:
        raise RuntimeError("The rendered page contains no product cards.")

    output = []
    for i in range(count):
        card = cards.nth(i)
        title = card.locator('[data-field="name"], h2, h3').first.inner_text()
        link = card.locator('a[href]').first.get_attribute('href')
        output.append({"id": card.get_attribute("data-product-id"),
                       "title": title.strip(), "url": link})
    browser.close()

print(output)
Waiting for networkidle can be appropriate for a page that finishes a finite set of requests, but it is not a universal guarantee: analytics, streams and long polling may keep the network busy. A specific selector or application state is usually more deterministic. If content appears after scrolling, perform the required scroll or click before waiting for the final locator.
Inspect the rendered DOM for debugging
with sync_playwright() as p:
    browser = p.chromium.launch(headless=True)
    page = browser.new_page()
    page.goto("https://example.com/catalog", wait_until="domcontentloaded")
    page.wait_for_timeout(2_000)
    print(page.locator("body").inner_html()[:5_000])
    page.screenshot(path="debug.png", full_page=True)
    browser.close()
This distinguishes a bad selector from a page that never produced the expected element. Do not assume that a screenshot proves the exact data is available to your parser; inspect the DOM or the application’s accessible tree as well.
Rank #3

- Save Your Nails with Scrigit Scraper - The ultimate multi-use plastic scraper tool works for many tasks at home or on the go; an ideal dried-on food scraper, label scraper, sticker removal tool, and even a handy chrome delete tool for automotive detailing.
- No-Scratch Super Scraper: One side of your Scrigit Scraper tool has a flat edge that's best for flat surfaces and larger areas. The other side has a round edge, best for curved surfaces and smaller areas. Dishwasher safe and easy to hold, just like a pen.
- Made in the USA – Let this crevice cleaning tool do the work for you in hard-to-reach areas. Made from durable plastic, it's safe for most surfaces, works great as a label remover tool, and even doubles as a lottery scratch-off tool. Proudly MADE IN THE USA!
- Keep Handy Everywhere You Need It: Keep your slim scraper pen Scrigit tool at home, in your vehicle or office. It's the ultimate crevice tool to keep in your cleaning box to remove grime from those hard-to-reach areas of your kitchen and bathroom.
- Convenient Size: Our slim detailing tools are 6 inches long x 3/8 inches in diameter with a convenient pocket clip. Why not buy some for your friends, because everyone can find a use for a Scrigit Scraper.
Handle changing class tokens deliberately
Match a stable token among multiple classes
HTML class attributes are sets of tokens. If one token conveys a durable role and another is generated, target the durable token: .price is preferable to .css-1a2b3c when the former is consistently present.
Use attribute-prefix or substring matching cautiously
A selector such as [class^="card-"] can cover generated suffixes, and [class*="price"] can find a meaningful fragment. These are fallbacks, not contracts: substring matches can collide with unrelated components. Narrow the match with a stable parent or a second attribute and validate the count.
Recommended Free Tools
Normalize the value after locating the node
Classes are only a locator. Parse text separately: trim whitespace, decode entities through the parser, normalize non-breaking spaces and convert numbers with locale-aware rules. Keeping location and value conversion separate makes class changes easier to repair.
Validate and monitor extraction
Run the scraper against more than one representative page, pagination state and account or locale where applicable. Add checks that fail visibly instead of publishing empty data.
- Require the expected container or a minimum record count.
- Detect duplicate IDs and duplicate URLs.
- Require non-empty values for fields that are mandatory in your output.
- Record the URL, timestamp and selector version when a check fails.
- Save a small HTML or rendered-DOM sample for diagnosis, subject to the site’s rules.
A valid zero-result page is possible, so make the check domain-specific: for example, distinguish an empty search result from a missing results container.
Rank #4

- Practical cleaning tools: you will get 9 piece of plastic scraper tools, enough quantity to satisfy your daily use, or you can share them with family and friends, so that you will be able to remove small amounts of various common substances easily
- 3 Kinds of two-way scraper tools: the 3 kinds of two-way scratch free plastic scrapers are proper for various occasions; The wide scraper head can be applied to scrape wide areas, such as smudges on the ground, chewing gum, stickers, labels, etc.; The narrow scraper head can clean narrow spaces, as well as difficult to reach places of the car outside body and interior place; And the pointed scraper is very suitable for cleaning more narrow crevices, such as tight corners, edges, grooves
- Durable material: the stiff multipurpose label scraper is made of quality carbon fiber plastic, sturdy and durable, not easy to break under pressure, with high hardness, reusable, lightweight and easy to carry; You can let the scrape cleaning tool do the job and protect your nails
- Portable and easy to use: our cleaning pen-shaped scraper tool is 5.8 inch/ 14.6 cm long, small and convenient size for easily carrying out with you; Anytime you need it, just put it in your handbag, tool box, or anywhere proper for you
- Wide applications: this plastic scraper tool is ideal for cleaning crevices, while protecting your nails; They are also suitable for removing label stickers, grease, paint, candle wax, dirt, soap, dried foods, ticket and more on kitchen, car, bathroom, office, motorcycle, boat, workshop, garage; It can also be applied as a pry open electronic repair tool for LCD, tablet
Troubleshooting dynamic-class scrapers
“No elements found” in Beautiful Soup
Likely causes: the data is JavaScript-rendered, the request received a different response, or the class changed. Fix: save and inspect response.text, confirm the status and redirects, then switch to Playwright if the records are absent from the response. Check the selector against the exact HTML you downloaded.
Playwright times out waiting for a locator
Likely causes: the selector is wrong, a consent dialog blocks the page, the request failed, or the element appears only after an interaction. Fix: capture a screenshot and rendered HTML, inspect console and network errors, handle the dialog, perform the required click or scroll, and wait for a meaningful state rather than adding an arbitrary long delay.
The selector matches too many elements
Cause: a generic class or substring is shared by several components. Fix: scope it to a record container and add a stable attribute, role, label or field marker. Assert the expected cardinality.
Text is present visually but empty in extraction
Cause: the visible value may be in an attribute, shadow DOM, pseudo-element, canvas, or an iframe. Fix: inspect the element properties, read the relevant attribute, target the frame, or use the application’s underlying data request when permitted. CSS pseudo-element text is not ordinary DOM text.
Requests are blocked or challenged
Cause: the site may require JavaScript, cookies, authentication or may reject automated traffic. Fix: respect terms, robots directives and rate limits; use an authorized API or authenticated browser context. Do not attempt to bypass a CAPTCHA or access control.
Performance, reliability and maintenance
Use direct HTTP parsing whenever the required data is in the response; it avoids browser startup and reduces resource use. Reuse a Playwright browser for multiple pages, limit concurrency to what the site allows, block unnecessary resources only when doing so does not remove required data, and set explicit navigation and locator timeouts. Cache responses where appropriate and identify your client honestly.
For long-lived scrapers, keep locators in one module, test them against saved fixtures, and alert on missing fields or sudden count changes. A short, meaningful selector is easier to review than a generated token or a positional XPath. When the site provides a documented API or export, prefer that interface over scraping presentation markup.
Or skip the browser setup
ScreenshotNeo provides a website screenshot API and MCP server. It accepts consent banners before capture and removes more than 60 known consent platforms, newsletter popups and chat widgets; each step can be turned off. Bot checks or CAPTCHAs, blank pages, timeouts, failed loads and cache hits are not billed, and the response reports the page verdict and billing status in X-Page-Verdict and X-Billed headers. Its MCP tools—take_screenshot, get_page_info and capture_pdf—work with Claude, Cursor and other MCP clients.
For a rendered visual capture of a target URL, use one call:
curl -G "https://api.screenshotneo.com/v1/shot" -d access_key=YOUR_API_KEY --data-urlencode url=https://stripe.com -o shot.webpPython:
import requests
r = requests.get("https://api.screenshotneo.com/v1/shot", params={"access_key": "YOUR_API_KEY", "url": "https://stripe.com"}, timeout=90)
open("shot.webp", "wb").write(r.content)
Node.js:
const q = new URLSearchParams({ access_key: 'YOUR_API_KEY', url: 'https://stripe.com' });
const res = await fetch(`https://api.screenshotneo.com/v1/shot?${q}`);
See the ScreenshotNeo documentation for options such as full-page capture, waiting for selectors or network idle, custom JavaScript and CSS, cookies and headers, device presets, PDF output, caching, bulk capture and signed webhooks. The Free plan includes 1,000 screenshots per month with no card; paid plans start at $5 for 3,000 shots. Sign up free to start.
Legal and operational boundaries
Whether you may scrape a site depends on its terms, permissions, robots directives, authentication controls and applicable law. Those conditions vary by target and jurisdiction. Keep request rates reasonable, protect credentials and personal data, and stop when an owner asks you to stop. This technical method is not legal advice.
Frequently Asked Questions
Can a regular expression reliably match a generated CSS class?
It can cover a known naming pattern, but it remains tied to an implementation detail. Prefer a semantic or explicit data attribute and use a regex only as a validated fallback.
Should I use XPath instead of CSS for changing classes?
Neither syntax makes an unstable contract stable. Choose the locator that expresses the clearest meaning, and avoid long positional paths in either form.
Do these 3 things before closing this tab:
1Repair Windows errors before they cause bigger problems2Scan for outdated or missing drivers - takes under a minute3Clear out junk files and repair common Windows errorsWhy does a page source search differ from inspector markup?
Page source is the original response; inspector markup is the live DOM after scripts, user actions and browser parsing. JavaScript-rendered data may exist only in the latter.
Quick Recap
Product prices and availability are accurate as of the date/time indicated and are subject to change. Any price and availability information displayed on Amazon at the time of purchase will apply.

