
iTechGuides is reader-supported. When you buy through links on our site, we may earn an affiliate commission. As an Amazon Associate I earn from qualifying purchases. Learn more
To optimize Isaac ROS perception, measure the complete graph, locate the repeatable bottleneck, change one relevant factor, then run the same benchmark again. A fast inference node does not guarantee a fast camera-to-result pipeline: resizing, tensor encoding, ROS scheduling, memory movement, synchronization and decoding can all contribute to end-to-end latency. Keep perception quality and real-time requirements in the test, not just frames per second.
Set a target and record the baseline conditions
Before changing the graph, define what “fast enough” means for the robot. Specify the maximum acceptable end-to-end latency, minimum sustained throughput, utilization limits and any detection- or image-quality requirements. A higher peak frame rate is not a useful improvement if it misses the latency deadline or degrades the perception task.
Record the configuration alongside every result. At minimum, note:
Free tools Windows power users keep installed
One-click scans. No signup required.
- GPU or Jetson model and power configuration.
- Isaac ROS release, ROS 2 distribution, JetPack, CUDA, NVIDIA driver and TensorRT versions, as applicable.
- Sensor input rate and image dimensions.
- Model, inference backend and graph composition, including preprocessing and postprocessing nodes.
- Benchmark input, configuration and measurement conditions.
Use an environment supported by the Isaac ROS release actually installed. NVIDIA’s current getting-started and benchmark documentation identifies different platform/software combinations; the listed combinations are a release-specific support snapshot, not timeless requirements.
#1 Best Overall
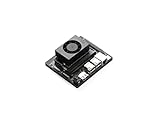
- The NVIDIA Jetson Orin Nano Developer Kit sets a new standard for creating entry-level AI-powered robots, smart drones, and intelligent cameras,and simplifies getting started with the Jetson Orin Nano series. Compact design, lots of connectors and up to 40 TOPS of AI performance make this developer kit perfect for transforming your visionary concepts into reality. With up to 80X the performance of Jetson Nano, it can run all modern AI models, including transformer and advanced robotics models.
- The developer kit comprises a Jetson Orin Nano 8GB module and a reference carrier board that can accommodate all Orin Nano and Orin NX modules, providing an ideal platform for prototyping your next-gen edge AI product. The Jetson Orin Nano 8GB module features an Ampere GPU and a 6-core ARM CPU, enabling multiple concurrent AI application pipelines and high-performance inference. The carrier board boasts a wide array of connectors, including two MIPI CSI connectors supporting camera modules with up to 4-lanes, allowing higher resolution and frame rate than before.
- Jetson runs the NVIDIA AI software stack, with available use-case-specific application frameworks, including NVIDIA Isaac for robotics, DeepStream for vision AI, and Riva for conversational AI. You can save significant time with NVIDIA Omniverse Replicator for synthetic data generation (SDG), and with NVIDIA TAO Toolkit for fine-tuning pretrained AI models from the NGC catalog.
- Ecosystem partners offer additional AI and system software, developer tools, and custom software development. They can also help with cameras and other sensors, as well as carrier boards and design services for your product.
- Jetson Orin modules are unmatched in performance and efficiency for robots and other autonomous machines, and give you the flexibility to create the next generation of AI solutions with the latest NVIDIA technology. Together with the world-standard NVIDIA AI software stack and an ecosystem of services and products, your road to market has never been faster.
| Platform in NVIDIA’s current documentation | Software combination listed |
|---|---|
| Jetson Thor and Jetson Orin | JetPack 7.2; Isaac ROS packages are designed and tested for ROS 2 Lyrical. |
| x86_64 NVIDIA GPU system | Ubuntu 24.04, CUDA 13.2 or later, and NVIDIA Driver 595 or later; Isaac ROS packages are designed and tested for ROS 2 Lyrical. |
| DGX Spark | DGX OS 7.2.3; Isaac ROS packages are designed and tested for ROS 2 Lyrical. |
For Jetson runs, follow NVIDIA’s power-setting guidance for the installed platform and keep power mode consistent between baseline and comparison. Otherwise, a changed power configuration can confound whether a software change caused the result.
Measure the graph, not only the inference node
Use both node-level measurements and a graph-level benchmark. Node measurements help isolate components; the full graph shows the performance the application actually experiences. NVIDIA’s Isaac ROS Benchmark is intended to report throughput, latency and utilization, with benchmark methods, configurations and input data provided so results can be independently verified.
Rank #2

- The NVIDIA Jetson AGX Orin 64GB Developer Kit makes it easy to get started with Jetson Orin. Compact size, lots of connectors, and up to 275 TOPS of AI performance make this developer kit perfect for prototyping advanced AI-powered robots and other autonomous machines.
- The developer kit includes a Jetson AGX Orin 64GB module, and can emulate all the Jetson Orin modules. It supports multiple concurrent AI application pipelines with the NVIDIA Ampere GPU architecture, next-generation deep learning and vision accelerators, high-speed IO and fast memory bandwidth. Now you can develop solutions using your largest and most complex AI models to solve problems such as natural language understanding, 3D perception, and multi-sensor fusion.
- Jetson runs the NVIDIA AI software stack, and use-case specific application frameworks are available, including Isaac for robotics, DeepStream for vision AI, and Riva for conversational AI. You can save significant time with NVIDIA Omniverse Replicator for synthetic data generation (SDG), and by using NVIDIA TAO toolkit to fine-tune pretrained AI models from the NGC catalog.
- Jetson ecosystem partners offer additional AI and system software, developer tools, and custom software development. They can also help with cameras and other sensors, as well as carrier boards and design services for your product.
- With the computing capability of more than 8 Jetson AGX Xavier systems in a developer kit that integrates the latest NVIDIA GPU technology with the world’s most advanced deep learning software stack, you’ll have the flexibility to create tomorrow’s AI solution as well as today’s.
Run a representative, fixed input and configuration for the baseline. Keep the same input, resolution, graph, platform and power mode when testing a change. Report the same metrics each time, and distinguish sustained throughput from a brief peak. NVIDIA’s published performance examples are tied to specific sample graphs, input sizes, hardware and documentation release, so they are reference points—not promises for another robot.
| Documented Isaac ROS DNN Inference 4.6 example | Hardware and input | Published result |
|---|---|---|
| TensorRT Node with DOPE | AGX Orin, VGA | 31.1 fps and 3.1 ms, as displayed in NVIDIA’s table. |
| TensorRT Node with PeopleSemSegNet | AGX Orin, 544p | 356 fps and 1.9 ms, as displayed in NVIDIA’s table. |
These figures describe the named documented examples. They do not establish a general speedup for Isaac ROS GPU perception, and should not be compared as if they were measured on the same model or workload.
Rank #3

- 【Core Parameters】★AI Perf: 117/157 TOPS★GPU: 1024-core N-VI-DIA Ampere architecture GPU with 32 Tensor Cores★CPU: 8-core Arm Cortex-A78AE v8.2 64-bit CPU 2MB L2 + 4MB L3★Memory: 16GB 128-bit LPDDR5 | 102.4GB/s★Storage: Supports external NVMe 【Note: This kit does not include a SSD and pre-installed system. User need to provide your own NVMe M.2 SSD of at least 256GB and flash the operating system onto it yourself. 】
- 【Empowered by Large Al Model, Enhanced Human-Computer Interaction】Jetson Orin Super leverages three AI models and incorporates an AI voice interaction module. This multimodal visual system matches the scene being described, enabling environmental awareness and AI visual gameplay. Combined with a large-scale voice module and camera, it enables speech-to-text, semantic analysis, natural conversation, and real-time video analysis, enabling advanced embodied AI applications.
- 【Revolutionize the Industry】Jetson Orin NX modules deliver unmatched performance and efficiency for small, low-power robotics and autonomous machines, making them ideal for drones, handheld devices, and more. The module can be easily used in advanced applications in manufacturing, logistics, retail, agriculture, medical and life sciences, and comes in a highly compact and energy-efficient package.
- 【Revolutionizing AI with Unmatched Performance】The Jetson Orin NX system module adopts the Ampere architecture GPU, a new generation of deep learning and vision accelerators, high-speed I/O, and fast memory bandwidth to support multiple AI application processes. Granular structured sparsity to improve the operating throughput of Tensor Core, and can use larger and more complex AI model development solutions in natural language understanding, 3D perception and multi-sensor fusion.
- 【Tutorial materials provided】The JETSON system based on Ubuntu 22.04 provides a complete desktop Linux environment with accelerated graphics, supporting NVIDI-ACUDA 12.6, TensorRT 10.7.0, cuDNN 9.6.0, OpenCV 4.10.0, etc. The performance on AI LLM, VLM and visual Transformer is significantly improved compared with the previous generation.
Find where the pipeline spends time
Once a baseline shows a repeatable problem, profile the graph before selecting an optimization. The image path can include resizing, encoding images into tensors, model inference and decoding results. ROS scheduling, transport, memory copies and synchronization can also matter. The presence of a neural network does not prove that inference is the dominant cost.
NVIDIA’s Isaac ROS Benchmarking 5.0 profiling guide describes Nsight Systems tracing for CPU, GPU and other system-on-chip accelerator activity. A GPU-aware trace can reveal work and synchronization that CPU-only tracing does not show. Use the trace to determine whether the delay is concentrated in preprocessing, inference, postprocessing, scheduling, memory movement or synchronization, then target that component.
Rank #4

- The Nvidia Jetson Xavier Nx Developer Kit Includes A Power-Efficient, Compact Jetson Xavier Nx Module For Ai Edge Devices. It Benefits From New Cloud-Native Support And Accelerates The Nvidia Software Stack In As Little As 10 W With More Than 10X The Performance Of Its Widely Adopted Predecessor, Jetson Tx2. The Capability To Develop And Test Power-Efficient, Small Form-Factor Solutions With Accurate, Multi-Modal Ai Inference Opens The Door For New Breakthrough Products.
- Developers Can Now Take Advantage Of Cloud-Native Support To Transform The Experience Of Developing And Deploying Ai Software To Edge Devices. Pre-Trained Ai Models From Nvidia Ngc, Together With The Nvidia Transfer Learning Toolkit, Provide A Faster Path To Inference With Optimized Ai Networks, While Containerized Deployment To Jetson Devices Allows Flexible And Seamless Updates.
- The Developer Kit Is Supported By The Entire Nvidia Software Stack, Including Accelerated Sdks And The Latest Nvidia Tools For Application Development And Optimization. When Combined With Jetson Xavier Nx, This Powerful Stack Helps You Create Innovative Solutions For Manufacturing, Logistics, Retail, Service, Agriculture, Smart City, Healthcare And Life Sciences, And More.
- Ease Of Development And Speed Of Deployment—Together With A Unique Combination Of Form-Factor, Performance, And Power Advantage—Make Jetson Xavier Nx The Most Flexible And Scalable Platform To Get To Market Fast And Continuously Update Over The Lifetime Of A Product.
Choose one optimization that matches the bottleneck
Test input resolution against task quality
Reducing image dimensions can reduce the pixel work in the inference path. NVIDIA’s DNN Inference documentation notes that inference tends to scale with image pixel count and that input resolution may be reduced to improve performance. The trade-off is application-specific: a smaller image may reduce detection or segmentation quality. Evaluate the task at the candidate resolution rather than treating a faster inference result as sufficient.
The Tool Desk
Outbyte Driver Updater FREEScan for outdated or missing drivers - takes under a minuteDriver Scan →Outbyte PC Repair FREEClear out junk files and repair common Windows errorsFree Scan →Select an inference backend based on model support
TensorRT optimizes supported models for the target hardware. Triton provides a frontend for multiple inference backends and may suit models that are not directly supported by TensorRT. NVIDIA’s documentation cautions that bespoke or newer models may not be supported by TensorRT. Check model and operator compatibility for the installed release, then compare end-to-end performance on the actual graph; backend choice alone does not establish which path will be faster.
Best Value
- GPU:2560-core NVIDIA Blackwell architecture GPU with 96 fifth-gen Tensor Cores
- AI Performance:2070 TFLOPS
| Consideration | TensorRT | Triton |
|---|---|---|
| Role described by NVIDIA | Optimizes supported models for target hardware. | Provides a frontend for multiple inference backends. |
| When to evaluate it | When the model is supported and hardware-targeted optimization is appropriate. | When backend choice or model compatibility makes a Triton path appropriate. |
| What to verify | Model/operator support and measured graph-level latency, throughput and utilization. | Available backend support for the model and measured graph-level latency, throughput and utilization. |
Reduce avoidable conversion and transport work
Inspect image encoding, decoding and format conversions around inference. If the trace shows avoidable copies, conversions or synchronization, test a graph change that removes the identified work, then measure again. NITROS is documented for message type adaptation and negotiation and accelerated transport, but transport instructions are release-sensitive.
A repository update dated 2026-09-21 records migration of TensorRT and Triton nodes from NITROS to ROS 2 rosidl::Buffer with a CUDA buffer backend. Do not apply older NITROS-specific instructions automatically: check the documentation and implementation for the exact Isaac ROS release in use.
Run controlled experiments and report the result honestly
- Capture the baseline. Run the fixed representative input and benchmark configuration; record graph-level latency, sustained throughput and utilization, plus node-level measurements useful for diagnosis.
- Use a trace to identify a bottleneck. Profile CPU and GPU activity and inspect the relevant preprocessing, inference, postprocessing, transport and synchronization work.
- Change one factor. For example, test a lower image resolution, a supported inference backend, fewer unnecessary conversions or a transport change that matches the installed release.
- Repeat the same measurement. Keep hardware, power configuration, software versions, input and graph conditions fixed. Compare the same metrics with the baseline.
- Check application constraints. Confirm the change still meets the latency and sustained-throughput target and preserves acceptable perception quality.
When publishing or sharing a result, state whether it covers one node or the full graph, along with hardware, power mode, Isaac ROS and ROS versions, relevant JetPack/CUDA/driver/TensorRT versions, input dimensions and rate, model, and measurement configuration. Without those details, a performance number is difficult to reproduce or apply to a different robot.
Recommended Free Tools
Quick Recap
Product prices and availability are accurate as of the date/time indicated and are subject to change. Any price and availability information displayed on Amazon at the time of purchase will apply.

