
iTechGuides is reader-supported. When you buy through links on our site, we may earn an affiliate commission. As an Amazon Associate I earn from qualifying purchases. Learn more
To track AI inference costs in production, combine provider billing reports with request-level usage and workflow traces. Billing shows what was charged; traces help explain which feature, model call, retry, or orchestration step drove the spend. Connect both views with stable workflow and request identifiers, then investigate cost alongside task quality, latency, and reliability.
What to measure for each AI workflow
Token counts and billed dollars are related, but they are not interchangeable. A trace can show the tokens returned for a request, while the provider’s billing view is the better record for reconciling charges. A token-based cost estimate is not an invoice: exact cost can depend on the model, cached-input treatment, service tier, geography, and negotiated pricing.


For each model operation, record a timestamp, provider and model identifier, workflow or feature, request or run ID, outcome, latency, and provider-returned usage fields when available. For agent systems, preserve parent-child relationships between calls so you can connect a user request to delegated work, retries, and other model calls. This is a practical instrumentation schema, not a vendor-mandated format.
Choose a unit that reflects the work your application delivers. Cost per successful task or workflow run is often more actionable than total monthly spend alone. Track supporting measures such as calls per run, input and output tokens, cached input where exposed, retries, errors, and latency.
#1 Best Overall
How to establish a trustworthy baseline
- Choose a reporting window. Compare provider usage and billing for the same dates. Normalize time zones before matching provider reports to application logs.
- Separate environments and workloads. Keep production distinct from staging, evaluation, and experiments when project or tag dimensions allow. Do not assume separate organizations are combined in one dashboard.
- Capture trace context. Attach stable workflow, feature, tenant, or team identifiers to calls where possible. Keep request IDs and parent-child links so an alert or expensive run can lead back to the responsible step.
- Record outcomes as well as usage. Mark whether a workflow succeeded, failed, or required retries. Without outcome data, a low-cost run may look efficient even if it did not complete the task.
For OpenAI, the Usage Dashboard is available to organization owners or users with the Usage Dashboard permission, displays data in UTC, and does not combine activity across separate organizations. Its usage guide explains the dashboard and other usage views: OpenAI API usage and costs.
Choose the right level of cost attribution
Provider billing and usage views are useful for answering what was used or billed over a reporting period. Traces and invocation logs are better for diagnosing which request or workflow step produced that usage. A cross-provider observability layer can help compare workflows, but only if its instrumentation, pricing data, model coverage, and retention meet your needs.
Rank #2

- 【Space-Saving Compact Design】Designed with a compact 10-inch width, this network rack saves valuable space while providing enough room to organize and mount essential equipment. Measuring 10.4 x 9.4 x 16.6 inches, it is ideal for space-efficient installations while maintaining reliable functionality
- 【Heavy-Duty Load Capacity】The 8U Network rack open frame is made of durable cold-rolled steel, providing strong support and reliable durability. The reinforced Rack shelf supports enhance overall stability and help securely hold mounted equipment
- 【Wide Equipment Compatibility】Designed to support 10-inch rack-mountable equipment, this rack is compatible with patch panels, network switches, cable organizers, and power strips, offering flexible installation solutions for various networking and electronics applications
- 【Enhanced Airflow & Clear Visibility】The open-frame structure promotes excellent airflow for improved cooling performance, while the transparent panels provide clear visibility of device indicators and help protect equipment from dust. This design ensures efficient heat management while allowing easy monitoring of your setup
- 【Complete Accessory Kit Included】The package includes 1 blank panel, 1 Brush Panel, 1 rack shelf, and all necessary mounting hardware, providing everything you need for a convenient, customizable, and efficient installation
| Approach | Best for | Important limitation |
|---|---|---|
| Provider billing and usage dashboards | Reconciling billed spend or provider-reported usage over a reporting period | Aggregation and attribution dimensions vary; permissions, account boundaries, and billing timing can matter. |
| Request traces and invocation logs | Finding the calls, steps, and behavior behind an individual workflow’s usage | Usage fields may be incomplete or best-effort; logs can be high-volume and may contain sensitive data. |
| Cross-provider observability layer | Comparing workflows across providers or frameworks | Validate integrations, pricing-data maintenance, per-step attribution, retention, privacy controls, alerts, and invoice reconciliation. |
OpenAI
Use the Usage Dashboard to examine reporting-period and project activity, and inspect request-level usage in API responses when available. For agent workflows, OpenAI documents input, cached-input, and output usage; reasoning tokens count as output tokens. One task can involve multiple model calls, and the returned usage may be absent or change as accounting arrives. Treat it as useful operational detail, not a substitute for billing reconciliation. See OpenAI Agents observability.
The Tool Desk
Outbyte Driver Updater FREEScan for outdated or missing drivers - takes under a minuteDriver Scan →Outbyte PC Repair FREEClear out junk files and repair common Windows errorsFree Scan →Amazon Bedrock
Bedrock’s native cost-attribution mechanisms answer different questions. AWS describes billed dollars aggregated by usage type per day and associated with identities or resource tags; these mechanisms do not produce a billing row for every request. Per-request metadata tagging can put tags and token counts in invocation logs, after which your team can calculate an estimated cost.
The suitable attribution method depends on the endpoint and the identity or resource dimensions you need. AWS’s options include IAM principal attribution, application inference profiles, Projects, Workspaces, and per-request metadata, with differing API support. In a gateway setup, the gateway’s IAM role is recorded as caller identity; per-request metadata can preserve prompt-level context without an STS call per request. See Amazon Bedrock cost tracking.
Anthropic
Anthropic’s organization Usage and Cost API documents USD costs, token, web-search, and code-execution cost types, grouping by workspace or description, and daily buckets. Its documentation says models released before February 2026 do not support inference_geo and report not_available for that dimension, so geographic analysis depends on the model cohort. See the Anthropic Usage and Cost API.
Rank #4
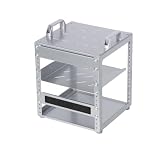
- 【Space-Saving Compact Design】Designed with a compact 10-inch width, this network rack saves valuable space while providing enough room to organize and mount essential equipment. Measuring 10.45 x 9.45 x 13.15 inches, it is ideal for space-efficient installations while maintaining reliable functionality
- 【Heavy-Duty Load Capacity】The 6U Network rack open frame is made of durable cold-rolled steel, providing strong support and reliable durability. The reinforced Rack shelf supports enhance overall stability and help securely hold mounted equipment
- 【Wide Equipment Compatibility】Designed to support 10-inch rack-mountable equipment, this rack is compatible with patch panels, network switches, cable organizers, and power strips, offering flexible installation solutions for various networking and electronics applications
- 【Enhanced Airflow & Clear Visibility】The open-frame structure promotes excellent airflow for improved cooling performance, while the transparent panels provide clear visibility of device indicators and help protect equipment from dust. This design ensures efficient heat management while allowing easy monitoring of your setup
- 【Complete Accessory Kit Included】The package includes 1 blank panel, 1 Brush Panel, 1 rack shelf, and all necessary mounting hardware, providing everything you need for a convenient, customizable, and efficient installation
How to find which workflow is driving the bill
Start with the highest-spend workflows, then compare successful runs of the same task. Averages can hide a small number of expensive outliers, so inspect distributions as well as totals.
Recommended Free Tools
- Unexpected call counts: look for repeated attempts, agent loops, extra delegated work, or orchestration that invokes a model more times than successful runs usually require.
- Growing input context: check for duplicated instructions or tool definitions, excessive conversation history, and retrieval that adds irrelevant or unbounded documents.
- Long outputs: review output-token distributions and maximum output settings. In OpenAI’s Agents usage explanation, reasoning tokens are counted as output tokens.
- Model mismatch: identify routine, low-complexity steps routed to a more capable or costly model than the task appears to require.
- Excessive orchestration: examine fine-grained state transitions, synchronous work that waits while compute remains occupied, and retries caused by failures.
- Non-token charges: where applicable, account for tool use, sandbox compute, cache writes, or third-party charges as well as model tokens.
AWS Prescriptive Guidance identifies token count as the biggest cost driver in Amazon Bedrock, but that is an AWS-specific statement, not a universal rule for every provider or AI infrastructure. For serverless agentic workloads, the guide recommends limiting prompt size and verbose completions, narrowing retrieval with metadata filters and Top K ranking, batching suitable events, avoiding excessive atomic state transitions, and routing low-complexity prompts to a lower-tier model with escalation when confidence is low. Treat these as experiments to evaluate on your own workload, not guaranteed savings. See AWS Prescriptive Guidance for agentic AI on serverless.
Best Value

- [ Maximum AI Compute Power ] Dominate complex workloads with the ASUS ESC8000A-E13. This 4U rack server is a powerhouse engineered for mass-scale AI, machine learning, and deep training. Featuring support for dual AMD EPYC 9005/9004 processors and up to eight dual-slot GPUs, it delivers the raw computational muscle required to train LLMs and run complex simulations effortlessly. Accelerate your data science pipeline and transform raw data into actionable intelligence faster than ever.
- [ Advanced Thermal Efficiency ] High performance demands elite cooling. The ESC8000A-E13 features a cutting-edge aerodynamic design with independent CPU and GPU airflow tunnels. Equipped with redundant hot-swap fans and optimized for liquid cooling integrations, this 4U server ensures maximum uptime under heavy, sustained workloads. Keep your data center running cool, quiet, and highly efficient while preventing thermal throttling during mission-critical enterprise operations.
- [ Scale with Flexible Storage ] Future-proof your infrastructure with unmatched storage and expansion flexibility. This offers comprehensive front-panel drive bays supporting Gen5 NVMe, SAS, or SATA drives alongside multiple PCIe 5.0 slots. Designed as a high-density 4U server capable of housing eight dual-slot GPUs: NVD H200, RTX PRO 6000 Blackwell, RTX PRO 4500 Blackwell or AMD Instinct MI350P PCIe Card, each supporting up to 600 watts.
- [ Enterprise-Grade Reliability ] Minimize downtime and secure your ecosystem with server-grade redundancy. The ESC8000A-E13 is built for 24/7 continuous operation, boasting 2+2 redundant (3200W total) 80 PLUS Titanium power supplies and integrated ASUS ASMB11-iKVM for comprehensive out-of-band management. Ideal for cloud service providers, rendering farms, and large enterprise infrastructure, it combines robust physical hardware with smart remote monitoring to safeguard your digital assets.
- [Reliability Guaranteed] Shop with total peace of mind knowing that every new computer component we sell is backed by our EPC 3-year warranty. Whether you are investing in high-speed DDR5 RAM or a powerhouse GPU, we protect your build against defects and performance failures. We stand firmly behind the quality of our hardware, ensuring that your setup remains fast, stable, and secure for years to come.
Which cost and workflow changes should trigger alerts?
Set alert limits from your own baseline and business tolerance; there is no authoritative universal threshold. Useful signals include:
- Spend or token volume per successful workflow, split by feature, tenant, or team.
- Calls per run, retry rate, and sudden changes in input or output-token distributions.
- Failure rate and latency, so a cost change is not mistaken for an improvement when workflows have become slower or less reliable.
- Sustained budget consumption as well as sudden increases, with trace links that lead to the relevant workflow or call.
Amazon CloudWatch documents generative AI workload views for latency, usage, and errors; end-to-end prompt tracing across components such as knowledge bases, tools, and models; and a Bedrock Model Invocation dashboard with token-consumption metrics and invocation logs. Its documentation lists compatibility with AWS Strands, LangChain, and LangGraph. See CloudWatch generative AI observability.
How to reduce avoidable spend without masking quality problems
Change one cost driver at a time and compare the result against task success or quality, latency, and reliability. Keep the evaluation set and reporting window consistent so you can attribute a change rather than guess at its effect.
Windows Errors? Fix Them Before They Spread
Repair common Windows errors and clear accumulated junk for a smoother, more stable PC - no reinstall needed.Free scan · no reinstallOutdated Drivers Are Slowing You Down
One free scan finds every outdated or missing driver and matches the right update for your exact hardware.Free scan · exact hardware match- Right-size models. Test a lower-tier model for routine steps and define when to escalate. Measure task outcomes, not just token cost.
- Trim prompts and outputs. Remove repeated context, narrow instructions, and set an output limit appropriate to the task. Confirm that shorter inputs or answers still contain what downstream steps need.
- Narrow retrieval. Use relevant filters and a suitable retrieval limit instead of injecting an unbounded set of documents. Check answer quality and coverage for omissions.
- Review retries and orchestration. Fix failure causes and reduce unnecessary transitions or delegated work rather than simply hiding failed attempts from cost reports.
- Use batching or asynchronous handling where suitable. Batching can fit suitable events; asynchronous handling may help applicable serverless workloads. The right choice depends on latency and workload requirements.
- Consider caching for repeated inputs. Verify that inputs are genuinely reusable and that cached results satisfy freshness and correctness requirements.
Do not claim a fixed savings percentage in advance: the result depends on the workload, and lower cost alone does not establish an equivalent result.
Quick Recap
Product prices and availability are accurate as of the date/time indicated and are subject to change. Any price and availability information displayed on Amazon at the time of purchase will apply.

