
iTechGuides is reader-supported. When you buy through links on our site, we may earn an affiliate commission. As an Amazon Associate I earn from qualifying purchases. Learn more
To catch a bad delivery without building a large monitoring stack, combine three signals: application logs for runtime errors, deployment events for release progress, and a health threshold that can notify or trigger a supported rollback. A scheduled log query can alert directly on log-derived counts, while your deployment platform reports whether a rollout is running or failed. There is no universally cheapest setup: cost depends on log volume, query frequency, retention, notification paths, region and provider.
What each signal tells you
| Signal | Answers | Typical use |
|---|---|---|
| Application logs and derived error metrics | Is the application producing errors after the release? | Count relevant errors or calculate an error rate over a defined window. |
| Deployment state events | Is delivery progressing, complete or failed? | Notify on deployment or instance state changes. |
| Health threshold and rollback policy | Should the deployment be stopped or reversed? | Notify a responder or invoke a platform-supported automatic rollback when a suitable alarm breaches. |
These signals complement one another. A successful workflow or completed deployment does not prove the application is healthy; runtime logs do not necessarily reveal whether a deployment is still progressing. For example, CloudWatch Log Alarms run scheduled Logs Insights queries and can invoke configured actions such as SNS or Lambda. That alarm path evaluates logs directly rather than requiring an intermediate metric filter.


Build an error signal that is useful after a release
Emit consistent, safe fields
Structure logs so each relevant record has a stable severity or error field and enough context to identify the service, environment, release or version, and request or operation. Keep secrets and personal data out of alert payloads. A query can only count or group fields that are present and consistently populated; an absent field referenced in an aggregation can leave the query without a usable result.
Choose the error condition and threshold
Filter to the service and environment being deployed, then count server errors or a consistent application-error marker within a bounded lookback. Where traffic varies substantially, consider a normalized rate or a comparison with a baseline instead of treating one raw count as meaningful at every traffic level. This is an implementation choice, not a threshold prescribed by the platform documentation.
#1 Best Overall
For API health, AWS identifies 5XX errors and latency as useful signals. A 4XX response can instead reflect client input, authorization, a missing resource or throttling, so automatically rolling back on every 4XX can reverse a healthy release for a client-side issue. See AWS AppConfig deployment monitoring guidance for these examples.
Configure log-alarm timing and missing data deliberately
In CloudWatch, a Log Alarm runs a Logs Insights query on a schedule, aggregates its results, compares them with a threshold and can invoke configured actions. Available aggregation functions include count, average, sum, minimum and maximum. The alarm configuration includes the query schedule and time offset, threshold, number of recent executions evaluated, number that must breach, and treatment of missing results. Consult the CloudWatch Log Alarms documentation for current setup details and limits.
- Set the window to match the risk. A short schedule may detect a regression sooner but can be more sensitive to noise and increases query frequency. AWS documentation gives
rate(5 minutes)as an example schedule, not a universal recommendation. Tune lookback and evaluation against traffic, acceptable detection delay and cost. - Use M-out-of-N evaluation to balance speed and noise. Requiring several recent executions to breach can avoid reacting to one transient spike, at the cost of slower detection.
- Distinguish no matching errors from missing telemetry. For sparse error events, AWS recommends treating missing query data as
notBreaching. If logs should arrive continuously, missing data may itself indicate a telemetry problem and deserve a different policy. - Account for query failures separately. A failed query or absent fields are not the same as a successful query returning no matching errors; query errors can leave the alarm in an evaluation-error or insufficient-data state.
That distinction matters when alarms control rollback. For example, AppConfig can roll back a configuration deployment when linked CloudWatch alarms enter ALARM or INSUFFICIENT_DATA. If missing data is configured too strictly, a telemetry gap may therefore cause rollback even when no application error was observed.
Quick wins for a faster PC:
Repair Windows errors before they cause bigger problemsFix Now →Scan for outdated or missing drivers - takes under a minuteDriver Scan →Clear out junk files and repair common Windows errorsFree Scan →Use deployment state for progress and failure visibility
Prefer native events where supported
Use deployment-system events or notifications to report progress and state changes rather than trying to infer them from application logs. AWS CodeDeploy monitoring describes deployment and instance status monitoring, event-driven notifications and reactions, including SNS and Lambda targets. Its documentation allows up to 10 CloudWatch alarms to be associated with a deployment group.
Use workflow logs for CI execution status
GitHub Actions workflow monitoring provides a workflow view and logs showing job and step status. This tells you whether the workflow ran or failed; pair it with runtime health monitoring to catch regressions after a workflow succeeds.
Poll only when events are unavailable
Polling can fill an integration gap, but there is no universal safe interval established here. Bound the polling frequency and timeout to avoid unnecessary requests or a process that waits indefinitely; use native state events where available. Set the interval according to the deployment system’s limits and the time in which an operator needs to know about a stalled or failed delivery.
Rank #3

- 2 Years of Cellular Service Included – Necto offers the most affordable cellular-enabled sensor with 2 full years of 4G LTE service included—no hidden fees, contracts, or WiFi required. With a built-in multi-network SIM card, you can remotely monitor conditions 24/7 and receive real-time alerts. After 2 years, you can renew the subscription from the app for only $6.99 a month.
- Instant Alert & 24/7 Monitoring - Keep tabs on your Home, RV, Car, or Pets from anywhere with the 3-in-1 temperature, humidity & power outage monitor. Customize the high and low temp/humidity thresholds and add up to 5 contacts for unlimited text and email alerts. Receive real-time alerts if critical changes in temp/humidity or a power loss occurs.
- Rechargeable Internal Battery - The Necto smart RV and pet monitor has a 3 day long-lasting rechargeable battery. Unlike WiFi sensors, Necto provides continuous monitoring in the event of a power outage, via its built-in battery and cellular technology. Receive instant alerts on your phone when battery power is low or if the device disconnects from the network.
- Intuitive Mobile App & Easy Setup - Our user-friendly mobile app gives you remote access to your sensor from anywhere. Use your smartphone or PC to customize alert thresholds, view past readings, and manage device settings with ease. The sensor takes minutes to install and requires no technical expertise. Simply activate the device through the app and plug it into any standard wall outlet.
- Fast Refresh & Free Data Storage - The industrial built-in temperature and humidity sensor takes readings every 10 seconds to make sure the temp/humidity are within the safe range. Every 10 minutes the most recent reading is updated on the online portal. Readings are stored on our servers for 1 year and can be downloaded anytime on a CSV file.
Choose a rollback path that matches the deployment
AWS AppConfig: configuration rollback from alarms
AppConfig can associate CloudWatch alarms with a configuration deployment and roll back when an alarm reaches ALARM or INSUFFICIENT_DATA during deployment. This is useful when the change is configuration and the alarm measures a relevant health condition. Decide how missing data should behave before linking an alarm to an automatic action.
Amazon ECS: deployment failure detection
Amazon ECS deployment failure detection documents two methods: a deployment circuit breaker and CloudWatch alarm-based failure detection. The documented mechanisms apply to rolling update and blue/green deployment types, and rollback requires a prior deployment in COMPLETED state. Check the deployment type and rollback prerequisite before relying on this path.
Google Cloud Deploy: rollout analysis
Google Cloud Deploy alerts cover failed renders and rollouts. Cloud Deploy analysis can use observability telemetry or a custom container; a triggered alert or nonzero analysis result causes analysis and rollout failure, which can be used as part of a rollback action. See Cloud Deploy deployment verification for analysis behavior and configuration.
Rank #4
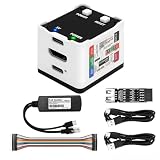
- 【Remote Control Operations Server】Sipeed NanoKVM is an IP-KVM solution based on the LicheeRV Nano RISC-V Linux single-board computer, inheriting the Nano's compact form factor and powerful capabilities. Breaking free from traditional host requirements for network connectivity and system software, NanoKVM functions as an external hardware device directly providing remote control capabilities.
- 【Powerful Interfaces】Sipeed NanoKVM features one HDMI input port that can be recognized by a computer as a display to capture screen content. One USB 2.0 port connects to the computer host, functioning as a HID device (e.g., keyboard, mouse, touchpad). It also utilizes spare TF card storage space, mounting it as a USB flash drive device.
- 【100Mbps Ethernet Support】Sipeed NanoKVM features a 100Mbps Ethernet port for network transmission of video and control signals. The Full version additionally includes an ATX power control interface (USB-C) for remote host power status monitoring and control. The Full version housing also incorporates an OLED display showing the device's IP address and KVM-related status.
- 【Server Management】Sipeed NanoKVM enables real-time monitoring and control of server operations. Supports remote desktop access and host power cycling: NanoKVM overcomes limitations requiring the host to be networked or specific system software, functioning as external hardware to provide direct remote control capabilities.
- 【Supports Remote Installation】Sipeed NanoKVM emulates a USB flash drive device, enabling mounting of installation images for system deployment or access to computer BIOS settings. The NanoKVM Lite features two serial ports for use with IPMI or connection to other development boards via web-based serial terminal interaction. Users may also expand functionality with additional accessories.
Automatic rollback is most appropriate when the health signal is timely, specific to the changed service and meaningful for the deployment type. Keep a human response path for ambiguous failures, and validate rollback behavior in a safe environment before depending on it in production.
Independent reader supportYour contribution helps us test, update, and keep practical guides available for everyone.Compare the options on operational fit, not a guessed price
| Approach | What it provides | What to assess |
|---|---|---|
| Scheduled log-query alarm | Log-derived counts or other aggregations, threshold evaluation and notification actions. | Query schedule and lookback, alert delay, missing-data policy, log and query costs, IAM permissions, and contributor limits. CloudWatch allows up to 500 contributor results per query execution, five fields in a by clause, and 100 contributors simultaneously in ALARM. |
| Deployment-platform alarms or events | Deployment-state visibility and, for supported products and configurations, stopping or rollback behavior. | Provider and deployment-type compatibility, prior-good-version requirements, signal quality, and whether rollback affects configuration or application artifacts. |
| Google Cloud Deploy alerts and analysis | Alerts on failed renders and rollouts; analysis can fail a rollout based on telemetry or a custom check. | Pipeline fit, telemetry integration, custom-check maintenance and operational rollback setup. |
| Workflow status view | Job and step execution status with workflow logs. | It reports workflow execution, so runtime monitoring is still needed for post-release application health. |
These features do not establish which design costs least for an unspecified workload. Estimate against your own log ingestion volume, query cadence, retention, region, alert destinations and expected rollout frequency before choosing.
The Tool Desk
Outbyte PC Repair FREEClear out junk files and repair common Windows errorsFree Scan →Outbyte Driver Updater FREEFix the driver behind crashes, sound loss and screen glitchesFind Drivers →Quick Recap
Limits and failure cases to plan for
- Errors are not consistently logged: improve instrumentation before trusting a count threshold; missing or inconsistently named fields can undermine the query.
- Normal background traffic triggers the alarm: narrow the service and environment, refine the error class, and consider a rate or baseline rather than an unqualified count.
- The alarm is quiet because there are no matching events: decide whether that is healthy silence or a missing-telemetry condition based on whether log traffic is expected to be continuous.
- A query error looks like missing or insufficient data: inspect the query and its fields rather than assuming the application is healthy or unhealthy from that state alone.
- Deployment status is green but users see errors: the release workflow and rollout state do not replace post-deployment application health checks.
- Rollback cannot find a good version or does not fit the deployment type: verify platform prerequisites, including the prior completed deployment requirement for the documented ECS rollback path.
Product prices and availability are accurate as of the date/time indicated and are subject to change. Any price and availability information displayed on Amazon at the time of purchase will apply.

