
Android apps can route machine-learning inference to a CPU, GPU, or vendor-specific neural accelerator—but you should not assume a model will automatically be split into concurrent CPU, GPU, and NPU work. In practice, the runtime and device determine which operations a delegate can handle. Choose a supported execution path, keep a CPU fallback, and benchmark the exact model on representative phones.
What “heterogeneous AI parallelism” means on Android
Android devices can contain several kinds of compute hardware, but having a CPU, GPU, and NPU does not mean a model automatically uses all of them at once. A runtime typically assigns supported operations or subgraphs to a delegate or backend. Unsupported operations may remain on the CPU, and a delegate may fail to initialize altogether. That is workload routing; it is not proof of fine-grained, simultaneous execution across every processor.
For a useful comparison, treat each runtime-and-backend combination as a candidate implementation. Check which model operations it supports, whether its numerical results are acceptable, and whether its end-to-end performance improves your app.
Choose an inference route
Google describes LiteRT as its on-device inference engine. Its current 2.x overview recommends the CompiledModel API for developers seeking state-of-the-art performance; the Interpreter API remains available for backward compatibility. The Android quick-start lists CPU, GPU (OpenCL/OpenGL), and NPU targets, with Android API 24+ as the minimum SDK. Its Kotlin/C++ setup references Android Studio Ladybug (2024.2.1)+ and Android NDK r26a+ for C++. See LiteRT getting started for current setup guidance.
What’s actually slowing this PC down?
Pick the symptom - the matching free tool is one click away.
#1 Best Overall

- 【Strong Adsorption】The inspiration of the silicone phone suction case comes from the adhesive force of the octopus. Each suction cup phone mount is 3.15 inches long and 2.17 inches wide, with 24 independent suction cups providing a stronger and more stable suction force, so you don't have to worry about your phone falling during use.
- 【Back of Phone Suction Grip】Remove the adhesive film on the phone suction cup and stick it on the phone case. You can then fix the phone on any smooth surface, which is very convenient. (The phone suction cup cannot be removed and reused after being attached to the phone case. It is recommended to attach it to a regular phone case, not a valuable one.)
- 【Widely Used】Our non-slip silicone phone sticky grip mount attaches to almost any flat phone case and make it compatible with common mobile phones such as iPhone and Android.You can shoot, watch videos or video calls in the kitchen, gym, dance studio, bathroom and other places.
- 【Capture the Wonderful Picture】Whether you are a TikTok creator or just like to share videos and photos, this phone suction cup can help you hands-free capture wonderful videos and photos for sharing with friends.
- 【Note】You can fix the phone suction cup on a smooth surface such as a mirror or glass. If necessary, wipe the suction cup with a damp cloth to obtain stronger suction. Before releasing your hand, make sure the phone is firmly fixed. (Not applicable to rough walls, wooden surfaces, and other uneven surfaces)
| Route | What it offers | What to check |
|---|---|---|
| CPU | A practical compatibility baseline and fallback. | Thread configuration, initialization cost, memory, and sustained behavior for the actual workload. |
| GPU delegate | LiteRT GPU acceleration through Google Play services or the standalone LiteRT distribution. | Supported operations, device compatibility, precision and correctness, initialization, and contention with graphics work. |
| Vendor neural accelerator | A vendor-provided delegate can expose hardware such as an NPU, HTP, or DSP to a runtime. | Availability and support vary by vendor, device, driver, model, and runtime; initialization can fail. |
| NNAPI | A historical Android dispatch API for ML frameworks and tools. | It is deprecated in Android 15; new performance-critical work should consider current alternatives. |
Android’s LiteRT guidance describes runtime and delegate access through Google Play services, GPU delegates, partner custom delegates, and an Acceleration Service API that can select an optimal configuration at runtime. Availability depends on the deployment environment, including whether Google Play services is present; do not treat this service as a guarantee that every custom delegate or device is covered. See Android’s LiteRT guidance.
Use the CPU as a baseline and fallback
Start with CPU inference using the same model artifact, inputs, preprocessing, and output checks you will use for accelerator tests. This gives you a compatibility reference and a recovery path for devices where an accelerator is unavailable or unsuitable. It does not establish that a GPU or NPU will be faster: initialization, operation coverage, precision, and application workload all affect the result.
Rank #2

- SUPERIOR COMFORT — Unlike traditional circular ear buds, the design of EarPods is defined by the geometry of the ear. Which makes them more comfortable for more people than any other ear bud–style headphones.
- HIGH-QUALITY AUDIO — The speakers inside EarPods have been engineered to maximize sound output and minimize sound loss, which means you get high-quality audio.
- BUILT-IN REMOTE — EarPods with USB-C plug also include a built-in remote that lets you adjust the volume, control the playback of music and video, and answer or end calls with a pinch of the cord.
- COMPATIBILITY — Works with all devices that have a USB-C port.
- INTEGRATED MICROPHONE — A built-in microphone precisely captures your voice while you’re on the phone, taking a FaceTime call, or summoning Siri — so you’re always heard loud and clear.
Google’s LiteRT delegate documentation describes a benchmark tool for estimating latency and memory across configurations. Treat its output as a way to compare candidates, not as a substitute for measuring your app on its target hardware.
When a GPU delegate makes sense
LiteRT documents Android GPU integration through Google Play services and through the standalone distribution. The standalone guide describes checking device compatibility before adding the delegate and configuring CPU execution when the GPU is unsupported. One integration constraint matters in threaded apps: initialize the GPU delegate on the same thread that invokes it. The guide also says Android GPU delegate libraries support quantized models by default. Follow the current GPU delegate guide for the selected integration path.
Do these 3 things before closing this tab:
1Scan for outdated or missing drivers - takes under a minute2Repair Windows errors before they cause bigger problems3Fix the driver behind crashes, sound loss and screen glitchesRank #3

- Secure Hold: Our PopSockets adhesive phone grip gives your cell phone a secure, comfortable hold in hand to help prevent drops while texting, taking photos, or scrolling on the go. Designed to stick firmly to most phone cases and devices.
- Hands-Free Made Easy: Easily turn your PopSocket into a phone stand to prop up your phone anywhere, perfect for watching videos, video calls, or following recipes. A must-have phone holder that keeps your device secure and ready for anything.
- Compatibility: Works with all phones, tablets, and Kindles. Sticks best to smooth, hard plastic cases and may not adhere to silicone or textured cases. Easily swap your PopTop to change up your style.
- Black PopSockets: Simple, refined, and endlessly versatile. A timeless essential for any phone.
- Travel Must-Have for People On the Go: A must-have travel accessory for flights, flying, airports, air travel, airplanes, planes, international trips, cruises, and long travel days. Key gadget for your airport haul, travel accessories and must-haves.
A GPU is not a universal speed switch. Delegate coverage and speed depend on the model and device, and inference may compete with rendering or other GPU work. If the app is drawing a busy interface while running inference, profile the full app experience as well as isolated inference latency.
When an NPU or other vendor accelerator makes sense
Android does not provide one universal NPU delegate that works identically across manufacturers. LiteRT’s NPU guidance describes vendor-provided delegates. Its Qualcomm example uses the AI Engine Direct/QNN delegate with the HTP backend and handles delegate-creation failure with UnsupportedOperationException. That is a Qualcomm-specific route, not a general Android NPU API. See Google’s Qualcomm NPU guide.
Rank #4

- [360 ° Flexible Rotation Design] Comes with a rotatable lanyard ring that supports 360 ° free rotation, effectively solving the problem of twisted and tangled lanyards
- [Wide compatibility] The ultra-thin 0.02-inch design does not block the charging port at all, and both wired and wireless charging can be used directly without removing the pad. Compatible with most smartphones such as iPhone, compatible with various wristbands, lanyards, crossbody straps, and keychains
- [Durable and Portable Material] Premium rust-resistant stainless steel material with good flexibility, which not only avoids scratching the phone case, but also has excellent anti rust and anti fading performance
- [Multi scenario Practical] Paired with a lanyard or wristband, hands-free use can be achieved. The phone is within reach and not easily dropped, ideal for daily commuting and outdoor activities. Suitable for full coverage phone cases, does not support half coverage phone cases
- [Quality Service] If you find any damage or other issues with the product upon receipt, please contact us immediately. We will handle it quickly
Plan for capability checks and a viable fallback. A device can expose neural hardware yet still lack a compatible delegate, driver, model-operation implementation, or initialization path for your app. Confirm that the intended model actually runs on the chosen backend, and verify its output against your CPU reference.
How to interpret published Qualcomm comparison figures
The following figures are from Qualcomm AI Hub results reproduced on Google’s page and labeled “for representation only.” Google describes the models as open-source and pre-optimized as part of AI Hub Models. They are vendor-platform results, not independent tests or a promise of performance on other devices, models, or builds.
PC Slower Than It Used to Be?
A free scan shows the junk files, broken settings and background clutter dragging Windows down - then fixes them in one click.Free scan · Windows 10 & 11Outdated Drivers Are Slowing You Down
One free scan finds every outdated or missing driver and matches the right update for your exact hardware.Free scan · exact hardware matchBest Value
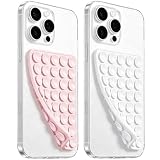
- 【PKYAA Double Sided Silicone Suction Phone Case Mount】PKYAA With Double Sided 40 Strong and Reliable individual suction cups, PKYAA provides a thicken and upgraded universal silicon suction mount for your phone.
- 【Friendly to Content Creators】If you are a content creator or an online influencer, you can create videos anywhere with this suction mount completely hands free with this silicone cell phone mount for cases.
- 【HANDS-FREE & Adhere to Mirrors】This Double Sided silicone suction phone case mount allows you to stick your phone to the mirror easily. No longer holding your phone in one hand to watch video tutorials while making up.
- 【Strong Grip on the Smooth Surface】You can easily hang your phone anywhere with a smooth surface. All you do is you clean off your phone and smooth surface. It is STURDY and it not only sticks to mirrors, it also sticks to windows, it sticks to refrigerators, tiles and other clean, flat surfaces.
- 【Press Down Firmly Every 30 Minutes】Use your palm or fingers to press the phone down firmly and check it's secure before letting go. Apply even pressure for a few seconds to allow the suction cup to adhere properly. To maintain the grip and prevent accidental falls, it's a good practice to periodically reapply pressure to the suction cup.
| Model | Phone | NPU | GPU | CPU |
|---|---|---|---|---|
| MobileNetV2 | Samsung S25 | 0.3 ms | 1.8 ms | 2.8 ms |
| MobileNetV2 | Samsung S24 | 0.4 ms | 2.3 ms | 3.6 ms |
| MobileNetV2 | Samsung S23 | 0.6 ms | 2.7 ms | 4.1 ms |
| FFNet-40S | Samsung S25 | 24.9 ms | 43 ms | 481.7 ms |
| FFNet-40S | Samsung S24 | 29.8 ms | 52.6 ms | 621.4 ms |
| FFNet-40S | Samsung S23 | 43.7 ms | 68.2 ms | 871.1 ms |
These values illustrate why results can differ by model and device; they do not establish a universal NPU speedup. Use the linked page’s context when interpreting them, and measure your own model and application.
Independent reader supportYour contribution helps us test, update, and keep practical guides available for everyone.Treat NNAPI as legacy context for new performance work
NNAPI was designed as a framework-facing API whose runtime could distribute operations to available neural hardware, GPUs, or DSPs, and could use the CPU when a specialized vendor driver was missing. But the Android NDK documentation marks NNAPI deprecated in Android 15 and recommends considering alternatives for performance-critical workloads, including the TensorFlow Lite GPU runtime. Its warning says: “NNAPI is deprecated. While you can continue to use NNAPI, we expect the majority of devices in the future to use the CPU backend, and therefore for performance critical workloads, we recommend migrating to alternative solutions, for example the TF Lite GPU runtime.” Read the current Android NDK NNAPI documentation before making a migration decision, since platform guidance can change.
Benchmark the configuration your users will run
Compare candidates on physical phones representative of your audience. Emulator results or one flagship phone cannot establish coverage or performance across Android devices. Use a repeatable workload and record the model, device, OS and runtime versions, delegate/backend, precision, warm-up policy, and measurement method.
- Establish a CPU reference. Fix the model file, test inputs, preprocessing, and output validation so the baseline and accelerator runs are comparable.
- Check delegate support and initialization. On each target device class, verify that the runtime and backend can be created and that the required model operations are supported. Record unsupported operations, initialization errors, and fallback behavior.
- Measure initialization and steady-state inference. Use LiteRT’s benchmark tooling to estimate average latency, initialization overhead, and memory footprint. The Android benchmark example invokes a GPU configuration with
adb; use the documentation for the exact command and options for your setup. - Check correctness as well as speed. Delegate computations may use different precision from CPU computations, so compare outputs or task-level accuracy against your acceptance criteria.
- Profile the application, not just the model. Measure end-to-end behavior when inference shares the device with UI rendering or other app work. Test sustained workloads and report thermal or power behavior only if you have measured it.
- Select per supported configuration and preserve fallback behavior. Keep CPU execution available, and use runtime selection only where the chosen route has passed compatibility, correctness, and performance checks.
Compare more than average latency: include operator coverage, numerical correctness, cold-start or compilation cost, throughput, memory footprint, device/OS/driver coverage, integration and binary-size cost, and contention with other work. Power and thermal behavior are useful comparison axes when measured, but the cited documentation does not establish a controlled cross-device battery or thermal result.
Recommended Free Tools
Make the deployment decision from measured trade-offs
There is no single accelerator choice that is best for every Android model. Prefer the route that passes correctness checks and improves the real application on the devices you intend to support. A GPU delegate or vendor NPU path can be valuable where model support and hardware align; CPU execution remains the practical baseline and fallback. Keep device coverage, initialization cost, memory, and app-level behavior in the decision rather than treating a delegate label as a performance guarantee.
Quick Recap
Product prices and availability are accurate as of the date/time indicated and are subject to change. Any price and availability information displayed on Amazon at the time of purchase will apply.

