
Free tools Windows power users keep installed
One-click scans. No signup required.
iTechGuides is reader-supported. When you buy through links on our site, we may earn an affiliate commission. As an Amazon Associate I earn from qualifying purchases. Learn more
There is no proven overall winner among MLX’s affine, mxfp4, and nvfp4 4-bit modes. The mlx-lm converter defaults to affine, but that default does not show it performs worse—or better—than the alternatives. The right choice depends on your model, task, Apple silicon device, and priorities for output quality, memory, speed, and compatibility.
What 4-bit formats does the MLX converter offer?
The mlx-lm converter accepts four quantization modes: affine, mxfp4, nvfp4, and mxfp8. The last is an 8-bit mode, not a 4-bit option. The converter source on the moving main branch lists these defaults; they may change, so check the version you are using. mlx-lm converter implementation.

| Mode | Default bit width | Default group size |
|---|---|---|
| affine | 4 | 64 |
| mxfp4 | 4 | 32 |
| nvfp4 | 4 | 16 |
| mxfp8 | 8 | 32 |
The CLI also exposes --q-bits and --q-group-size, so the defaults are configurable. A different default group size means these modes are not necessarily a like-for-like comparison when left at their defaults.
Do these 3 things before closing this tab:
1Fix the driver behind crashes, sound loss and screen glitches2Clear out junk files and repair common Windows errors3Scan for outdated or missing drivers - takes under a minuteDoes affine start at a disadvantage?
No conclusion about quality, speed, or memory follows from the default alone. The implementation establishes that affine is selected by default and that the converter offers alternatives; it does not establish that affine is intentionally disadvantaged or that another mode is universally better. The official sources cited here do not provide a controlled head-to-head benchmark proving an overall winner.
#1 Best Overall
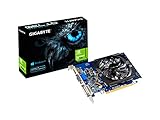
- Digital Max Resolution:4096 X 2160.Form Factor:ATX.Analog max resolution 2048 x 1536
- Powered by NVIDIA GeForce GT 730 GPU
- Integrated with 2048MB DDR3 memory and 64-bit memory interface
- Core Clock: 902MHz.Avoid using unofficial software
- Features Dual-Link DVI-D / HDMI / D-Sub
Why “4-bit” does not tell the whole storage story
Nominal bit width is not identical to effective storage per weight. The Hugging Face transformers-to-MLX guide estimates that 4-bit quantization with group size 64 typically uses about 4.5 effective bits per weight once scale and bias metadata are included. This is a rough estimate from that guide, not a universal measured figure for every mode or model. Hugging Face Transformers-to-MLX guide.
For that reason, compare converted artifact size and peak memory rather than assuming that every format labeled 4-bit produces the same total footprint.
Rank #2

- Powered by Radeon AI PRO R9700 - Supercharge you workflow with the cutting-edge RDNA 4 Architecture and 2nd-gen AI Accelerators.
- 32GB GDDR6 with 256-bit memory bus - Tackle larger, more complex projects without limits.
- PCIe Gen 5 - Unlock lightning-fast data transfers with PCIe Gen 5 support.
- GIGABYTE TURBO Fan Cooling System - Indented metal cover and blower fan increase airflow intake, while the vapor chamber, all copper heat sink, and metal frame offer efficient heat dissipation. Optimized airflow design allows for easy multi-GPU scalability.
- Double Ball Bearing Fan - Delivers superior heat resistance and rotational efficiency for better performance and a longer lifespan compared to conventional sleeve fans.
Could mixed precision be a better fit?
Uniform 4-bit conversion is not the only option. mlx-lm includes mixed-bit recipes that assign more bits to selected components, including value projections, down projections, and the language-model head, while leaving other quantizable layers at fewer bits. The exact allocation depends on the recipe.
The Tool Desk
Outbyte Driver Updater FREEFix the driver behind crashes, sound loss and screen glitchesFind Drivers →Outbyte PC Repair FREEClear out junk files and repair common Windows errorsFree Scan →Apple’s WWDC25 MLX LM demonstration shows a custom predicate assigning 6 bits to lm_head and embed_tokens, 4 bits to other quantizable layers, and skipping modules that cannot be quantized. This illustrates how bit allocation can differ across layers; it is not evidence that this particular recipe is best for every model. Apple’s WWDC25 MLX LM demonstration.
Rank #3

- 【Easy to Use】 Just put a card into the reader machine, the reader will pronounce the words automatically.
- 【Play Music】New added music function, the machine can play 4 songs about happy birthday, ABC, dog, and Christmas.
- 【Lively voice】When toddlers choose an animal card inserted into the machine, it will issue American standard pronunciation and then vivid animal sounds, making toddlers full of interest in learning.
- 【Two Pronunciation Modes】You can switch between the two pronunciation modes by pressing the button: (1) Only pronounce the sound of English. (2) Pronounce the sound of English first, and then pronounce the sound of Spanish.
- 【Rich learning resources】 Each card is printed in English and Spanish, along with the corresponding graphic. Contains 521 sight words, covering almost all fields, including ABC letters, numbers, shapes, colors, animals, vehicles, food, and more. Expose toddlers to many unknown objects, full of imagination.
How to decide which mode is best for your workload
Choose a comparison that matches what you need the model to do. Keep the model, device, runtime, and workload consistent; otherwise, a measured difference may reflect something other than the quantization mode.
- Define the task and quality measure. Use a stated evaluation set or repeatable task-specific prompts, with a scoring method you can apply to every candidate.
- Compare storage and memory. Record converted artifact size and peak memory, accounting for metadata overhead rather than relying on nominal bits alone.
- Measure speed under the same conditions. Keep runtime, prompt length, generation length, and device the same for each run.
- Check compatibility. Verify that the model architecture and runtime support the selected mode, then confirm that the converted model loads and behaves as intended.
- Document bit allocation. Distinguish a uniform 4-bit conversion from a mixed-bit recipe. Their labels do not mean every layer has the same precision.
A defensible winner is the mode—or layer allocation—that performs best against your stated priorities in this controlled comparison. Without measurements for a named model, device, software version, and workload, the available evidence does not identify one.
Independent reader supportYour contribution helps us test, update, and keep practical guides available for everyone.Where MLX fits
MLX LM is intended for language-model work on Apple silicon, and Apple’s developer material demonstrates model conversion and quantization. The cited material does not establish that a particular Mac model or memory configuration is required. Apple’s WWDC25 MLX LM demonstration.
Quick Recap
Product prices and availability are accurate as of the date/time indicated and are subject to change. Any price and availability information displayed on Amazon at the time of purchase will apply.

