
Free tools Windows power users keep installed
One-click scans. No signup required.
iTechGuides is reader-supported. When you buy through links on our site, we may earn an affiliate commission. As an Amazon Associate I earn from qualifying purchases. Learn more
In a one-day snapshot taken on September 23, 2026, SerpPrism found a Sitemap line in 54 of 71 usable robots.txt files from a hand-picked set of high-traffic sites. Seventeen had no Sitemap line. These results describe those files on that date—not all websites, and not necessarily the sites’ current configurations.
What did the 71-site snapshot find?
SerpPrism’s survey by Hongtao Ren examined robots.txt files fetched from 78 manually chosen, high-traffic domains across news, ecommerce, SaaS, developer, social, finance, education, and government categories on September 23, 2026. Seventy-one returned usable plain-text files. Two responses were HTML, and five files could not be read: four returned HTTP 403 or 418, and one returned 404. The fetch used curl directly and, where needed, through a local proxy; 46 usable files came directly and 25 through the proxy. Ren notes that this split was not evenly distributed across categories.


The files were parsed line by line with user-agent groups respected. The counts below are observations of those 71 files, not estimates for the web as a whole.
Quick wins for a faster PC:
Scan for outdated or missing drivers - takes under a minuteDriver Scan →Repair Windows errors before they cause bigger problemsFix Now →Fix the driver behind crashes, sound loss and screen glitchesFind Drivers →| Observation | Count in the snapshot |
|---|---|
| At least one Sitemap line | 54 of 71 (76%) |
| More than one Sitemap line | 26 of 71 |
| No Sitemap line | 17 of 71 (24%) |
| Crawl-delay in the wildcard (User-agent: *) group | 5 of 71 |
| A declared sitemap blocked by the same site’s Disallow rule | 0 of 71 |
The source’s domain list and parsing script are published with the SerpPrism article. Because robots.txt files can change, named-site examples below should be read as September 23, 2026 observations.
#1 Best Overall

- Upgraded Two Zipper Pockets: Forvencer server books feature two secure zipper pockets for better organization of coins, cash, and receipts, ensuring that everything you collect has a safe and secure place
- Smart Storage & Quick Access: Designed with 8 multi-functional compartments, the right side includes a guest receipt pad, while the left has a money pocket, ticket pocket, and credit card slot. Two small clear pockets store bills, receipts, and other visible items. A stitched pen loop ensures you always have your favorite pen ready
- High-quality & Easy to Clean: Crafted from high-quality PU leather with heavy-duty stitching, this server book is built to last. It resists tears, scratches, and its waterproof surface makes cleaning easy with just a damp cloth or a non-chlorine sanitizer
- Perfect Fit for Your Apron: Measuring 5” x 8”, this compact organizer is slightly smaller than other models, making it ideal for bending or sitting while carrying in your server apron. It holds everything a waitress needs—a place for everything
- What's Included: This server organizer comes with multiple open and zippered pockets to store money, receipts, tips, etc. Clear sleeves are perfect for keeping menus or special lists while serving. Available in a variety of colors, allowing you to express yourself even when in uniform
Is a sitemap in robots.txt required?
No. A Sitemap line is one way to tell crawlers where a sitemap is; it is not required for a site to have a sitemap. In the snapshot, 17 files had no Sitemap line: Forbes, Amazon, Etsy, Shopify, GitHub, GitLab, Reddit, LinkedIn, Quora, npmjs.com, Python.org, Go.dev, Mozilla.org, W3.org, Ahrefs, Screaming Frog, and MIT.
That finding means only that the inspected robots.txt response did not declare a sitemap. Google also allows site owners to submit sitemaps through Search Console, and its documentation describes sitemap submission as a hint rather than a guarantee that Google will fetch or use the file. See Google’s sitemap guidance. To determine whether a site has submitted a sitemap, inspect its Search Console if you have access; the public robots.txt file alone cannot answer that.
Rank #2
Does Google support Crawl-delay?
No. Google’s robots.txt specification says Google supports fields including user-agent, allow, disallow, and sitemap; other fields such as crawl-delay are not supported. A Crawl-delay line therefore should not be treated as a way to control Googlebot.
SerpPrism found Crawl-delay in the wildcard group of five sampled files: X, Tumblr, Vimeo, Semrush, and Search Engine Land. It also reported a separate GitHub group for AI crawlers—GPTBot, OAI-SearchBot, ClaudeBot, anthropic-ai, and PerplexityBot—with Crawl-delay: 1. Those are site-specific, date-bound observations. Crawler behavior and support for directives can differ, so do not assume that a rule documented for one crawler applies to another.
Rank #3

- 5 Pockets & 1 Pen Hook: Keep essentials neatly organized with 5 pockets for cash, cards, receipts, and guest checks, plus a pen holder for easy access.
- Perfect Size for Aprons: Compact 5”x7” size fits comfortably in aprons without poking or bulging. Expandable design ensures easy handling, helping you stay professional and efficient.
- Durable & Easy to Clean: Made from premium, cruelty-free PU leather that’s water-resistant and scratch-proof. Easy to clean, ensuring it stays looking great through busy shifts.
- Stay Organized on the Go: Designed to keep everything securely in place, this server book helps you stay organized even during the busiest shifts, so you can focus on providing great service.
- High Quality at an Affordable Price: A well-crafted server organizer that offers premium quality at a reasonable price, trusted by waitstaff for everyday use.
Can a sitemap live on another domain?
Yes, under Google’s documented rules, a Sitemap URL in robots.txt can point to a different host. It must be a fully qualified URL, and a file can contain multiple Sitemap declarations. The survey recorded two cross-host examples: notion.so listed 11 sitemap URLs on www.notion.com, while trello.com listed one on a594014.sitemaphosting7.com.
A cross-host declaration is not, by itself, a protocol violation. It does create an operational dependency: the sitemap host must remain available and the published sitemap must remain current. Google’s requirements are described in its robots.txt documentation.
Rank #4
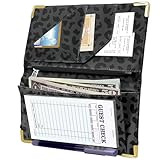
- Tylish Design: This waitress book with money pocket and zipper is a magnificent product with a striking design, which will impress the server as well as the customers. With so many other guest book just being boring and generic, our cute server book guest book is different because of unique design elements and All over printing that make it eye-catching for customers
- Large Capacity: Our waiter book included 7 pockets to keep staff organized; Ideal for keeping credit card, menu, bill, coins, dollars, order paper, pen; Waitress book with money pocket to keep your coins secure without falling out
- Premium Materials: This portable server wallet closure size is 5″x 7.9″, designed to fit easily into server apron pockets; The waitress book for servers is easy to hold in one hand, you can quickly grab and use whenever you need to take orders, helping you stay organized and efficient
- Useful and Stretch: High quality soft PU leather for this premium server book, make it light weight,sleek and desirable, excellent non slip water resistant and durable qualities whilst retaining that professional and fashionable look
- Durable and Easy to Clean: Designed to withstand the demands of the job, this server book is built to last. The waterproof material not only protects against spills and stains but also wipes clean easily, maintaining its pristine appearance even with regular use
What should I check in my own robots.txt?
- Request the exact file for the relevant site. robots.txt applies to a particular host, protocol, and port, and belongs in that host’s top-level directory. Check the response body as well as the status code. Google expects UTF-8 plain text, but says it attempts to parse an HTML response and extract rules while ignoring other content.
- Read rules in their user-agent groups. Confirm that a directive is in the group for the crawler you intend to affect. A rule for a named bot is not automatically a site-wide rule; Google documents its supported fields and parsing behavior in its robots.txt guide.
- Look for sitemap declarations without treating absence as proof. If there is no Sitemap line, check sitemap submission through Search Console or other discovery routes before concluding that no sitemap exists.
- Check that sitemap URLs are fully qualified and reachable. Multiple declarations and cross-host URLs are permitted by Google’s rules. SerpPrism observed HTTP sitemap URLs for theguardian.com and who.int; both reportedly redirected. Treat an HTTP declaration as a reason to verify the current destination and maintainability, not as proof that the sitemap failed.
- Match the control to your goal. Use robots.txt to manage crawler access, not as a reliable way to remove a URL from Google or protect private information.
In the snapshot, khanacademy.org and cdc.gov returned HTTP 200 with HTML at /robots.txt, which SerpPrism characterized as a soft 404. Google says it may parse HTML and extract rules while ignoring other content, so inspect the actual response rather than assuming every crawler treats HTML as a total failure.
The Tool Desk
Outbyte PC Repair FREEClear out junk files and repair common Windows errorsFree Scan →Outbyte Driver Updater FREEFix the driver behind crashes, sound loss and screen glitchesFind Drivers →Does robots.txt keep a page out of Google?
No. Google describes robots.txt as a way to tell crawlers which URLs they may access, mainly to manage crawling. It is not a dependable indexing-removal or privacy control: a blocked URL may still appear in Search, for example if it is discovered through links. To prevent indexing, allow Google to crawl the page and use a noindex directive. To protect confidential content, require authentication or use another access control. Google explains the distinction in its introduction to robots.txt.
Quick Recap
Product prices and availability are accurate as of the date/time indicated and are subject to change. Any price and availability information displayed on Amazon at the time of purchase will apply.

