
iTechGuides is reader-supported. When you buy through links on our site, we may earn an affiliate commission. As an Amazon Associate I earn from qualifying purchases. Learn more
Magnitude is an open-source inference engine for running open models locally and connecting them to agent clients. Magnitude says it compiles and tunes kernels on the user’s hardware, but its public product page and README do not explain the underlying algorithms or architecture. The available evidence supports a clear account of what the software does and what Magnitude reports about performance—not a detailed, inside-the-engineering story of how it was built.
What Magnitude is—and what it is not
Magnitude describes itself as an inference engine for agents: software that runs an open model on your computer and makes that model available to an agent client. It is not itself a new AI model, and it is not an agent framework. The model supplies the language-model capability; Magnitude provides the local inference layer and connection options.


Magnitude calls the project open source and identifies its license as Apache 2.0. Its README and product page are the primary public descriptions of the product.
Free tools Windows power users keep installed
One-click scans. No signup required.
What “self-optimizing” means in Magnitude’s description
Magnitude says it compiles and tunes kernels on the user’s device for that hardware, then runs open models. In broad terms, the claim is that the inference software is adapted to the machine it runs on rather than relying only on a single generic configuration. This is Magnitude’s description of its approach, not an independently verified explanation of its implementation.
#1 Best Overall
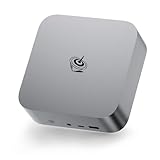
- 🔥【Powerful Performance & Cool】Beelink SER9 ryzen mini pc equips with 8-core/16-thread AMD Ryzen 7 H 255(up to 4.9GHz), The base frequency is 3.8GHz / the dynamic frequency can reach 4.9GHz. Beelink mini pc ryzen is a robust hub for your every work and gaming need. New Airflow Design -MSC2.0, air intake from the bottom is so efficient at dissipating the heat that SER9 can keep very low fanspeed to stay cool and stable, ensuring near-silent operation.
- 🔥【Lastest GPU 780M & RDNA3】Beelink PC integrates AMD Radeon 780M 12core 2600 MHz GPU to deliver powerful graphics processing power to easily handle the demands of complex design software, 4K UHD video editing, and playback, or running AAA games. High frame rates, high graphics quality, and high resolution provide you with an immersive gaming experience. And It can connect 3 screens via HDMI 2.1& DisplayPort 1.4 & Full Featured USB4 to efficiently handle your tasks and meet your specific needs.
- 🔥【Large Capacity Storage & Quiet】The AI Mini PC comes with 64GB DDR5 Memory(can upgrade to 256GB, 2 x 128GB), which can deliver you the smoothest experience in AI computing. There are also Dual M.2 PCle 4.0 x4 SSD slots under the hood, supporting up to 8TB of fast internal storage. Multitask working can be performed smoothly, and all your necessary software applications can be accommodated in this small machine. Beelink Mini PC uses MSC2.0 cooling system, air intake at the bottom and air dissipation at the back achieve high efficiency heat dissipation. The SER9 operates at a noise level of as low as "32dB", so you can simply enjoy undisturbed gaming in peace.
- 🔥【Multiple Interfaces & Wireless】Beelink Mini PC has a 10Gbps Ethernet LAN (RJ-45, Network interface speed up to 10Gbps bandwidth rate), 2.4Gbps WiFi6(802.11ax, stronger capacity of resisting disturbance), and built-in Bluetooth 5.2, high-speed wireless connection makes you step ahead. And 2*USB3.2 ports(10Gbps), 2*USB2.0 ports, 1*HDMI port, 1*DP port, 1*USB-C port(USB4 40Gbps), 1*USB-C 10Gbps port and 1*Audio Jack (HP&MIC), 1*DC Jack, thus offering the user even greater versatility in use.
- 🔥【Lifetime After-sales Service】Beelink has been dedicated to R&D Mini PC for many years. All Beelink Mini-PC have passed strict inspections before shipping. If you have any questions, please don’t hesitate to contact Us. We are 100% guaranteed to solve your problems. We offer lifetime technical support, a 3 year warranty, and 24/7 after-sales service. All of our products obtained FCC, RoHS, and CE Certifications.
The public materials reviewed do not specify the compiler stack, how candidate kernels are generated or searched, what optimization objective is used, or how the runtime manages memory and schedules work. They also do not provide enough detail to explain the internal tuning algorithm. It would therefore be misleading to describe a particular kernel-search strategy or architecture as established fact.
For a user, the practical distinction is simpler: Magnitude says the device-specific compilation and tuning happen on the local machine, while the model inference and agent connection are also designed to run locally. The product description does not establish that every model or supported device will receive the same speedup.
Rank #2

- Next-Gen AI & LLM Local Deployment: Powered by the 8845HS processor and RTX 5060 GPU, this NAS provides incredible computing power to deploy 70B large language models and local AI programming environments seamlessly, keeping your data 100% private.
- Real-Time 4K/8K Video Editing Hub: Built for studios and creators. The dedicated graphics card accelerates hardware rendering, allowing your team to collaborate and edit multi-track high-resolution video directly on the server without downloading.
- Heavy-Duty Virtualization & Docker: Say goodbye to lag. High-speed system architecture ensures smooth performance when running multiple virtual machines, complex Docker containers, and full-scale smart home control centers simultaneously.
- Ultimate Multimedia Transcoding: Experience flawless remote streaming. Effortlessly handles multi-stream 4K/8K hardware transcoding for Plex or Jellyfin, delivering ultra-smooth playback to any device anywhere in the world.
- Enterprise Privacy with Flexible Sharing: Combines local hardware security with smooth cloud-like accessibility. Easily manage secure user permissions, automatic backups, and seamless cross-platform file sharing for your business.
What Magnitude’s published benchmarks show
The figures below are Magnitude’s own reported comparisons with llama.cpp. Its product page names the model configuration and two hardware setups, but does not display a benchmark year or fully detail every methodology point in the retrieved material. No independent replication is provided there, so these numbers should be read as vendor-reported results for the listed configurations—not universal performance guarantees.
What’s actually slowing this PC down?
Pick the symptom - the matching free tool is one click away.
| Hardware and model setup | Prefill reported by Magnitude | Decode reported by Magnitude |
|---|---|---|
| Metal Mac M4 Pro, 48 GB; Qwen 3.6 35B A3B, 4-bit, 64k context, no speculative decoding | Magnitude reports 466 → 507 tok/s, or 9% faster than llama.cpp; benchmark year not stated. | Magnitude reports 30 → 57 tok/s, or 92% faster than llama.cpp; benchmark year not stated. |
| CUDA DGX Spark; Qwen 3.6 35B A3B, 4-bit, 64k context, no speculative decoding | Magnitude reports 2,033 → 2,507 tok/s, or 23% faster than llama.cpp; benchmark year not stated. | Magnitude reports 49 → 58 tok/s, or 19% faster than llama.cpp; benchmark year not stated. |
Prefill is the work of processing the prompt; decode is the generation of subsequent tokens. The distinction matters because an engine can perform differently on those two stages. Magnitude’s “up to 2x faster than llama.cpp” headline summarizes its displayed tests; it should not be generalized to every model, computer, context length, or generation setting. The figures above are published on Magnitude’s product page.
To judge performance for your own workload, compare engines using the same model and quantization, context length, hardware, and decoding settings. Record prefill and decode separately, and check whether the test includes features such as speculative decoding. The cited pages do not provide a complete independent side-by-side evaluation of Magnitude, llama.cpp, Ollama, and LM Studio.
How to get started and connect an agent
- Install the Magnitude app. The README describes an initial desktop-app setup; the CLI is included with the app.
- Choose a model. In the app, open Discover, select a model, and download it.
- Connect an agent. Open Connections and choose a listed one-click integration, or connect another client through Magnitude’s OpenAI-compatible API.
The product page and README list one-click connections for Pi, OpenCode, Hermes, OpenClaw, Codex, Claude Code, Oh My Pi, and Cline. Integrations can change, so consult the current README for the up-to-date list and instructions.
Rank #4

- Next-Gen Processing Power: Powered by the AMD Ryzen 7 8845HS processor (8 Cores, 16 Threads, Zen 4 architecture) and Radeon 780M graphics. Effortlessly handles fluid 4K/8K real-time media transcoding, multiple operating system virtualizations (PVE/ESXi), and simultaneous background tasks without a stutter.
- Secure Local AI & Privacy: Features an integrated Ryzen AI NPU delivering up to 38 TOPS of total processing power. Deploy 8B/14B Large Language Models (LLM) locally, run automated programming assistants, and enjoy lightning-fast AI photo recognition—all completely offline, keeping your sensitive data 100% secure.
- Pro-Studio Collaboration: Engineered with dual 2.5GbE network ports and optimized high-speed architecture. Eliminate transmission bottlenecks so multiple video editors, photographers, or 3D designers can collaborate, render, and share heavy assets directly from the NAS in real time.
- Massive Docker Ecosystem: Seamlessly deploy and run over 20+ Docker containers simultaneously. Perfect for hosting your home assistant, private web servers, automated downloaders, and personal databases with enterprise-level stability.
- Futuristic Heat Dissipation: Designed with an advanced cooling system tailored for continuous, high-load hardware operation. Enjoy high-speed read and write speeds across multiple drive bays while maintaining whisper-quiet operation in your home or studio.
Hardware and operating-system support
Magnitude states that it supports macOS, Linux, and Windows, and lists Apple Silicon, NVIDIA, AMD, and CPU hardware. Its FAQ gives no fixed minimum hardware requirement. Instead, it says the model size a machine can run depends in part on available memory: machines with less memory can run smaller models, while more memory can allow larger ones. The sources do not specify a universal minimum memory figure or guarantee that every model works on every listed device.
Recommended Free Tools
What Magnitude says about privacy and offline use
Magnitude says prompts, files, and models stay on the user’s machine, and that an internet connection is unnecessary once a model has been downloaded. These are vendor claims about the product’s privacy and local operation, not the result of an independent security audit. Readers with strict data-handling requirements should assess the software and its configuration against their own policies.
What the public account does—and does not—establish
The available public materials establish Magnitude’s intended workflow, stated platform support, high-level device-specific kernel-compilation and tuning claim, and vendor-published benchmark results. They do not document the detailed engineering process implied by a full “how we built it” account. Without technical documentation or a source-code analysis, claims about the engine’s internal architecture or exact optimization methods would go beyond what these sources show.
Quick Recap
Product prices and availability are accurate as of the date/time indicated and are subject to change. Any price and availability information displayed on Amazon at the time of purchase will apply.

