
iTechGuides is reader-supported. When you buy through links on our site, we may earn an affiliate commission. As an Amazon Associate I earn from qualifying purchases. Learn more
An 8GB graphics card can sometimes run a model whose weights exceed its video memory, but that does not mean the whole model runs on the GPU—or that generation will be fast. The practical route is to use a quantized model in a runtime that supports your GPU, keep the context length realistic, tune cache settings only when needed, and verify where the work is placed.
The exact result depends on the GPU, model, quantization, runtime backend, system RAM, and workload. The available documentation explains the mechanisms, but it does not establish a reproducible flagship-model setup or speed for an unspecified 8GB card.
Why an 8GB GPU can run a model larger than 8GB
Model weights are only one part of inference memory. Context length and the key/value (KV) cache also use memory, and runtime overhead matters too. If all model weights do not fit in VRAM, some runtimes can place work across GPU and CPU memory instead of requiring the entire model to reside on the graphics card.
The llama.cpp project documents integer quantization from 1.5-bit through 8-bit and CPU+GPU hybrid inference. Quantization reduces the memory needed for model weights; hybrid inference can let a model run when it exceeds available VRAM. Neither capability guarantees a particular model will fit comfortably, generate quickly, or retain the quality of a higher-precision version.
#1 Best Overall
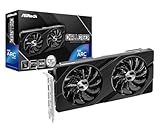
- Next-Gen Intel Arc Graphics: Powered by Intel Arc A580 GPU with Intel Xe HPG microarchitecture, featuring 384 XMX engines for enhanced AI acceleration and content creation.
- High-Performance Memory: 8GB GDDR6 on a 256-bit interface running at 16 Gbps, delivering excellent bandwidth for 1440p gaming and creative workloads.
- Factory Overclocked: Engine clock set at 2000 MHz out of the box, providing optimized performance for smooth gameplay and multimedia tasks.
- Advanced Dual-Fan Cooling: Features a dual-fan design with striped axial fans and an ultra-fit heatpipe for efficient thermal management. 0dB Silent Cooling stops fans completely at low temperatures for silent operation.
- Durable Construction: Includes a stylish metal backplate for enhanced PCB rigidity and a premium aesthetic, backed by ASRock's Super Alloy components for long-term reliability.
Think of “runs” as three separate tests: the model loads, it generates at a speed you can use, and its output remains good enough for your task. A successful launch proves only the first.
Set up the workflow in the right order
-
Choose a model and quantization
Use a model file and quantization supported by your chosen runtime and hardware backend. Lower-precision weights reduce memory requirements, but the quality tradeoff depends on the model and task; the cited documentation does not establish a universal quality ranking or exact loss for a specific model. Start with a quantized version, then judge its answers on the work you actually need it to do.
Rank #2
Sale GIGABYTE GeForce RTX 5060 WINDFORCE OC 8G Graphics Card, Cooling System, 8GB 128-bit GDDR7, PCIe 5.0, Manufactured by NVIDIA, DisplayPort & HDMI - Video Output Interface, GV-N5060WF2OC-8GD Video Card
- Powered by the NVIDIA Blackwell architecture and DLSS 4
- Powered by GeForce RTX 5060
- Integrated with 8GB GDDR7 128bit memory interface
- PCIe 5.0
- WINDFORCE cooling system
-
Use a runtime with a compatible GPU backend
llama.cpp supports multiple hardware backends and hybrid CPU/GPU inference. Confirm that your installation was built for the backend your GPU needs; choosing a model alone does not ensure GPU acceleration. Its README includes command-line and server examples, but those examples—including its small sample model—do not demonstrate that an unspecified flagship model will work on an 8GB card.
Quick wins for a faster PC:
Repair Windows errors before they cause bigger problemsFix Now →Fix the driver behind crashes, sound loss and screen glitchesFind Drivers →Special offer. See more information about Outbyte and uninstall instructions. Please review EULA and Privacy policy. -
Begin with a realistic context length
Context is the amount of prompt and conversation the model can consider at once. A larger context can increase KV-cache memory use, so avoid setting it higher than your task needs. Ollama’s FAQ lists 4096 tokens as the default context and describes how to change it. That is a default, not a guarantee that every model and 8GB GPU can use that context without memory pressure.
Rank #3
 ASRock Radeon RX 7600 Challenger Pro 8GB OC, AMD RDNA 3, 8GB GDDR6, PCIe 4.0, Triple Fans, 0dB Silent, 2695MHz Boost, Triple Fan Graphics Card
- System Compatibility Note: 2.5‑slot card measuring 303 mm (L) x 131 mm (W) x 45 mm (H); requires a single 8‑pin power connector and a recommended 550W power supply. Please verify chassis clearance and power supply capacity before purchase.
- Dedicated Support: Please contact us directly through Amazon for any product questions or assistance you may require.
- AMD RDNA 3 Architecture with AI & Ray Tracing Acceleration: Powered by 32 RDNA 3 Compute Units featuring 3rd Gen Ray Tracing Accelerators and 2nd Gen AI Accelerators, delivering lifelike lighting, shadows, and superior machine learning performance for enhanced gaming and content creation.
- Powerful 1080p & 1440p Gaming Engine: Features a max boost clock of up to 2695 MHz, a game clock of 2280 MHz, and 2048 stream processors, ensuring outstanding frame rates in the latest titles.
- 8GB High‑Speed GDDR6 Memory: Equipped with 8GB of GDDR6 memory on a 128‑bit interface running at 18 Gbps, delivering up to 288 GB/s bandwidth for high‑resolution textures and demanding game workloads.
-
Tune KV cache or Flash Attention only if the memory budget calls for it
Ollama documents Flash Attention as a way to reduce memory use as context grows. It can be enabled or disabled with an environment variable when the selected backend and devices support it. Cache quantization is another option: according to the Ollama FAQ, q8_0 uses approximately half the memory of f16, while q4_0 uses approximately one quarter. These are KV-cache memory comparisons—not model-weight sizes or speed results.
Ollama describes q8_0 as having very small precision loss and q4_0 as having small-to-medium precision loss, potentially more noticeable at higher context sizes. The impact varies by model and task; Ollama specifically cautions that models with a high grouped-query attention (GQA) count may see more precision impact. Change one setting at a time and check whether the memory savings are worth any output change for your use.
Rank #4
 MOUGOL AMD Radeon RX 580 8GB GDDR5 Gaming Graphics Card, HDMI/DP/DVI White
- 【Ultimate Triple Display Connectivity】: Features a versatile output array including HDMI, DisplayPort (DP), and DVI. Whether you're connecting a high-refresh-rate gaming monitor via DP or a standard office screen via HDMI, this card supports triple-monitor setups for maximum productivity.
- 【Compact Size & Wide Compatibility】: Measuring 240x135x45mm (9.45x5.31x1.77 inches), this dual-fan RX 580 fits perfectly into standard ATX Mid-Towers, Micro-ATX (M-ATX), ideal for compact desktop PC upgrades and space-saving gaming builds.
- 【Optimized Gaming Performance】: With 2048 Stream Processors and a 1206 MHz core clock, this card delivers solid frame rates in popular titles like Fortnite, GTA V, Apex Legends, and Valorant. It’s the ideal budget-friendly GPU for entry-level to mid-range gaming rigs.
- 【Advanced Thermal Management】: Engineered with a dual-fan cooling system and high-efficiency heat pipes to ensure stable performance under heavy loads. The intelligent fan control keeps your system quiet during light office work and provides maximum airflow during intense gaming sessions.
- 【Ready for Content Creation】: Supports DirectX 12, Vulkan, and OpenGL 4.6, making it more than just a gaming card. It provides hardware acceleration for video editing in Premiere Pro, 3D rendering in Blender, and smooth streaming for aspiring creators.
-
Check placement, then test the actual task
With Ollama, run
ollama psand inspect the Processor column to see how the model is placed. A model that loads successfully may still rely substantially on CPU work; do not infer GPU utilization from the launch alone. Then test representative prompts and note the model, quantization, context setting, runtime and backend, system RAM, and observed generation speed. Without those details, a claim that a flagship model “works” cannot tell another reader whether it will be usable on their machine.Free tools Windows power users keep installed
One-click scans. No signup required.
Special offer. See more information about Outbyte and uninstall instructions. Please review EULA and Privacy policy.
Choose settings by the constraint you are trying to relieve
| Constraint | Setting to consider | Tradeoff or check |
|---|---|---|
| Model weights exceed VRAM | Lower-bit model quantization; CPU+GPU hybrid inference | Quantization can affect task quality; hybrid placement can change performance. The cited documentation does not quantify the speed cost for a particular setup. |
| Context causes memory pressure | Reduce context to what the task needs; consider Flash Attention where supported | Less context limits how much prompt or conversation the model can use. Flash Attention support depends on the backend and devices. |
| KV cache consumes too much memory | Consider q8_0 or q4_0 KV-cache quantization | Ollama’s approximate memory ratios compare cache formats with f16; precision effects vary, and q4_0’s impact may be more noticeable at higher context sizes. |
| Model loads, but GPU contribution is unclear | Check Ollama’s ollama ps Processor column |
Placement indicates where work is assigned; it is not by itself a generation-speed benchmark. |
What system RAM can—and cannot—do
On Linux, the llama.cpp build guide documents the GGML_CUDA_ENABLE_UNIFIED_MEMORY=1 option, which allows swapping to system RAM when VRAM is exhausted. This is a runtime/build option, not a promise of acceptable latency. More host-memory involvement may let a workload proceed, but whether the resulting generation speed is usable has to be measured on the particular machine.
Best Value

- Not compatible with all built-in computers or systems
- AMD Radeon RX 6600 GPU: Built on RDNA 2 architecture, delivering excellent 1080p gaming performance with high efficiency.
- 8GB GDDR6 Memory: Provides smooth gameplay and multitasking with fast data transfer rates.
- Challenger D Cooling: Features a dual-fan design for effective heat dissipation and quiet operation.
- PCIe 4.0 Support: Ensures high bandwidth for improved gaming and productivity performance.
Memory needs can also rise when serving multiple requests. Ollama notes that parallel requests increase memory requirements with request count and context length. A single-user test therefore does not establish that the same setup can handle concurrent users or larger contexts.
What counts as a successful result
- It loads: The model starts and produces output. This says nothing by itself about speed or output quality.
- It is usable: Generation speed is acceptable for your task under the exact context and workload you intend to use. Record the configuration and measure it rather than assuming from VRAM capacity.
- It meets your quality bar: The quantized model and any cache settings produce acceptable answers on representative prompts. Compare outputs for your task; no general quality result is established for an unspecified model and GPU.
For a reproducible claim, report the exact GPU, model and quantization, runtime version and backend, system RAM, context setting, cache options, and measured speed. Without them, “flagship LLM on 8GB” describes a possibility enabled by memory-saving and hybrid-inference techniques, not a result other owners can rely on.
Quick Recap
Product prices and availability are accurate as of the date/time indicated and are subject to change. Any price and availability information displayed on Amazon at the time of purchase will apply.
The Tool Desk
Outbyte Driver Updater FREEScan for outdated or missing drivers - takes under a minuteDriver Scan →Outbyte PC Repair FREEClear out junk files and repair common Windows errorsFree Scan →
