
Quick wins for a faster PC:
Scan for outdated or missing drivers - takes under a minuteDriver Scan →Clear out junk files and repair common Windows errorsFree Scan →There is no documented turnkey stack that takes a quantized diffusion model, runs its complete graph through Android Vulkan, and delivers real-time texture synthesis. The practical route is a compatibility and benchmarking project: LiteRT offers an Android GPU path that is not established as Vulkan, while ExecuTorch offers an Android-focused Vulkan backend whose documented quantized coverage is currently limited. Treat operator coverage, graph partitioning, and device measurements as release gates rather than assuming that “GPU accelerated” means “Vulkan.”
What is actually feasible today?
Two separate integration paths are relevant, and they should not be conflated.
| Runtime and backend | Android graphics path | Quantized behavior documented | What is not established |
|---|---|---|---|
| LiteRT GPU delegate | Google’s Android GPU route, with GLES-oriented setup and GPU-friendly buffers | For supported 8-bit models, weights and biases are dequantized into GPU memory; quantized inputs and outputs can be converted around inference; simulators preserve activation ranges | That this route executes through Android Vulkan, or that a complete diffusion graph stays on the GPU |
| ExecuTorch Vulkan backend | Vulkan backend developed with an Android GPU focus; distributed through executorch-android-vulkan |
Quantized linear layers are documented as supported; additional quantized operators and modes are still being developed | End-to-end support for an arbitrary quantized diffusion denoiser, or real-time texture synthesis on a named phone |
LiteRT’s documentation warns that unsupported operations may run on the CPU while supported sections use the GPU. Synchronization between those devices can make a split graph slower than CPU-only execution. ExecuTorch’s Vulkan documentation similarly requires checking the exact graph against the backend and partitioner in the release you ship.
Why a diffusion model needs a graph audit
Inventory every operation
A diffusion pipeline is a sequence of tensor operations, not a single kernel. Record every operator, tensor shape, layout, data type, quantization scale and zero point, reshape, normalization, activation, attention block, sampler step, decoder stage, and post-processing conversion. Then compare that inventory with the selected backend’s supported operators for the exact runtime version.
#1 Best Overall

- 【Strong Adsorption】The inspiration of the silicone phone suction case comes from the adhesive force of the octopus. Each suction cup phone mount is 3.15 inches long and 2.17 inches wide, with 24 independent suction cups providing a stronger and more stable suction force, so you don't have to worry about your phone falling during use.
- 【Back of Phone Suction Grip】Remove the adhesive film on the phone suction cup and stick it on the phone case. You can then fix the phone on any smooth surface, which is very convenient. (The phone suction cup cannot be removed and reused after being attached to the phone case. It is recommended to attach it to a regular phone case, not a valuable one.)
- 【Widely Used】Our non-slip silicone phone sticky grip mount attaches to almost any flat phone case and make it compatible with common mobile phones such as iPhone and Android.You can shoot, watch videos or video calls in the kitchen, gym, dance studio, bathroom and other places.
- 【Capture the Wonderful Picture】Whether you are a TikTok creator or just like to share videos and photos, this phone suction cup can help you hands-free capture wonderful videos and photos for sharing with friends.
- 【Note】You can fix the phone suction cup on a smooth surface such as a mirror or glass. If necessary, wipe the suction cup with a damp cloth to obtain stronger suction. Before releasing your hand, make sure the phone is firmly fixed. (Not applicable to rough walls, wooden surfaces, and other uneven surfaces)
Check partitioning before optimizing
A delegate accepting a model does not prove that the whole graph executes on the GPU. Export a test graph, inspect which nodes are assigned to Vulkan (or to the LiteRT GPU delegate), and identify every CPU fallback. Measure the transfers and synchronization at each boundary. A few unsupported operations inside every denoising iteration can dominate total latency.
Separate model compatibility from renderer interoperation
Running inference with a Vulkan backend and displaying the result as a game or engine texture are separate problems. Define how the output tensor becomes an image, how it is uploaded or shared with the renderer, and where layout transitions and synchronization occur. The available documentation does not establish a ready-made texture-renderer/Vulkan interoperation path for this proposed pipeline, so validate it on the target graphics stack.
Rank #2

- SUPERIOR COMFORT — Unlike traditional circular ear buds, the design of EarPods is defined by the geometry of the ear. Which makes them more comfortable for more people than any other ear bud–style headphones.
- HIGH-QUALITY AUDIO — The speakers inside EarPods have been engineered to maximize sound output and minimize sound loss, which means you get high-quality audio.
- BUILT-IN REMOTE — EarPods with USB-C plug also include a built-in remote that lets you adjust the volume, control the playback of music and video, and answer or end calls with a pinch of the cord.
- COMPATIBILITY — Works with all devices that have a USB-C port.
- INTEGRATED MICROPHONE — A built-in microphone precisely captures your voice while you’re on the phone, taking a FaceTime call, or summoning Siri — so you’re always heard loud and clear.
How quantization behaves on each route
LiteRT’s GPU treatment of 8-bit models
LiteRT describes a floating-point view of supported quantized models on the GPU. Constant tensors such as weights and biases are dequantized when the delegate is enabled. Quantized input and output tensors may be converted on the CPU for each invocation, and quantization simulators are inserted between operations to retain learned activation bounds. The documentation recommends floating-point model inputs and outputs when performance is the priority.
That behavior can reduce the memory benefit you expected from an integer model and can add per-inference conversion work. Use GPU-resident, GPU-friendly buffers where the API permits, but verify whether your particular input and output path still performs copies.
Rank #3

- Secure Hold: Our PopSockets adhesive phone grip gives your cell phone a secure, comfortable hold in hand to help prevent drops while texting, taking photos, or scrolling on the go. Designed to stick firmly to most phone cases and devices.
- Hands-Free Made Easy: Easily turn your PopSocket into a phone stand to prop up your phone anywhere, perfect for watching videos, video calls, or following recipes. A must-have phone holder that keeps your device secure and ready for anything.
- Compatibility: Works with all phones, tablets, and Kindles. Sticks best to smooth, hard plastic cases and may not adhere to silicone or textured cases. Easily swap your PopTop to change up your style.
- Black PopSockets: Simple, refined, and endlessly versatile. A timeless essential for any phone.
- Travel Must-Have for People On the Go: A must-have travel accessory for flights, flying, airports, air travel, airplanes, planes, international trips, cruises, and long travel days. Key gadget for your airport haul, travel accessories and must-haves.
ExecuTorch Vulkan coverage
The official ExecuTorch Vulkan overview identifies quantized linear layers as supported and says more quantized operators and modes are in progress. Diffusion models contain substantially more than linear layers, so a successful export requires an operator-by-operator compatibility result. Do not describe the model as Vulkan-supported until the complete denoiser, scheduler-related math, decoder, and conversions have been tested with the release you intend to distribute.
A practical integration workflow
- Define the output contract. Decide whether one request produces a single tile, a sequence of progressively refined texture updates, or a continuously changing texture. Record resolution, color format, tile overlap, conditioning inputs, denoising-step budget, and the maximum acceptable latency.
- Freeze a reproducible model. Record the model version, export format, calibration data, quantization scheme, tensor layouts, and whether the text or other conditioning encoder is on-device. Keep the denoiser and decoder versions tied to the same test package.
- Create an operator and shape inventory. Enumerate the full graph, including preprocessing, conditioning, denoising iterations, decoding, and output conversion. Mark each node’s precision and dynamic-shape requirements.
- Select the backend deliberately. Choose LiteRT only when its GPU delegate and GLES-oriented Android path meet your requirements. Choose ExecuTorch Vulkan when Vulkan execution is a hard requirement and the graph passes its documented and release-specific operator checks. Installing
executorch-android-vulkanalone does not establish model compatibility. - Run a partition test. Export a small representative graph first, then the complete pipeline. Capture delegated nodes, CPU fallbacks, tensor copies, and synchronization points. Reject a design whose fallback pattern repeats inside every denoising step unless measurements show it is still acceptable.
- Validate numerical fidelity. Compare dequantized and quantized outputs against a reference implementation at each stage. Check activation ranges, clipping, color conversion, tile seams, and output stability across multiple seeds. A visually plausible image is not sufficient if errors accumulate over iterative denoising.
- Integrate the output with the renderer. Measure tensor-to-texture conversion, image layout transitions, synchronization, and texture upload or sharing separately from neural-network execution. Keep the output contract explicit so a “frame” is not confused with a completed image.
- Measure cold and warm runs. Include model loading, graph compilation or delegate initialization, conditioning work, every denoising iteration, decoding, output conversion, texture delivery, and frame presentation. Repeat long enough to expose thermal throttling.
What counts as real-time?
“Real-time” must be a workload definition, not a label attached to a kernel time. For a generated tile, specify the time from request to usable texture. For progressive output, specify update interval, time to first update, and time to final quality. For a continuously evolving texture, specify a sustained frame rate and the quality permitted at that rate.
Rank #4

- [360 ° Flexible Rotation Design] Comes with a rotatable lanyard ring that supports 360 ° free rotation, effectively solving the problem of twisted and tangled lanyards
- [Wide compatibility] The ultra-thin 0.02-inch design does not block the charging port at all, and both wired and wireless charging can be used directly without removing the pad. Compatible with most smartphones such as iPhone, compatible with various wristbands, lanyards, crossbody straps, and keychains
- [Durable and Portable Material] Premium rust-resistant stainless steel material with good flexibility, which not only avoids scratching the phone case, but also has excellent anti rust and anti fading performance
- [Multi scenario Practical] Paired with a lanyard or wristband, hands-free use can be achieved. The phone is within reach and not easily dropped, ideal for daily commuting and outdoor activities. Suitable for full coverage phone cases, does not support half coverage phone cases
- [Quality Service] If you find any damage or other issues with the product upon receipt, please contact us immediately. We will handle it quickly
The clearest published Android reference in the available material is Choi et al.’s 2023 ICML Workshop paper, Squeezing Large-Scale Diffusion Models for Mobile, which reports Mobile Stable Diffusion latency of less than seven seconds for one 512×512 image on Android devices with mobile GPUs. That is a 2023 research result, not a Vulkan-specific measurement, a current-phone guarantee, or evidence of interactive texture synthesis.
Benchmark protocol for a credible implementation
- Name the Android device, GPU vendor, operating-system version, runtime and backend release, model version, quantization format, image or tile dimensions, conditioning path, and denoising-step count.
- Report cold-start and warm-start latency separately, including model load and delegate or Vulkan initialization.
- Break out denoising, decoder, preprocessing, output conversion, texture upload, synchronization, and presentation times.
- Record operator partitioning, fallback count, peak memory, and intermediate buffer sizes.
- Run sustained workloads and report thermal behavior, throttling, power draw when available, and latency variance rather than a single best result.
- Compare candidate backends on identical devices and workload definitions; otherwise the numbers are not comparable.
Common failure modes and recovery choices
| Symptom | Likely cause | Next action |
|---|---|---|
| The model loads, but latency is worse than CPU execution | Frequent CPU/GPU partitioning and synchronization | Inspect delegated nodes and move or replace unsupported operations; benchmark the complete graph, not isolated kernels |
| Memory use is higher than expected for an 8-bit model | Weights are dequantized for GPU execution or conversion buffers are duplicated | Measure peak GPU and CPU memory, then test floating-point I/O and buffer reuse separately |
| ExecuTorch export succeeds but Vulkan execution fails | The graph uses quantized operators beyond the backend’s documented linear-layer support or relies on an unsupported mode | Reduce the graph to a failing operator set, verify the exact release, and revise quantization or partitioning |
| Inference is fast but texture updates miss the frame budget | Output conversion, synchronization, or texture upload dominates | Profile tensor-to-texture delivery and validate a compatible sharing or staging strategy on the target device |
| First-use latency is unacceptable | Model loading, compilation, or delegate initialization is included in the user-visible path | Measure initialization explicitly and decide whether safe prewarming or cached compilation is available for the deployment |
| Performance degrades during a long session | Mobile GPU thermal throttling | Use sustained tests, reduce denoising work or resolution, and publish thermally stable rather than peak numbers |
Decision criteria before committing to Vulkan
- Full-graph coverage: The chosen backend handles the denoiser, decoder, and conversions without costly repeated fallbacks.
- Quantization fidelity: Calibration and activation ranges preserve acceptable texture quality across seeds and content.
- End-to-end latency: The defined texture workload meets its target after initialization, synchronization, and delivery costs.
- Memory headroom: Peak allocations fit the weakest supported device, including renderer resources.
- Sustained behavior: Thermal throttling does not invalidate the promised update rate.
- Portability: The result is repeatable across the GPU vendors and Android versions you plan to support.
- Maintenance cost: Backend operator coverage and quantization modes are stable enough for your release schedule.
If any of these gates fails, a hybrid design may be more practical: keep unsupported stages on the CPU, use a different runtime, reduce resolution or denoising steps, or generate tiles asynchronously instead of promising a synchronous real-time frame.
Do these 3 things before closing this tab:
1Scan for outdated or missing drivers - takes under a minute2Repair Windows errors before they cause bigger problems3Fix the driver behind crashes, sound loss and screen glitchesQuick Recap
Best Value
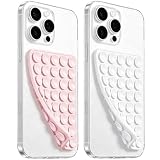
- 【PKYAA Double Sided Silicone Suction Phone Case Mount】PKYAA With Double Sided 40 Strong and Reliable individual suction cups, PKYAA provides a thicken and upgraded universal silicon suction mount for your phone.
- 【Friendly to Content Creators】If you are a content creator or an online influencer, you can create videos anywhere with this suction mount completely hands free with this silicone cell phone mount for cases.
- 【HANDS-FREE & Adhere to Mirrors】This Double Sided silicone suction phone case mount allows you to stick your phone to the mirror easily. No longer holding your phone in one hand to watch video tutorials while making up.
- 【Strong Grip on the Smooth Surface】You can easily hang your phone anywhere with a smooth surface. All you do is you clean off your phone and smooth surface. It is STURDY and it not only sticks to mirrors, it also sticks to windows, it sticks to refrigerators, tiles and other clean, flat surfaces.
- 【Press Down Firmly Every 30 Minutes】Use your palm or fingers to press the phone down firmly and check it's secure before letting go. Apply even pressure for a few seconds to allow the suction cup to adhere properly. To maintain the grip and prevent accidental falls, it's a good practice to periodically reapply pressure to the suction cup.
Product prices and availability are accurate as of the date/time indicated and are subject to change. Any price and availability information displayed on Amazon at the time of purchase will apply.

