
Free tools Windows power users keep installed
One-click scans. No signup required.
A GPU-driven rendering pipeline moves per-object decisions—visibility, level-of-detail selection, command generation, and sometimes work scheduling—from CPU loops into GPU workloads. The CPU still manages resources, frame data, synchronization, and high-level scene changes; the goal is to reduce per-object submission overhead, not eliminate the CPU.
The most portable starting point is GPU-resident scene data, compute culling, GPU-generated indirect arguments, a correct compute-to-indirect barrier, and indirect drawing. Mesh shaders and work graphs extend this model but are optional and feature-dependent.
What problem does GPU-driven rendering solve?
A conventional renderer can test visibility, select an LOD, bind resources, record a draw, and repeat for every object. Thousands of small meshes and several views—depth, shadows, reflections, and color—can make CPU submission and command recording the frame bottleneck even when the GPU has capacity.
GPU-driven rendering changes the dataflow. Compute shaders inspect scene buffers, reject or classify work, and write command arguments that later draw or dispatch commands consume. The work is moved, not removed: CPU culling becomes GPU compute, binding becomes indexed lookup, and object loops become shader invocations.
#1 Best Overall

- Powered by Radeon RX 9070 XT
- WINDFORCE Cooling System
- Hawk Fan
- Server-grade Thermal Conductive Gel
- RGB Lighting
Vulkan’s multi-draw example shows GPU culling, generated indirect commands, and indexed resource access as a way to reduce CPU command-generation and binding overhead (Vulkan multi-draw indirect sample).
CPU-driven and GPU-driven frame flow
Conventional flow
CPU: update camera → iterate objects → cull → bind → record draw
GPU: execute recorded draws
Basic GPU-driven flow
CPU: update frame constants → dispatch culling → synchronize → issue indirect draw
GPU: read scene data → cull and select LOD → write arguments → execute draws
Advanced flow
instance culling → Hi-Z occlusion → LOD selection
→ meshlet/cluster culling → compaction and sorting
→ depth, shadow, visibility, and color passes
The same approach can generate indirect dispatch arguments for later compute work, not just draw commands (Vulkan GPU-side command generation tutorial).
Canonical pipeline architecture
- GPU scene data: Store transforms, bounds, mesh metadata, material IDs, LOD thresholds, and visibility history in buffers.
- Compute filtering: Run frustum, distance, LOD, occlusion, or cluster tests.
- Command generation: Write fixed-slot or compacted indirect draw/dispatch records and counters.
- Synchronization: Make shader writes visible to indirect-command reads.
- Execution: Submit indirect draws or dispatches with no CPU loop over visible objects.
- Resource lookup: Resolve materials and textures through descriptor indexing or equivalent bindless access.
Typical GPU data
- Object transforms and previous-frame transforms
- Bounding spheres or AABBs
- Mesh, submesh, and material metadata
- Texture indices and LOD thresholds
- Indirect arguments, counters, visible IDs, and occlusion results
- Meshlet bounds and cone data
What remains CPU-managed
- Resource creation, destruction, streaming, and pipeline compilation
- High-level scene changes and frame pacing
- Command-buffer submission, fences, and capability selection
- Debug tooling and exceptional work
Use separate per-frame or ring-buffered resources so the CPU does not overwrite data still in use by the GPU.
GPU culling stages
Frustum culling
Test a sphere or AABB against the camera frustum. It is inexpensive, predictable, and supported on broad hardware, but object-level bounds can be conservative and it cannot reject hidden geometry.
Recommended Free Tools
Distance and screen-size tests
Reject objects below a projected-size threshold or choose an LOD from distance and screen coverage. Thresholds must account for resolution, field of view, and projection; a value tuned for 1080p can be wrong at 4K or with a wide lens.
Occlusion culling
A hierarchical-Z depth representation can reject objects hidden by previously rendered opaque geometry. A previous-frame depth pyramid avoids a stall but introduces latency, so use conservative tests and hysteresis to prevent popping. Transparent geometry and alpha-tested foliage generally need separate handling.
Rank #2

- Powered by the NVIDIA Blackwell architecture and DLSS 4
- Powered by GeForce RTX 5070 Ti
- Integrated with 16GB GDDR7 256bit memory interface
- PCIe 5.0
- WINDFORCE cooling system
Hierarchical and meshlet culling
Rejecting a world cell or cluster before its children reduces work. Meshlets add fine-grained bounds, cone tests, and screen-size decisions. They require preprocessing and more metadata, so add them only when object-level culling leaves measurable GPU work.
Generating indirect commands
Fixed command array
Give each candidate a command slot and set instanceCount to zero when it is invisible.
Do these 3 things before closing this tab:
1Fix the driver behind crashes, sound loss and screen glitches2Clear out junk files and repair common Windows errors3Scan for outdated or missing drivers - takes under a minute- Pros: simple indexing, stable correspondence, straightforward debugging.
- Cons: inactive slots consume command capacity and may still incur processing overhead.
Compacted visible list
For each visible object, atomically append an ID and command, or use a prefix-sum scan. Execute with an indirect-count command where available, or copy the count into a fixed command structure.
- Pros: fewer commands when visibility is sparse and easier per-pass lists.
- Cons: counters, scans, barriers, overflow handling, and potentially nondeterministic ordering.
Reset append counters before every culling pass. Define overflow behavior—clamp, drop excess entries, set a diagnostic flag, or choose a larger buffer next frame—before shipping.
Minimal implementation shape
// CPU
UploadCameraConstants();
ResetCounters();
Dispatch(cullingPipeline, (objectCount + THREADS_PER_GROUP - 1) / THREADS_PER_GROUP);

// Synchronize storage/UAV writes before indirect reads
InsertComputeToIndirectBarrier();

// GPU consumes generated work
DrawIndexedIndirectCount(indirectArgsBuffer, drawCountBuffer, maxDrawCount);
A production implementation also validates bounds and metadata, handles zero visible objects, allocates per-frame buffers, and provides readback diagnostics.
Synchronization is part of correctness
The culling pass writes an argument or count buffer; a later pass reads it as an indirect source. Without an explicit dependency, draws can use stale data or race with the compute pass.
Rank #3

- AI Performance: 767 AI TOPS
- OC mode: 2632 MHz (OC mode)/ 2602 MHz (Default mode)
- Powered by the NVIDIA Blackwell architecture and DLSS 4
- Axial-tech fan design features a smaller fan hub that facilitates longer blades and a barrier ring that increases downward air pressure
- A 2.5-slot design maximizes compatibility and cooling efficiency for superior performance in small chassis
Vulkan
Use appropriate pipeline barriers or synchronization2 dependencies for shader-write to indirect-command-read visibility. Buffers need matching storage and indirect usage flags. If compute and graphics use different queues, add queue-ownership and semaphore synchronization. Count buffers require the same treatment.
Direct3D 12
Track resource states and insert UAV ordering where a compute UAV write is followed by indirect execution. Fence and queue selection must prevent per-frame resources from wrapping while still in use.
Common symptoms
- Stale commands from the previous frame: missing or incorrect barrier.
- Intermittent counts: counter reset or queue dependency race.
- GPU hang: out-of-bounds append, invalid argument, or descriptor index.
- CPU overwrite: frame-resource ring is shorter than GPU latency.
Bindless materials and resource indexing
GPU-generated object IDs are most useful when shaders can resolve resources without a CPU descriptor update for every draw:
Material m = materials[draw.materialID];
Texture2D baseColor = textures[m.baseColorIndex];
Descriptor indexing, unbounded arrays, or large descriptor heaps reduce repeated binding operations (Vulkan indexed-resource example). They do not remove residency, lifetime, indirection, or cache costs. Thousands of unrelated texture accesses can be less cache-friendly than a smaller, well-sorted set.
What’s actually slowing this PC down?
Pick the symptom - the matching free tool is one click away.
Sorting and batching generated work
Visibility alone does not guarantee efficient execution. Sort keys can include pipeline, material, texture set, mesh, LOD, depth, or shadow-caster class. Sorting may reduce state changes, cache misses, and overdraw, but GPU radix sorts and temporary buffers add passes, memory traffic, and synchronization. Start with a stable unsorted path, then measure whether sorting pays for itself.
Indirect draws, mesh shaders, and work graphs
Compute plus traditional indirect draws
This path reuses conventional vertex and index buffers and is usually the best first implementation. It has broad fallback value, although command granularity and material grouping can remain coarse.
Rank #4

- Powered by the NVIDIA Blackwell architecture and DLSS 4. System Requirements: Minimum 850W PSU with 16-pin 12V-2x6 (12VHPWR) connector required. Verify before purchasing.
- Military-grade components deliver rock-solid power and longer lifespan for ultimate durability. Compatibility: 348mm (13.7") length, 3.6 slots, 4.3 lbs. Confirm case clearance and slot spacing. GPU bracket included.
- Protective PCB coating helps protect against short circuits caused by moisture, dust, or debris
- 3.6-slot design with massive fin array optimized for airflow from three Axial-tech fans
- Phase-change GPU thermal pad helps ensure optimal thermal performance and longevity, outlasting traditional thermal paste for graphics cards under heavy loads
Task and mesh shaders
Task shaders can cull or amplify meshlet work; mesh shaders emit vertices and primitives directly. Vulkan documents their execution model in the shader specification and pipeline specification. Mesh shaders require supported hardware, meshlet preprocessing, and careful payload, occupancy, and workgroup tuning. They are not universally faster than vertex pipelines. NVIDIA’s architectural overview discusses meshlet culling but is hardware- and workload-dependent (NVIDIA mesh-shader introduction).
Device-generated commands and work graphs
Device-generated-command proposals and Direct3D 12 Work Graphs extend GPU-created work beyond a simple argument array. They are attractive for irregular, dependent, deeply amplified workloads, but feature checks, backing memory, debugging, and platform consistency matter. See the Vulkan device-generated-command proposal and NVIDIA’s Work Graphs discussion.
The Tool Desk
Outbyte PC Repair FREERepair Windows errors before they cause bigger problemsFix Now →Outbyte Driver Updater FREEScan for outdated or missing drivers - takes under a minuteDriver Scan →Performance: what to measure
Fewer CPU draws are not a performance proof. Record separate CPU render-thread time, culling compute time, graphics time, memory bandwidth, occupancy, synchronization gaps, candidate and visible counts, executed command count, and overdraw.
- If the GPU is already saturated, moving culling onto it can reduce frame rate.
- A global append atomic can contend; per-workgroup counts and hierarchical scans can scale better.
- Divergent object types and LOD rules reduce shader efficiency.
- Large metadata reads can make culling bandwidth-bound.
- Occlusion helps only when rejected geometry and overdraw exceed the depth-pyramid and test cost.
Failure modes and debugging
Incorrect visibility
Check clip-space conventions, frustum-plane extraction, transformed bounds, camera freshness, floating-point precision, and conservative occlusion. A previous-frame depth buffer must match the camera convention used by the test.
Missing objects
Inspect reversed LOD thresholds, truncated indirect counts, visible-list overflow, incomplete streaming, and descriptor indices. Render bounds and color-code rejection reasons.
Debug workflow
- Copy visible IDs and counters to a readback buffer.
- Disable culling stages one at a time.
- Replace indirect execution with a CPU-generated equivalent.
- Display candidate, visible, compacted, and executed counts.
- Flag overflow and invalid metadata in a diagnostic buffer.
Choosing an architecture
| Approach | Choose it when | Main cost or limitation |
|---|---|---|
| Conventional CPU renderer | Few large draws, simple content, or CPU-side debuggability is paramount | Per-object submission scales poorly |
| Multithreaded CPU recording | Worker threads can absorb moderate command-generation work and GPU compute is busy | Still pays CPU culling and binding costs |
| Compute culling plus indirect draws | Many objects, repeated views, and measurable CPU submission overhead | Requires synchronization, counters, and GPU memory traffic |
| Mesh shaders | Meshlet preprocessing and modern target hardware are acceptable | Feature availability and performance vary |
| Work graphs | GPU work is irregular, dependent, and difficult to express as fixed dispatch chains | Newer scheduling and debugging model |
| Hybrid | Opaque geometry is regular but UI, transparency, or rare objects are not | Maintains multiple rendering paths |
GPU-driven selection must also respect streaming and residency: a visible object needs a resident mesh, usable texture mips, and a fallback if data is unavailable. Animated characters may be culled by conservative bounds before visible instances are skinned.
Best Value
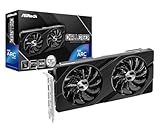
- Next-Gen Intel Arc Graphics: Powered by Intel Arc A580 GPU with Intel Xe HPG microarchitecture, featuring 384 XMX engines for enhanced AI acceleration and content creation.
- High-Performance Memory: 8GB GDDR6 on a 256-bit interface running at 16 Gbps, delivering excellent bandwidth for 1440p gaming and creative workloads.
- Factory Overclocked: Engine clock set at 2000 MHz out of the box, providing optimized performance for smooth gameplay and multimedia tasks.
- Advanced Dual-Fan Cooling: Features a dual-fan design with striped axial fans and an ultra-fit heatpipe for efficient thermal management. 0dB Silent Cooling stops fans completely at low temperatures for silent operation.
- Durable Construction: Includes a stylish metal backplate for enhanced PCB rigidity and a premium aesthetic, backed by ASRock's Super Alloy components for long-term reliability.
Practical adoption path
- Keep a CPU fallback and capability-based feature selection.
- Move object, bounds, mesh, and material metadata into persistent GPU buffers.
- Implement frustum culling and fixed indirect commands.
- Add compaction only after inactive-command overhead is measured.
- Add distance/LOD selection, then occlusion if overdraw justifies it.
- Introduce sorting, meshlets, mesh shaders, or work graphs only with workload-specific profiling.
For tools, RenderDoc (official site) is useful for captures and indirect-buffer inspection; NVIDIA Nsight Graphics (official site) provides NVIDIA-specific analysis; PIX (official site) targets Direct3D 12 and Microsoft platforms. None replaces cross-vendor measurement.
Frequently Asked Questions
Does GPU-driven rendering eliminate CPU work?
No. The CPU still manages resources, frame orchestration, synchronization, streaming, and exceptional objects; the architecture reduces repetitive per-object culling and submission.
Are mesh shaders required?
No. Compute culling with traditional indexed indirect draws is a complete GPU-driven architecture and usually the most portable starting point.
Why can fewer draw calls make a frame slower?
GPU culling, memory traffic, synchronization, atomics, poor sorting, or bindless cache misses can cost more than the CPU work removed.
The Bottom Line
Start with GPU-resident scene data, frustum culling, indirect draws, explicit synchronization, and a tested CPU fallback. Add compaction, occlusion, sorting, meshlets, or work graphs only when profiling shows that their complexity removes a measured bottleneck.
Quick Recap
Product prices and availability are accurate as of the date/time indicated and are subject to change. Any price and availability information displayed on Amazon at the time of purchase will apply.

