
Recommended Free Tools
iTechGuides is reader-supported. When you buy through links on our site, we may earn an affiliate commission. As an Amazon Associate I earn from qualifying purchases. Learn more
Micron has not verified a specific edge-inference memory product entering mass production in 2028. Its published portfolio does show a broader strategy: use LPDDR, DDR, DRAM and nonvolatile storage to keep AI inference close to the sensor, reducing cloud data movement and improving latency and energy efficiency. HBM remains aimed mainly at high-throughput data-center systems, although newer generations deliver substantially better bandwidth and power efficiency.
What “Micron edge-inference memory” actually means
Micron’s official material does not identify one product called “edge-inference memory.” The term describes a system approach in which memory is selected and integrated around an edge processor’s power, latency and bandwidth limits. The portfolio spans LPDDR and DDR for active workloads, DRAM for high-speed working data, and storage technologies for models and persistent robot data.
Micron says edge systems must perform real-time inference at the lowest possible tera operations per second per watt (TOPS/W). Its edge-AI explanation also notes that models are commonly trained in the cloud, then optimized for deployment on an edge device. Keeping the optimized model and sensor-processing pipeline on the robot avoids repeatedly sending raw data to a remote service.
Quick wins for a faster PC:
Fix the driver behind crashes, sound loss and screen glitchesFind Drivers →Clear out junk files and repair common Windows errorsFree Scan →Scan for outdated or missing drivers - takes under a minuteDriver Scan →Why memory is central to an AI robot
A robot’s processor can only react as quickly as the perception pipeline supplies weights, camera frames, lidar returns and intermediate tensors. If those data repeatedly cross a slow or distant memory boundary, the accelerator can sit idle while the robot consumes power moving data rather than computing on it.
#1 Best Overall

- Boosts System Performance: 32GB DDR5 RAM laptop memory kit (2x16GB) that operates at 5600MHz, 5200MHz, or 4800MHz to improve multitasking and system responsiveness for smoother performance
- Accelerated gaming performance: Every millisecond gained in fast-paced gameplay counts—power through heavy workloads and benefit from versatile downclocking and higher frame rates
- Optimized DDR5 compatibility: Best for 12th Gen Intel Core and AMD Ryzen 7000 Series processors — Intel XMP 3.0 and AMD EXPO also supported on the same RAM module
- Trusted Micron Quality: Backed by 42 years of memory expertise, this DDR5 RAM is rigorously tested at both component and module levels, ensuring top performance and reliability
- ECC Type = Non-ECC, Form Factor = SODIMM, Pin Count = 262-Pin, PC Speed = PC5-44800, Voltage = 1.1V, Rank And Configuration = 1Rx8
Edge designs therefore prioritize predictable latency, low energy per transfer, sufficient capacity for the active model and operation within a tightly constrained thermal envelope. Micron presents LPDDR as a way to provide high-speed, high-bandwidth transfer without giving up power efficiency. In one cited example, Micron and Hailo illustrate processor-memory co-design rather than treating memory as a replaceable commodity.
Volatile memory handles the live control loop
LPDDR, DDR and other DRAM retain data only while powered, but they offer the speed and latency needed for active inference. They hold model layers being executed, camera and lidar buffers, feature maps, operating-system data and short-lived planning state.
Nonvolatile storage preserves the robot’s learned state
eMMC, UFS, NVMe and SSD-class storage retain data without power. A robot can use them for the optimized model, multiple skill packages, maps, logs, firmware, calibration files and identity-related data. Storage is slower than working DRAM, so the normal pattern is to load the pieces needed for a task into volatile memory before execution.
The Tool Desk
Outbyte PC Repair FREERepair Windows errors before they cause bigger problemsFix Now →Outbyte Driver Updater FREEFix the driver behind crashes, sound loss and screen glitchesFind Drivers →Rank #2
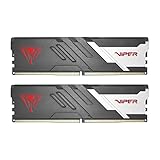
- Capacity: 32GB (2 x 16GB) 6000MHz
- Tested Timings: 30-40-40-76
- Feature Overclock: XMP 3.0 / EXPO overclocking supported
- Compatibility: Tested across latest DDR5 platforms for reliability on high performance
- Limited lifetime warranty
| Memory or storage class | Primary robot role | Strength | Constraint |
|---|---|---|---|
| LPDDR | Active inference, sensor buffers and control | High transfer speed with power-efficient operation | Volatile; capacity and package choices depend on the platform |
| DDR/DRAM | Working memory for processors and accelerators | Flexible, low-latency access | Volatile and power-hungry relative to persistent storage |
| eMMC/UFS | Boot image, models and durable device data | Nonvolatile retention in an embedded form factor | Lower bandwidth and higher access latency than DRAM |
| NVMe/SSD | Large model libraries, maps, logs and updates | High capacity and fast persistent access | Power, thermal and mechanical integration costs |
| HBM | Very high-bandwidth accelerator memory | Exceptional bandwidth close to a large compute package | Advanced packaging, thermal limits, cost and OEM availability |
Does HBM4 solve HBM’s power-efficiency weakness?
HBM is designed primarily for data-center accelerators that need maximum bandwidth and throughput. Micron’s 2026 figures show the scale of that performance: an HBM3E 12-high stack is specified at 1.2 TB/s, while a 36GB 12-high HBM4 stack is specified at more than 2.8 TB/s. Micron also describes that HBM4 configuration as more than 20% more power-efficient than the prior generation.
Those improvements reduce the energy cost per unit of transferred data, but they do not make HBM automatically suitable for every robot. A mobile or industrial robot must still accommodate the HBM package, its cooling solution, board and substrate constraints, manufacturing yield, and purchase cost. The relevant question is not whether HBM is faster; it is whether the robot’s model and sensor workload can justify that bandwidth and integration burden.
For some large, stationary or premium robots with a centralized high-performance compute module, HBM could be appropriate. Smaller, battery-powered platforms are more likely to pair an accelerator with soldered LPDDR or conventional DRAM and use nonvolatile storage for models and data.
Rank #3

- Boosts System Performance: 32GB DDR5 overclocking desktop memory RAM kit (2x16GB) that operates at 6000MHz to improve gaming, multitasking and system responsiveness for smoother performance
- Accelerated gaming performance: Every millisecond gained in fast-paced gameplay counts—benefit from lower latency for higher frame rates, perfect for AAA games
- Optimized DDR5 compatibility: Compatible 13th gen intel core CPUs or newer AMD Ryzen 9000 series CPus
- Trusted Micron Quality: Backed by 42 years of memory expertise, this DDR5 RAM is rigorously tested at both component and module levels, ensuring top performance and reliability
- Top-Tier Overclocking: 32GB of DDR5 RAM 32GB, 6000MHz at extended timings of 36-38-38-80 provide stable overclocking performance and lower latency compared to usual Crucial Pro Series DRAM modules
Why edge memory can be more efficient than simply adding HBM
Power efficiency depends on the complete path from sensor to result. A memory subsystem can save energy by reducing transfers, keeping frequently reused data nearby, matching channel width to the accelerator, and avoiding unnecessary movement between cloud, host processor and accelerator. LPDDR-based co-design addresses those system-level costs even when its peak bandwidth is far below HBM.
Micron also reports that GDDR7 can deliver up to 33% higher AI-inference throughput than GDDR6. That figure indicates another performance-per-watt option for systems that need more bandwidth than typical low-power memory but do not use an HBM package. It is a throughput comparison, not a claim that every robot will achieve the same gain; actual results depend on the accelerator, model, software and thermal limits.
What is known about the 2028 mass-production target
The collected Micron product and technology material supports edge-AI memory use cases and current HBM efficiency improvements, but it does not verify a dated roadmap that names an edge-inference memory product for mass production in 2028. The 2028 statement should therefore be treated as an unconfirmed premise, not an established Micron schedule.
Rank #4

- Elevated performance for gamers & creators: 128GB kit DDR5 for enhanced productivity—accelerate demanding tasks and enjoy higher frame rates with this high-speed RAM
- Enhanced PC performance: Crucial Pro RAM 128GB kit with 2x64GB DDR5 operating at the speed of 5600MHz with 5200MHz or 4800MHz downclock support
- Top-tier RAM capacity: 128GB DDR5 RAM kit (2x64GB) compatible with latest Intel Core Ultra Series 2 & 14th Gen Core CPUs and AMD Ryzen 9000 Series desktop CPUs and above
- Low-profile, matte black heat spreader: Enhance your gaming rig with a sleek, modern look. With our integrated low-profile heat spreader, Crucial DDR5 Pro can even fit in smaller PCs
- Supports Intel XMP 3.0 and AMD EXPO on the same module: Achieve easy performance recovery on CPUs that suppress rated memory speeds with Intel XMP 3.0 or AMD EXPO turned on in the UEFI/BIOS settings. Get the full value of your investment without overpaying for performance
A credible confirmation would need a dated Micron product announcement, earnings disclosure or roadmap that identifies the product, memory type, production status and intended market. Until then, manufacturers should plan around currently announced LPDDR, DDR, DRAM, storage, HBM3E, HBM4 or GDDR7 offerings rather than reserving a design for an unnamed 2028 part.
Independent reader supportYour contribution helps us test, update, and keep practical guides available for everyone.A practical memory stack for an AI-powered robot
- Train and refine the model in the cloud or a data center. Quantize, prune or otherwise optimize it for the target accelerator and its available memory capacity.
- Place the active model in volatile memory. Use LPDDR or DRAM sized for the model, sensor buffers, intermediate tensors and operating-system overhead, with enough headroom for real-time scheduling.
- Keep persistent assets in nonvolatile storage. Store the base model, alternate skills, maps, logs, firmware and calibration data on eMMC, UFS, NVMe or SSD-class media as the platform requires.
- Measure the complete pipeline. Check sensor-to-actuator latency, bandwidth utilization, energy per inference, memory temperature and sustained performance—not only the accelerator’s TOPS rating.
- Choose HBM only when the workload needs it. High-bandwidth memory can fit a large centralized compute design, but its package, cooling and cost implications must be justified by the robot’s sustained workload.
How OEMs should evaluate Micron’s roadmap
- Power budget: calculate energy for memory transfers and cooling, not just compute.
- Latency target: verify worst-case response time for perception, planning and control.
- Capacity: include model growth, multiple skills, sensor history and safety redundancy.
- Integration: confirm package availability, board dimensions, thermal design and supply commitments.
- Lifecycle: require a documented production schedule and software support before committing to a future memory type.
Micron’s evidence supports a clear direction toward memory-and-processor co-design for efficient on-device inference. It does not yet support saying that a named Micron edge-inference memory product will be mass-produced in 2028.
Free tools Windows power users keep installed
One-click scans. No signup required.
Quick Recap
Product prices and availability are accurate as of the date/time indicated and are subject to change. Any price and availability information displayed on Amazon at the time of purchase will apply.

