
The Tool Desk
Outbyte Driver Updater FREEFix the driver behind crashes, sound loss and screen glitchesFind Drivers →Outbyte PC Repair FREERepair Windows errors before they cause bigger problemsFix Now →iTechGuides is reader-supported. When you buy through links on our site, we may earn an affiliate commission. As an Amazon Associate I earn from qualifying purchases. Learn more
Evaluate a multilingual voice agent across the whole interaction: what it heard, what it understood, which critical details it preserved, what action it took, and what it said back. Word error rate (WER) alone cannot show whether the agent completed the request. Report task accuracy separately from spoken-interaction quality, and break results down by language, code-switch pattern, accent, and acoustic condition.
What should count as a successful voice-agent interaction?
Define success before running tests. For each scenario, write down the required end state, applicable policy constraints, and every field that must be correct for the task to count as a pass. A plausible-sounding response is not a pass if the agent used the wrong amount, changed an identifier, or failed to perform the requested action.
Specify the task and its critical fields
For a booking, support request, or transaction, list the fields that determine execution: for example, a date, amount, account identifier, destination, or stated constraint. Decide in advance whether each field must match exactly, may be normalized (such as a spoken date rendered in a standard format), or can be omitted. Then define the verified task state—for instance, whether a record was actually created or updated—not just the response the agent produced.
Quick wins for a faster PC:
Scan for outdated or missing drivers - takes under a minuteDriver Scan →Repair Windows errors before they cause bigger problemsFix Now →Score critical-field accuracy independently from overall task completion. A useful project-specific measure is the share of required fields captured and normalized correctly, with results also reported per field type. This is an evaluation-design recommendation, not a universal metric prescribed by the benchmarks. It makes consequential errors visible even when an aggregate task score looks acceptable.
#1 Best Overall

- Teacher must haves: WB002 Bluetooth voice amplifier can be a thoughtful and practical gift for a teacher who frequently speaks in front of large groups or classrooms.15W powerful output could cover 10000 sq.ft,kindly recommend use this portable headset microphone speaker system indoors like classroom,it's plenty loud for a class of around 50 middle schoolers to hear you.
- Easy Pairing and Operation: Wireless voice ampliifer unit is very easy to pair with bluetooth headset microphone,just turn them on and they will be paired automatically.Operation is straight forward, even if you could without needing the manual Everybody can very quickly up and running.
- Long Battery Life: Portable voice amplifier built in 2600mAh rechargeable battery that could get up to 12-15 hours on one charge, perfect for teachers and presenters. wireless microphone headset support 8 to 10 hours. Both them are be charged quickly with the included Type-C charging cable.
- Lightweight and Versatile: Bluetooth voice amplifier is lightweight to wear,it can be clipped to a belt or hung around the neck using the supplied neck strap.The bluetooth headset is lightweight and doesn't slide off head.Good think that wireless microphones come in two parts, it can also be used as handheld mic if anyone wants to use it that way. The headset comes apart very easily for storage.
- Affordable and Reliable: The Voice Amplifier WB002 is an affordable yet reliable personal amplifier/speaker that comes with a Bluetooth earpiece/mic, a belt clip and a lanyard. WinBridge provides a one-year warranty + Lifetime Support and a 30-day return policy for added peace of mind.
Separate accuracy from experience
Keep two scorecards. EVA-Bench, published by ServiceNow AI Research in October 2026, distinguishes accuracy dimensions such as task completion, faithfulness, and speech fidelity (EVA-A) from experience dimensions such as conversation progression, conciseness, and turn timing (EVA-X). An agent can complete a task while interrupting repeatedly, or sound natural while failing to carry it out; one score should not hide that difference.
How should the test set represent multilingual speech?
Choose languages and switching patterns based on the people and tasks the agent will actually serve. A benchmark’s language coverage is evidence about that benchmark, not a universal list of what a deployed system can handle.
Rank #2

- Designed for Home Assistant Voice & Music Workflows: Preloaded with Home Assistant Voice Assistant and Music Assistant. Functions as both a voice input terminal and an audio playback endpoint.
- Dual Microphones for Voice Capture: Built with dual digital microphones for wake word or button-activated voice capture. Audio is streamed to the Home Assistant voice pipeline.
- Integrated 3W Speaker for Direct Playback: The built-in 3W/4Ω speaker supports TTS playback, Music Assistant streaming, and system audio without external speakers.
- Linux-Based Local Operation: Runs a lightweight Linux system on a quad-core ARM A53 CPU with 256MB RAM and 512MB flash for local audio processing.
- Development & Debugging Capabilities: Supports firmware flashing, and also provides access to live logs, on-device editing—suitable for routine development or issue diagnosis.
Include the ways speakers actually switch
Where relevant, test switches within a sentence as well as longer stretches in another language. Include different speakers and accents, and make sure the examples cover task-critical words in both languages—for instance, a request spoken mostly in one language with a name, date, or address in another. A test set that contains bilingual utterances but no critical details near a language boundary may miss the errors that matter most.
Do these 3 things before closing this tab:
1Repair Windows errors before they cause bigger problems2Scan for outdated or missing drivers - takes under a minute3Clear out junk files and repair common Windows errorsUse native-speaker review where feasible to check that prompts and reference transcripts are natural and that language-specific scoring choices are defensible. τ-Multilingual reports native-speaker review; the ServiceNow code-switch ASR benchmark describes review by an AI/NLP linguist who is a native speaker of the matrix language.
Rank #3

- 1.CLEAR & POWERFUL 15W VOICE AMPLIFICATION:Designed with a 15W high-performance speaker and advanced audio processing, this voice amplifier delivers loud, clear sound for audiences up to 50 people. Perfect for teachers, tour guides, trainers, coaches, presentations, classrooms, meetings, and outdoor activities
- 2.WIRELESS LAPEL MICROPHONE FOR HANDS-FREE USE:Includes a wireless lapel microphone that lets you move freely while speaking. This microphone with speaker system provides stable transmission and clear voice pickup, making it ideal for teaching, training sessions, public speaking, fitness instruction, and guided tours
- 3.12-15 HOURS PLAYTIME & 15+ HOURS MIC RUNTIME:Built-in 2600mAh rechargeable battery delivers up to 12-15 hours of continuous use. The wireless microphone lasts over 15 hours on a single charge, helping you stay productive throughout the day without interruptio
- 4.BLUETOOTH CONNECTIVITY FOR EASY AUDIO STREAMING:Connect your smartphone, tablet, or other Bluetooth-enabled devices to play music, educational content, workout audio, or announcements. A versatile Bluetooth voice amplifier for work, school, fitness classes, and events
- 5.LIGHTWEIGHT, PORTABLE & EASY TO WEAR:Compact and lightweight with a convenient belt clip design. Whether you're a teacher, tour guide, church speaker, coach, presenter, or event organizer, this portable voice amplifier is built for all-day comfort and reliable performance
Vary acoustic conditions deliberately
Test realistic noise and a range of accents rather than assuming clean, studio-like audio represents customers. τ-Voice evaluates realistic audio, including noise and diverse accents, while EVA-Bench includes controlled accent and noise perturbations. Record the condition for every result so a clean-audio score is not mistaken for performance under a noisy call or unfamiliar accent.
Use published benchmarks as coverage examples, not a leaderboard
| Work | Reported scope | What it can inform |
|---|---|---|
| τ-Multilingual (2026) | 4,500 full-duplex calls; Spanish, Portuguese, Hindi, Korean, and Mandarin | Language-specific task and interaction outcomes; its reported results should stay attached to the benchmark and configuration. |
| τ-Voice (2026) | 278 tasks | Grounded-task completion and robustness testing with realistic audio conditions. |
| EVA-Bench (ServiceNow AI Research, October 2026) | 213 scenarios across three enterprise domains | Separate accuracy and experience dimensions, including repeated-run measures. |
| ServiceNow code-switch ASR benchmark (2026) | 259 Spanish-English, 298 French-English, 188 Canadian French-English, and 173 German-English records | Code-switch recognition measures across four named language pairings; the article describes synthesized audio, not spontaneous natural speech. |
| HiKE (2026) | Korean-English; non-synthetic speech | An example of code-switch evaluation using non-synthetic speech for a specific language pair. |
These works differ in language coverage, tasks, audio, and system configuration, so their scores are not a direct cross-paper ranking. For example, τ-Multilingual reports distinct outcomes across its five languages, but that does not establish a universal ranking of languages or predict performance on a different system.
Rank #4

- A True Original Voice Amplifier that amplifies your voice without making it mechanized in sound quality
- ZOWEETEK Voice Amplifier Amplifys your voice and saves your throat. The sound is clear, crisp, no noise and no distortion. The max 10 watts sound can cover about 10000 sq. ft (1000 ㎡), loud enough to cover a big room
- Portable Voice Amplifier Compact size (4. 1 x 1. 4 x 3. 4 inches) and light weight (0. 36 lb.). You can use the back clip to fix it on your belt or pocket. You can also use waistbelt to tie it around your waist or hang it on your neck
- Built in 1800 mAh rechargeable lithium battery. Continuously working time is up to 12 hours. You can use USB cable to charge this mini voice amplifier. Only needs 3~5 hours to fully charge it
- Supports MP3 audio playing: TF (Micro SD) card playing & USB flash drive playing. Can repeat single tune, loop all music and switch songs
Which metrics reveal where the agent failed?
Score the pipeline in layers. Each measure answers a different question, and none should stand in for the whole interaction.
Free tools Windows power users keep installed
One-click scans. No signup required.
Transcription and meaning
- WER: measures word-level transcription errors. Break it down by language when possible, but do not treat every word error as equally consequential.
- Semantic preservation: check whether the intended meaning survived, especially around code-switches. The ServiceNow benchmark reports semantic word error rate (SWER) as well as WER.
- Answer error: measure whether the task-relevant answer is wrong. The ServiceNow benchmark reports answer error rate alongside WER and SWER, illustrating that lexical, semantic, and answer-level errors are distinct.
Critical fields, action, and policy
- Critical-field accuracy: score required values independently, including entity recognition and normalization. Make the scoring rule explicit for each field.
- Task completion: verify the result in the target environment or with a task grader. τ-Voice uses verifiable completion of grounded tasks; EVA-Bench includes task completion.
- Faithfulness: check whether the agent followed the request and applicable policy rather than merely returning a correct-looking answer. EVA-Bench includes faithfulness as an accuracy dimension.
- Response completeness: compare the spoken response with the information the scenario requires. Microsoft’s Voice Live guidance includes response-completeness and task-completion evaluators; it notes that the described evaluation does not measure WER or mean opinion score (MOS).
Spoken interaction
Score turn-taking, interruptions, conversation progression, conciseness, timing, and speech fidelity separately from whether the task succeeded. These measures help distinguish an accurate but frustrating interaction from a smooth conversation that loses important information.
Best Value
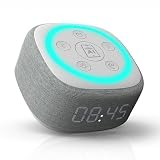
- Bedside Speaker and Sleep Sound Machine: This compact wireless speaker combines Bluetooth audio, 16 built-in sleep sounds (white noise, brown noise, rain, ocean, and more) and multiple RGB night light modes in one rechargeable device. Stream music while the light pulses in time with your audio, or switch to sleep mode and drift off to the sound you picked. A practical gift for teens and adults upgrading a bedroom setup.
- One Button, Your AI, Instantly: The BRS-180 has a dedicated AI button on top. Press it once and it wakes Google Assistant, Siri, or whichever assistant lives on your paired device. Ask it anything, play music, set a reminder, check the weather, or control your smart home, all from across the room without picking up your phone.
- Pairs in Seconds and Stays Connected: Bluetooth connects to any iOS or Android phone, tablet, or laptop with no app and no account required. Once paired, the 12-hour LED clock display syncs the correct time on its own. Three display settings keep you in control: full brightness, dimmed, or completely off for total darkness. A memory function saves your last volume, sleep sound, and light settings automatically.
- Built for the Nightstand, Night After Night: The soft fabric-wrapped enclosure sits on a nightstand, dresser, or shelf without looking like a gadget. Plug it in over USB-C and it runs continuously, or use the built-in rechargeable battery for up to 6 hours of wireless playback. Either way it is ready when you are. Available in White, Black, and Green.
- 16 Sleep Sounds, Fully Customizable: Choose from 16 built-in sleep sounds that play straight from the speaker with no phone, no app, and no subscription. Set a 15, 30, or 60-minute sleep timer and the sound fades out by itself. Want a different library? Connect it to any PC with the included USB-C cable and swap out every sound stored on the device.
How can you test reliability rather than a lucky run?
Repeat scenarios when model behavior or simulated dialogue is stochastic. Report the number of runs and the sampling protocol, then distinguish a single-run result from performance across repeated attempts. EVA-Bench reports pass@1, pass@k, and pass^k to distinguish peak performance from reliable capability; preserve the benchmark’s definitions when using those measures rather than treating them as interchangeable.
For your own evaluation, state what counts as passing each run and how repeated outcomes are summarized. A single successful interaction demonstrates that the agent can succeed under that test condition; it does not establish that it will do so consistently.
How should failures be diagnosed and reported?
For each failed scenario, identify the earliest stage where the result diverged from the expected path. A practical diagnosis map is:
What’s actually slowing this PC down?
Pick the symptom - the matching free tool is one click away.
- Speech recognition: Were the words or language segments transcribed incorrectly?
- Language identification and switching: Did the system miss a language change or assign a span to the wrong language?
- Entity handling: Was a name, date, amount, identifier, or constraint lost or normalized incorrectly?
- Dialogue state and policy: Did the agent misunderstand what remained to be clarified, or fail to follow a required constraint?
- Tool choice and execution: Did it select the wrong action, or fail to produce the intended state change?
- Response generation: Did the spoken response omit required information, misstate the outcome, or create an interaction problem?
This is a useful diagnostic taxonomy, not a mandatory standard established by the cited benchmarks. In the report, break results down by language, language pair, switching pattern, accent, and noise condition. Keep separate figures for transcription, meaning, critical fields, verified task completion, interaction, and repeated-run reliability instead of compressing them into one headline score.
What can user preference research tell you about code-mixing?
Whether an agent should mirror a speaker’s code-mixing is partly a user-experience question, not just a recognition question. A 2020 Microsoft Research study by Bawa, Khadpe, Joshi, Bali, and Choudhury used 91 bilingual participants to study perceptions of chatbots that reciprocate users’ code-mixing. That study concerned text chatbots; its findings should not be treated as direct evidence about spoken voice agents. If mirroring language choice matters to the product, test it with the intended users and measure preference separately from task accuracy.
Quick Recap
Product prices and availability are accurate as of the date/time indicated and are subject to change. Any price and availability information displayed on Amazon at the time of purchase will apply.

