
Windows Errors? Fix Them Before They Spread
Repair common Windows errors and clear accumulated junk for a smoother, more stable PC - no reinstall needed.Free scan · no reinstallCrashes, No Sound, or Screen Glitches?
Random freezes, missing sound and display glitches usually trace back to one bad driver. Find and replace yours safely.Free scan · under a minuteiTechGuides is reader-supported. When you buy through links on our site, we may earn an affiliate commission. As an Amazon Associate I earn from qualifying purchases. Learn more
Build AI/ML infrastructure around the path data takes from governed source systems to a monitored model—not around a fixed list of products. A practical design preserves trustworthy source data, creates reusable curated datasets, records how models were built, and gives each model a controlled route to batch or online production. Add components such as a feature store only when the workload and operating model justify them.
Start with the workload and its constraints
Before choosing a platform pattern, establish what data the models need, how quickly that data changes, how predictions will be used, and who will operate the system. These answers determine whether you need streaming ingestion, online feature access, scheduled scoring, or a more modest batch pipeline.


- Data shape: Identify whether inputs are structured tables, event streams, text, images, video, or a mixture.
- Freshness and latency: Set expectations for how current the input data and predictions must be.
- Reuse: Find out whether datasets, features, or predictions will be shared across models and products.
- Governance: Document owners, permitted uses, access rules, retention needs, and audit requirements.
- Operating capacity: Account for team skills, production support, recovery needs, and the burden of maintaining additional services.
- Scale and cost: Consider storage, compute, data movement, and concurrency under the actual workload, rather than assuming a platform pattern will be economical at every scale.
Architecture guidance from Microsoft and AWS describes useful components and patterns, but it does not establish a neutral cross-vendor performance or cost threshold. Where scale, freshness, or service behavior determines the choice, test a representative workload and measure it in your own environment.
Quick wins for a faster PC:
Clear out junk files and repair common Windows errorsFree Scan →Scan for outdated or missing drivers - takes under a minuteDriver Scan →Repair Windows errors before they cause bigger problemsFix Now →Use a lifecycle architecture, not a product checklist
A useful conceptual flow is:
- Source systems and governed data access
- Ingestion and a durable raw-data layer
- Repeatable processing into curated datasets
- An optional managed feature layer
- Training, evaluation, and experiment records
- A versioned model registry and release checks
- Batch scoring or online inference
- Monitoring, investigation, and controlled feedback or retraining
This is a design framework, not a requirement to deploy every component as a separate service. A small team may combine steps; a larger organization may need explicit boundaries for ownership, permissions, and support.
How should data enter the platform?
Inventory each source system, its owner, permitted uses, update cadence, expected volume, and data format. Retaining an ingest or raw layer gives teams a way to rebuild downstream datasets when business definitions or transformations change. It also helps preserve the distinction between received data and data that has been cleaned or interpreted for a particular use.
Choose the ingestion pattern according to when and where transformations make sense:
| Pattern | Where transformation happens | Good fit | Important consideration |
|---|---|---|---|
| ETL | Before data is loaded into its destination | Workloads that need data transformed before it reaches the target | Transformation rules operate before the destination holds the loaded data. |
| ELT | After data is loaded | Workloads that benefit from retaining raw inputs and preparing them flexibly downstream | Loading first preserves input for later preparation, but downstream transformations still need clear ownership and quality checks. |
| EL | After loading, as needed by consumers | Document or media ingestion for GenAI and retrieval-augmented generation, where steps such as chunking may happen later | Do not assume content is ready for model use merely because it has been ingested. |
ELT is often recommended for flexibility, but it is not a universal rule. The right choice depends on source constraints, governance, transformation needs, and the target workload.
Turn ingested data into trusted, reusable datasets
Build repeatable pipelines that validate, clean, enrich, and aggregate data. A layered arrangement can distinguish ingested data, refined or curated data, and consumer-oriented data products. For each layer, make schemas, definitions, ownership, lifecycle, and quality expectations discoverable.
Place quality checks around the pipeline steps where errors can be detected and handled. A catalog helps users find appropriate datasets; lineage helps them understand where data came from and how it changed. Neither replaces clear ownership. An operational copy that downstream products rely on can become a silo if it drifts from its source or lacks an agreed maintenance process.
When is a feature store worth adding?
A feature store is a managed catalog and serving layer for curated model features. It can record feature definitions, sources, transformations, owners, update frequency, generation time, lineage, and versions. That makes shared features easier to find and can help keep training inputs and production inputs consistent.
Adopt one when duplicated feature work, cross-model reuse, lineage, versioning, or point-in-time training needs create enough value to warrant another governed data layer. For a single-model workflow, the added operational and governance burden may outweigh the benefit. Treat features as potentially sensitive data: apply appropriate access controls, encryption, and auditing.
Make training reproducible and separate environments
Give development and production distinct workspaces and controlled access to data and compute. Record each experiment’s inputs, parameters, metrics, and artifacts so a model can be reproduced and assessed. Platform selection should account for versioning, governance, scalability, and security—not just notebook convenience.
Rank #3
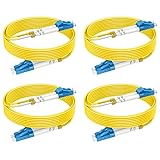
- 【6ft/2m 4pack OS2 Fiber Optic Patch Cable】 As AI continues to advance at an unprecedented pace, having reliable and efficient connectivity is crucial.RamboCables offers a cost-effective solution for your AI infrastructure with the 4-Pack OS2 LC-LC Single Mode Fiber Patch Cables. These high-quality fiber optic patch cords are designed to provide reliable and efficient connectivity for your AI applications.
- 【Wide Application】Whether you're using AI for data processing, machine learning, or other applications, the OS2 LC-LC Single Mode Duplex Fiber Patch Cable is ideal for connecting high-speed transceivers such as 10G SR, 40G BIDI SR, QSFP+, SFP+, and more. It is suitable for 1G/10G/40G/100G/400G Ethernet connections, making it a versatile choice for data centers, cloud storage networks, server farms and any other environments where reliable fiber optic connectivity is essential.
- 【Max Transmission Distance】With the OS2 Single Mode Optic Fiber Cable, you can transmit data for up to 10km at 1310nm or up to 40km at 1550nm. It offers excellent bandwidth at 1310nm-1550nm, with a low attenuation rate of 0.36 dB/km-0.22 dB/km, and can operate in a wide temperature range of -20~70°C, ensuring reliable performance even in harsh environments.
- 【Industry Standard】The OS2 LC-LC Fiber Patch Cords are built to industry standards. With LSZH (Low Smoke Zero Halogen) jacket, LC/UPC to LC/UPC connectors, 9/125μm high-rated fiber cladding, and a 2.0mm cable diameter, feature an LSZH environmentally friendly jacket, Zirconia Ceramic Ferrule, and 15mm minimum bend radius, all in accordance with EIA/TIA 604-2 standards, ensuring optimum insertion loss (IL) and return loss (RL) performance.
- 【Standards & Reliability】With over 15 years of experience manufacturing fiber patch cords, RamboCables are dedicated to supplying high-quality products and services. Our fiber patch cables comply with industry standards to enable efficient network transmission.
Decide deliberately how development teams use production data. Training or tuning with production data may improve relevance, but sensitive data outside production needs strong safeguards. Training on non-production data can simplify some development controls, yet repeated training across environments can increase compute and storage use. In either pattern, define access permissions and keep development isolated from production.
Promote models through a controlled release path
Use a versioned registry to track models and their metadata, configurations, and lineage. Before release, route a candidate through staging and tests suited to the use case. Automate repeatable checks, and use human approval where risk or organizational policy calls for it.
Keep the release path consistent from experiment to production: a model should be traceable to its data and code, evaluation results, and approval. That makes it easier to investigate a failure or reproduce a prior release than relying on an unrecorded handoff from a development workspace.
The Tool Desk
Outbyte Driver Updater FREEScan for outdated or missing drivers - takes under a minuteDriver Scan →Outbyte PC Repair FREERepair Windows errors before they cause bigger problemsFix Now →Choose batch or online inference by how predictions are consumed
Batch inference computes predictions ahead of time for later use. Online serving returns predictions in response to requests, supporting immediate or near-real-time decisions. Neither is inherently the better or cheaper choice; compare the actual freshness, latency, reuse, reliability, and cost requirements.
| Decision factor | Batch inference | Online inference |
|---|---|---|
| Prediction timing | Predictions can be prepared before consumers need them. | Predictions are needed in response to a live request. |
| Reuse | Useful when computed predictions can serve multiple later consumers or processes. | Useful when each request needs a current prediction for that interaction. |
| Freshness | Depends on the scoring schedule and the age of the inputs. | Can use current inputs, subject to the serving path and data availability. |
| Operational focus | Pipeline scheduling, completion, retries, and delivery of results. | Endpoint response, capacity, reliability, and serving dependencies. |
Measure end-to-end behavior on a representative workload. Include the cost and reliability of the whole path—not only model computation—when comparing alternatives.
Independent reader supportYour contribution helps us test, update, and keep practical guides available for everyone.Build governance and interoperability into the platform
Access control, audit, lineage, cataloging, and data quality should apply across ingestion, curated datasets, features, training, model artifacts, and serving. Use stable schemas and data contracts so producers and consumers can detect incompatible changes. Keep interfaces and formats as open as practical for the organization’s needs; portability matters, but it should be weighed against the operational capabilities a chosen platform provides.
A centralized platform can make shared controls and consistent standards easier to operate. A domain-oriented data mesh can give business units more autonomy to produce and exchange data products under shared governance. These patterns are not mutually exclusive: organizations can introduce domain ownership gradually while retaining common policies and platform capabilities. Neither a lakehouse label nor a mesh structure by itself solves data quality or unclear ownership.
Operate models with monitoring and a recovery path
Monitor data, model, and infrastructure behavior after release. Depending on the use case, that includes data or model drift, model performance, endpoint response, and capacity. Define who investigates alerts, how failed pipeline steps are recovered, and what evidence is needed before retraining or rolling out a replacement.
Feed monitoring findings into a controlled investigation and retraining path rather than making an untracked model change. If retraining is warranted, preserve experiment records, evaluate the candidate, and use the same release controls as for an initial deployment.
Compare designs with a workload-specific proof of concept
When multiple architectures are plausible, compare them using the same representative data and operating assumptions. Evaluate:
- Latency and data freshness under realistic input patterns
- Whether data products, features, or predictions can be reused as intended
- Permissions, lineage, auditability, privacy, and retention controls
- Interoperability with existing systems and the effort needed to move data
- Team autonomy versus the complexity of supporting domain-owned products
- Storage, compute, concurrency, reliability, recovery, and ongoing operational effort
Use the results to choose the simplest design that meets the workload’s governance and reliability requirements. Add a feature layer, additional serving path, or domain boundary when a concrete need justifies the added responsibility.
Do these 3 things before closing this tab:
1Scan for outdated or missing drivers - takes under a minute2Repair Windows errors before they cause bigger problems3Fix the driver behind crashes, sound loss and screen glitchesQuick Recap
Product prices and availability are accurate as of the date/time indicated and are subject to change. Any price and availability information displayed on Amazon at the time of purchase will apply.

