
Recommended Free Tools
iTechGuides is reader-supported. When you buy through links on our site, we may earn an affiliate commission. As an Amazon Associate I earn from qualifying purchases. Learn more
For a private deployment, start with OpenAI’s open-weight gpt-oss-120b or gpt-oss-20b, then choose the serving runtime that matches your hardware and traffic. Use Ollama for the simplest local developer experience, llama.cpp for broad hardware coverage and constrained machines, and vLLM for concurrent production serving on suitable NVIDIA CUDA infrastructure. These models run on infrastructure you control—on premises, in a private cloud, or through a hosting partner—and are not served through the OpenAI API.
The important distinction is between the model and the runtime. A strong model does not automatically make a good deployment: memory, quantization, context length, concurrency, security controls, monitoring, and operational support determine whether a self-hosted system is practical.
What counts as a private OpenAI alternative?
A private alternative is an AI model and serving stack that you operate on infrastructure under your organization’s control. The inference request, prompt, retrieved documents, and generated answer can remain inside your network boundary instead of being sent to a public API. Your environment might be an office server, a datacenter cluster, a private-cloud virtual machine, or a managed hosting partner configured for your organization.
OpenAI’s gpt-oss-120b and gpt-oss-20b are open-weight reasoning models intended for this arrangement. “Open-weight” means the model weights are available to deploy; it does not mean that every operational component, support service, or safety obligation disappears. The models are not endpoints in the OpenAI API. You obtain the weights, select a compatible runtime, and operate the resulting service yourself or contract a hosting provider to operate the infrastructure.
#1 Best Overall

- GPU processor: NVIDIA RTX A5500
- CUDA cores: 10240
- 24GB GDDR6 ECC Graphics Memory
- System Interface: PCI-Express 4.0 x16
- 1 x DisplayPort to HDMI adapter
The weights use an Apache 2.0 license subject to the gpt-oss usage policy. Apache 2.0 is permissive, but it is not a waiver of the model’s usage requirements. Your legal, security, and compliance teams should review both the license notice and the usage policy before redistribution or embedding the model in a product.
Which model should you choose?
gpt-oss-120b
The 120-billion-parameter model is the higher-capability option in this pair. It is the more natural starting point for difficult reasoning, technical analysis, and workloads where answer quality is worth a larger hardware footprint. Its parameter count does not by itself determine the required GPU memory: quantization, context length, batch size, runtime overhead, and simultaneous requests all affect the final requirement.
gpt-oss-20b
The 20-billion-parameter model is the smaller deployment. It is generally easier to fit on constrained infrastructure and can be a sensible choice for internal assistants, classification, extraction, drafting, and other tasks where the 120b model would be excessive. “Smaller” does not mean “lightweight in every configuration”; long contexts and concurrent users can still require substantial memory.
Published benchmark indicators
The following figures are vendor-published results shown on OpenAI’s 2026 open-models page. They are useful for comparing the two releases under the stated benchmark conditions, but they do not predict accuracy, latency, or cost for your private workload.
| Benchmark | gpt-oss-120b | gpt-oss-20b |
|---|---|---|
| MMLU | 90.0 | 85.3 |
| GPQA Diamond | 80.1 | 71.5 |
| AIME 2024 | 96.6 | 96.0 |
| AIME 2025 | 97.9 | 98.7 |
Benchmark variation matters. The 20b model scores slightly higher than the 120b model on the published AIME 2025 result, while the 120b model leads on MMLU and GPQA Diamond. Treat these numbers as indicators rather than a guarantee that the larger model will win every task. Build a representative evaluation set from your own documents, tools, languages, safety cases, and expected answer lengths.
Rank #2
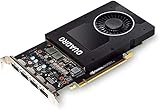
- 1280 CUDA Cores deliver powerful graphics and compute performance
- 5 GB of fast GDDR5x GPU memory holds large models or scenes
- Ideal for 3D Design and FHD video editing, and medical imaging systems (ultrasound)
- Drives up to four displays at 5K resolution with 30-bit color
- Compatible with NVIDIA CUDA, NVIDIA nView and Mosaic
Best runtime by deployment goal
Ollama, llama.cpp, and vLLM can all be used with the gpt-oss models according to OpenAI’s compatibility guidance, but they solve different operational problems.
Do these 3 things before closing this tab:
1Fix the driver behind crashes, sound loss and screen glitches2Clear out junk files and repair common Windows errors3Scan for outdated or missing drivers - takes under a minute| Runtime | Best fit | Hardware emphasis | Operational profile |
|---|---|---|---|
| Ollama | First local experiment, developer workstation, or small team service | Verify the current model package and supported accelerators for your machine | Simplest named entry point; packaging and defaults reduce setup friction |
| llama.cpp | Single-user development, CPU-only inference, Apple Silicon, limited GPU memory, and broad local hardware coverage | CPU and mixed or limited-memory configurations; quantized model workflows | Flexible and efficient, but you own more of the model-file and process configuration |
| vLLM | Multiple concurrent requests, high throughput, and production serving | NVIDIA GPU with CUDA support for Docker’s Model Runner path; verify the supported build for your platform | Designed for serving efficiency and OpenAI-compatible endpoints; more infrastructure work |
Choose Ollama for the shortest path to a working local model
Ollama is the easiest of the named options for many consumer and developer setups. It handles much of the local model lifecycle, so a developer can install the runtime, obtain a compatible gpt-oss package, start an interactive session, and expose a local endpoint for an application. Confirm that the current package includes the model variant you need and check its hardware support before standardizing on it; packaging, tags, and accelerator support can change.
Ollama is a good fit when one person or a small team needs a dependable local assistant and throughput is modest. It is not automatically the best choice for a large, multi-tenant service. You still need authentication, resource limits, logging policy, and a plan for upgrades.
Choose llama.cpp for hardware flexibility
llama.cpp is the practical choice when your priority is running locally across varied hardware. Docker’s comparison positions it for CPU-only systems, Apple Silicon, limited GPU memory, and single-user development. Its quantized-model workflows can reduce memory pressure, and it can use a mixture of CPU and accelerator resources depending on the build and configuration.
This flexibility is valuable for a workstation proof of concept, an edge computer, or a server that cannot provide the CUDA environment expected by a higher-throughput stack. The trade-off is that you must pay closer attention to model-file format, quantization level, context allocation, threading, accelerator offload, and process supervision. Test the exact build and settings on the target machine rather than assuming that a configuration that starts will also meet your latency target.
Rank #3
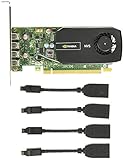
- Quad display support1
- Display Port 1.2 features.H.264 Encoder
- Versatile connectivity options using Mini Display Port (mDP) connector.NVIDIA FXAA and TXAA.Intelligent Power Management
- Multi-display experience with NVIDIA Mosaic technology.NVidia High-Definition Video Technology
- Maximum Power Consumption:35Watts
Choose vLLM for concurrent production traffic
vLLM is the stronger fit when several users or applications will send requests at the same time and throughput matters. It is designed for efficient serving and can provide OpenAI-compatible endpoints, which can simplify migration for clients already written against that API shape. Docker documents an NVIDIA CUDA requirement for its Model Runner path and recommends vLLM for multiple concurrent requests, maximum throughput, and production deployment when the hardware supports it.
Do not interpret that guidance as a universal “GPU required” statement for every vLLM build. vLLM documentation describes CPU and ARM build paths for supported configurations, but support, performance, and feature coverage depend on the specific version and platform. For a production decision, validate the exact accelerator, driver, CUDA, operating-system, and vLLM versions together.
Hardware: size the workload, not just the model
There is no single correct GPU recommendation for self-hosting an LLM. Required memory depends on parameter count, numerical precision or quantization, context length, batch size, concurrency, runtime overhead, and any other models or services sharing the device.
Memory components to account for
- Model weights: the base requirement grows with parameter count and falls as you use a lower-bit quantization. Quantization can change quality and supported features, so measure it rather than choosing solely by memory.
- KV cache: longer prompts and generated outputs consume additional memory. A configuration that works for short chats may fail when users submit large documents.
- Batching and concurrency: serving several requests at once increases memory use but can improve total throughput. Size for your peak, not your average, if rejected requests are unacceptable.
- Runtime and operating-system overhead: leave headroom for the serving process, drivers, tokenizer, monitoring, and other workloads.
- Storage and transfer: model files, alternate quantizations, container layers, and logs need disk space. Initial downloads can also be a significant network event for a private environment.
Match runtime to the available machine
| Your environment | Starting point | Why |
|---|---|---|
| Apple Silicon laptop or desktop | llama.cpp or Ollama | Both are named compatibility paths; llama.cpp is explicitly positioned for Apple Silicon and local development |
| CPU-only server | llama.cpp | Docker identifies it as the better fit for CPU-only inference |
| Small-memory GPU or workstation | llama.cpp, or Ollama after verifying packaging | Quantization and flexible offload are more practical than assuming a large CUDA server |
| CUDA-equipped production server with concurrent users | vLLM | Designed for throughput and concurrency when the supported NVIDIA stack is available |
| Uncertain or mixed fleet | Benchmark llama.cpp first, then compare vLLM on a supported CUDA node | Keeps a portable baseline while testing the higher-throughput path |
For hardware procurement, a “NVIDIA CUDA-capable GPU for local LLM inference” is a defensible description for a vLLM-oriented system. An exact card recommendation requires at least the selected model, quantization, maximum context, target tokens per second, peak concurrent requests, and whether other services share the GPU. Without those inputs, a specific card would be guesswork.
How to deploy a private model safely
1. Define the boundary and workload
- List the data classes the model will process: public text, internal documents, personal data, regulated records, source code, or secrets.
- Decide where inference may run: a workstation, an internal subnet, a private cloud account, or a managed hosting partner.
- Set measurable targets for response time, throughput, context length, uptime, and maximum concurrent requests.
- Choose a representative evaluation set, including difficult prompts, refusal cases, tool calls, long-context examples, and multilingual inputs if those matter to your users.
2. Select the model and quantization
Begin with gpt-oss-20b when the workload is moderate or hardware is constrained; test gpt-oss-120b when quality on complex reasoning or specialized tasks justifies the larger footprint. Select a quantization that fits with operational headroom, then verify answer quality on your evaluation set. Keep the unquantized or higher-precision reference available for comparison if storage permits.
Rank #4

- Graphics Coprocessor NVIDIA Quadro K4000
- Brand NVIDIA
- Graphics Ram Size 3 GB
3. Install a runtime that matches the hardware
- Install the runtime version supported by your operating system and accelerator drivers.
- Obtain the model package or weights from the documented distribution channel and verify checksums or signatures where provided.
- Configure the runtime for the intended context length, maximum output, device layers or accelerator use, and concurrency.
- Start with the narrowest network binding that works. A local-only listener is safer than exposing an unauthenticated service to a broader network.
- Send test requests that exercise short prompts, long context, parallel requests, cancellation, and malformed input.
4. Put an application boundary in front of the model
Do not treat a raw model endpoint as a complete product. Place an authenticated service or gateway in front of it, enforce request and response size limits, apply per-user or per-tenant quotas, and restrict which internal systems the model can reach. If the model can call tools, use an allowlist and separate credentials for each tool. A prompt should never be able to retrieve arbitrary secrets merely because the serving process can access them.
5. Measure before rollout
- Record time to first token, generation rate, end-to-end latency, error rate, queue depth, and GPU or CPU utilization.
- Repeat tests at expected concurrency and at a stress level that reveals saturation.
- Compare quality and refusal behavior across the selected quantization and context settings.
- Test restart recovery, model reload time, disk exhaustion, driver failure, and loss of the network dependency used to retrieve documents or tools.
Privacy is improved, not automatic
OpenAI states: “OpenAI does not receive or process the data you send to these self-hosted models unless you explicitly share it with OpenAI, or use one of our managed hosting partners.” That describes the model inference data path, not your entire system. Telemetry, container registries, monitoring platforms, backup jobs, support bundles, and application logs can still move sensitive information if you configure them to do so.
The Tool Desk
Outbyte PC Repair FREEClear out junk files and repair common Windows errorsFree Scan →Outbyte Driver Updater FREEScan for outdated or missing drivers - takes under a minuteDriver Scan →Self-hosting transfers responsibility to the deploying organization. Establish the following controls before production use:
- Network isolation: keep inference traffic on private networks, restrict outbound access, and document any required update or package repositories.
- Identity and authorization: require authenticated clients, separate administrator and inference roles, rotate credentials, and isolate tenants.
- Data handling: define retention for prompts, outputs, traces, and cached documents; redact secrets from logs; encrypt data at rest and in transit.
- Patch management: update the operating system, drivers, runtime, containers, and dependencies on a documented schedule.
- Model governance: record the exact model revision, license, usage policy, quantization, system prompt, and safety configuration used in each release.
- Evaluation and incident response: test harmful, confidential, biased, and prompt-injection cases; provide a way to disable the service and investigate incidents.
Licensing, support, and total cost
The Apache 2.0 license can simplify internal use and redistribution compared with a closed hosted API, but you must preserve required notices and comply with the gpt-oss usage policy. Have counsel review how the policy applies to your application, fine-tuning, redistribution, and customer-facing service.
Self-hosting also changes who provides support. OpenAI describes these deployments as self-managed and self-serviced and does not provide hands-on implementation or debugging support for third-party runtimes. Your team therefore needs Linux, GPU or CPU infrastructure, networking, observability, and model-serving skills, or a support contract with a qualified hosting or deployment provider.
Best Value
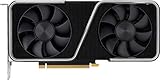
- GeForce RTX 30 Series GPUs deliver ultimate performance for gamers and creators. They're powered by Ampere, NVIDIA's 2nd generation RTX architecture, with new RT cores, Tensor cores, and streaming multiprocessors for the most realistic ray-plotted graphics and cutting-edge AI features.
- Discover today's biggest blockbusters like never before with the visual fidelity of real-time ray tracing and the ultimate performance of AI-powered DLSS. RTX It's on.
- NVIDIA DLSS is a revolutionary AI rendering that increases frame rates with uncompromising image quality using dedicated AI processing Tensor cores on Geforce RTX. This gives you the margin of performance to increase settings and resolutions for an amazing visual experience. The AI revolution has arrived in the game.
- NVIDIA Reflex delivers the ultimate competitive advantage. The lowest latency. The best responsiveness. Powered by Geforce RTX 30 Series GPUs and NVIDIA G-SYNC monitors. Acquire targets faster, react faster and increase aiming accuracy with a revolutionary suite of technologies to measure and optimize system latency for competitive gaming.
- Enhance your creative projects with Geforce RTX 30 Series GPUs. Accelerate AI in the best creative applications. Supported by the NVIDIA Studio platform of dedicated drivers and exclusive tools. Designed to run in record time. Whether it's rendering complex 3D scenes, editing 8K videos, or live streaming with the best encoding and image quality, Geforce RTX GPUs give you the performance you need to create the best.
Calculate total cost rather than comparing a model download with an API request price. Include:
What’s actually slowing this PC down?
Pick the symptom - the matching free tool is one click away.
- Server or GPU purchase, rental, or managed-hosting fees.
- Electricity, cooling, rack space, and replacement hardware.
- Storage for weights, quantized variants, logs, backups, and evaluation data.
- Engineering time for deployment, upgrades, security review, and incident response.
- Network egress and any private connectivity charges.
- Downtime, capacity headroom, and a second node if availability requirements demand failover.
Common failure modes and fixes
The model loads but runs out of memory
Reduce the context limit or concurrency, use a tested quantization, move other workloads off the device, or select the smaller model. Leave operational headroom; a configuration that barely loads is not production-ready.
Responses are too slow
Measure whether the delay is in queueing, prompt processing, generation, or downstream retrieval. Shorten unnecessary context, improve document retrieval, tune batching, and compare llama.cpp with a CUDA-backed vLLM deployment when concurrent traffic is the bottleneck.
One user affects everyone else
Set per-user limits, queue requests, cap context and output lengths, and reserve capacity for interactive traffic. A single large request can consume the KV cache and starve shorter requests if limits are absent.
The local endpoint is accidentally exposed
Check bind addresses, firewall rules, reverse-proxy routes, cloud security groups, and container port mappings. Require authentication at the gateway and verify from another network that the endpoint is not reachable when it should be private.
Quick wins for a faster PC:
Repair Windows errors before they cause bigger problemsFix Now →Scan for outdated or missing drivers - takes under a minuteDriver Scan →Clear out junk files and repair common Windows errorsFree Scan →Quality changes after an upgrade
Pin the model revision, runtime version, quantization, prompt template, and decoding settings in deployment records. Re-run the representative evaluation set before promoting a new combination.
Tool use creates a security hole
Run tools through a broker with explicit schemas and allowlists. Give each tool the minimum credential scope, validate arguments, log calls without exposing secrets, and require human approval for irreversible actions.
A practical decision framework
- Need a local proof of concept today? Try Ollama with a compatible gpt-oss package, keeping the service local until authentication and data handling are configured.
- Have CPU-only, Apple Silicon, or limited GPU memory? Start with llama.cpp and a quantized model; benchmark the exact context and concurrency you expect.
- Need many simultaneous requests and high throughput? Test vLLM on a supported NVIDIA CUDA system, then size the cluster from measured peak traffic rather than model parameter count alone.
- Handle regulated or highly confidential data? Treat private inference as one layer of a broader control system. Review logs, backups, network egress, access rights, and retention before onboarding real data.
- Cannot operate servers reliably? Consider managed private hosting or deployment support, but verify contractual data handling, isolation, patching, incident response, and who controls the encryption keys.
Migration checklist for an OpenAI-compatible application
Applications written for a hosted API may be able to switch to a vLLM endpoint that presents an OpenAI-compatible interface, but compatibility is not identity. Review every assumption about model names, tokenizer behavior, context limits, streaming, tool calls, structured output, error formats, and rate limits.
Quick Recap
- Replace the remote base URL with the private endpoint and use a dedicated service credential.
- Map the application’s requested model to the exact locally deployed revision.
- Run contract tests for chat, streaming, retries, timeouts, tool calls, and structured responses.
- Re-test prompts against your evaluation set; the same prompt can produce different results across model revisions and decoding settings.
- Update privacy notices and data-flow diagrams to show the new boundary.
- Define rollback to the previous model or runtime before switching production traffic.
Bottom line for each common workload
| Workload | Recommended starting choice | Decision condition |
|---|---|---|
| Personal coding or writing assistant | gpt-oss-20b with Ollama or llama.cpp | Choose the runtime that your computer supports comfortably and keep the endpoint local |
| Offline or disconnected workstation | gpt-oss-20b with llama.cpp | Prioritize quantized files, CPU or local-accelerator support, and repeatable model storage |
| Internal knowledge assistant for a small team | gpt-oss-20b first; evaluate gpt-oss-120b if quality requires it | Measure retrieval quality, context use, concurrent sessions, and access controls |
| High-concurrency production API | gpt-oss-120b or 20b with vLLM on supported CUDA hardware | Pick the model from evaluation results and size the fleet from peak throughput tests |
| Strictly controlled private-cloud deployment | Either model with the runtime that matches the approved platform | Document egress, logging, patching, identity, and operational ownership |
Product prices and availability are accurate as of the date/time indicated and are subject to change. Any price and availability information displayed on Amazon at the time of purchase will apply.
Free tools Windows power users keep installed
One-click scans. No signup required.

