
To retrieve an old website, open the Wayback Machine, enter the page URL (or its domain), select Browse History, choose a capture date, and inspect the replay. For a deep page, search its complete URL rather than relying on the site’s home page. Always check the timestamp in the replay URL: linked pages can be substituted with a nearby capture date or, if nothing was archived, the live web.
Find an archived page in the Wayback Machine
- Go to web.archive.org (the service is also reachable through archive.org/web).
- Paste the original URL, including the path, query string when relevant, and file extension. Select Browse History. If you only know the domain, enter that first and use the calendar to explore its captures.
- Choose a year on the timeline, then a date and time in the calendar. The Help Center describes blue dots as successful 2xx captures, green as redirects (3xx), orange as client errors (4xx), and red as server errors (5xx); a blue capture is usually the best starting point.
- Open the snapshot and read the replay URL. Its timestamp uses
YYYYMMDDhhmmss(for example,20000229123340means 29 February 2000 at 12:33:40). Copy the complete replay URL if you need a stable reference.
Archived pages are evidence of what the crawler saved, not a guaranteed copy of the original site. Preserve the page title, author, publication date and the archived URL separately when you are documenting historical material.


Retrieve a specific deep page, image or document
Search the exact page URL
Knowing a domain is not enough when the page you need was buried in a blog, help center or subdirectory. Enter the full historical URL directly, including a trailing slash when the original used one. Try both http and https if you are unsure which protocol was used. A blank calendar for one spelling does not establish that the page never existed.
Recover a linked file
If an image, PDF, stylesheet or download is missing, copy its original URL (not just the replay URL) and paste it into the Wayback search box. The Internet Archive Help Center says, “You can tell if the image or link you are looking for is in the Wayback Machine by entering the image or link’s URL into the Wayback Machine search box.” A file may have been crawled independently from the page that references it.
The Tool Desk
Outbyte PC Repair FREEClear out junk files and repair common Windows errorsFree Scan →Outbyte Driver Updater FREEFix the driver behind crashes, sound loss and screen glitchesFind Drivers →#1 Best Overall

- Used Book in Good Condition
Inspect all recorded paths
For a broad inventory, the Help Center gives this pattern:
http://web.archive.org/*/www.yoursite.com/*
Replace the example host with the domain you are investigating. Results still represent discovered captures, not a complete directory listing or backup.
Verify that the replay is really the date you selected
Wayback can use the closest available capture when a linked resource was not saved on the exact day. In some cases an uncaptured link can lead to the live website. After every important click:
- Look for
/web/YYYYMMDDhhmmss/in the address bar. - Compare the timestamp with the date you intended to cite.
- Check the hostname and path after the timestamp; a redirect may have moved you to another page.
- Do not assume that a page displaying successfully is archived—live content can look identical.
If date fidelity matters, return to the calendar and open a capture of the target URL itself instead of following a link from another replay.
Windows Errors? Fix Them Before They Spread
Repair common Windows errors and clear accumulated junk for a smoother, more stable PC - no reinstall needed.Free scan · no reinstallCrashes, No Sound, or Screen Glitches?
Random freezes, missing sound and display glitches usually trace back to one bad driver. Find and replace yours safely.Free scan · under a minuteWhy an archived page is missing
No capture appears
A missing result can mean the crawler never discovered the URL, the server was inaccessible, the page required a password, robots rules prevented crawling, or the owner requested exclusion. The Internet Archive states, “We can’t guarantee that your site has been or will be archived.” Try the exact URL, the domain, alternate protocols, and known URL variants before concluding that the page is unavailable.
Images are broken or gray
The image file may not have its own capture, may have been served from another hostname, or may have depended on a path that changed. Search each image’s original URL directly. CSS, fonts and JavaScript can fail for the same reason.
Rank #2
Buttons, forms or menus do not work
Replay cannot recreate every interaction. Features that depend on JavaScript, server-side image maps, form submissions, database queries, authentication or continuing contact with the original server may not function. Simple, self-contained HTML is generally the easiest material to replay. Treat a non-working control as a limitation of preservation, not proof that the original feature never existed.
The page jumps to today’s website
That usually means the linked destination has no archived version, so the archive fetched the live web. Check the timestamp segment immediately. Use the destination’s original URL in a fresh Wayback search and select a dated capture, if one exists.
Recommended Free Tools
Can you download the whole archived website?
Not through the normal Save Page Now workflow. Save Page Now stores the submitted page and, where available, its images and CSS; it does not save outlinks, directories or an entire site. The Help Center states, “It does not save multiple pages, directories or entire sites.” The Internet Archive also says it cannot guarantee a site was archived and does not offer to package lost websites as backups for the general public.
You can manually collect several replay URLs, download individual assets, or use capture metadata to plan a larger investigation, but do not promise a complete, browsable restoration unless you have independently verified every required page and file.
Save a page for future reference
- Open the page you want to preserve in its current form.
- Use Save Page Now in the Wayback interface (the browser extension can also invoke the save action).
- Wait for the returned replay URL and open it to confirm what was captured.
- Store that replay URL with the original URL and your access date. A saved page is a point-in-time record, not a crawl of its outlinks.
Images and CSS are included only when the service can retrieve them. Interactive or third-party resources may remain incomplete.
Automate capture discovery with official APIs
Availability API: one closest snapshot
For a quick programmatic check, the developer documentation uses this request:
Free tools Windows power users keep installed
One-click scans. No signup required.
Rank #3
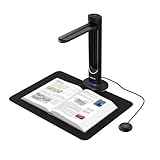
- [48MP Ultra-High Resolution] The K48 is a professional-grade book scanner equipped with a true 48MP Sony CMOS sensor, capable of capturing exceptional detail at 600 DPI — even on A3-sized materials. Used for digitizing books, magazines, documents, and archival materials with stunning clarity.
- [AI-Assisted Page Smoothing] Curved book pages are automatically flattened using intelligent software technology. This causes the removal of finger shadows, background interference, and page curvature — delivering flat, clean scans without any manual post-processing. Double pages are split automatically.
- [Laser Positioning & Auto-Scan] The built-in laser positioning system ensures precise alignment every time. Page turning detection causes the scanner to start capturing automatically as soon as a page is turned — ideal for high-volume digitization where speed matters.
- [Multi-Format OCR & Text-to-Speech] Used for creating searchable PDFs, editable Word/Excel files, or MP3 audio for voice playback. The K48 is capable of recognizing text in multiple languages and converting documents into accessible formats — perfect for education, accessibility compliance, and digital archives.
- [4K Live View & USB 3.0] Stream 4K@30fps video for live presentations, online classes, or real-time document review. USB 3.0 Type-C ensures fast data transfer and stable connection. Used for immediate setup in classrooms, offices, and libraries — plug and play, no drivers needed.
http://archive.org/wayback/available?url=example.com
The documented response provides one closest snapshot when one is available. Use it as a discovery aid, then inspect the returned timestamp and replay URL. A positive response does not prove that every page, image or stylesheet was preserved.
Memento and CDX for broader queries
The Internet Archive developer documentation describes Memento interfaces for additional snapshot queries and CDX for complex capture-data filtering, analysis and selection. These are appropriate when you need to examine many captures, constrain dates or inspect status codes. Documentation spans 2018–2022, so verify endpoint behavior and response fields before putting an integration into production.
Choose the right retrieval method
| Method | Best for | Effort | Scope |
|---|---|---|---|
| Wayback calendar | Finding and reading a known page | Browser, low technical skill | One URL or domain history |
| Direct deep-URL lookup | Recovering a specific article, asset or PDF | Browser, low technical skill | One resource at a time |
| Browser extension | Saving the page currently open and checking its history | Browser installation | Current page; extension repository features include page snapshot count and last-save information |
| Availability API | Checking for one closest capture | HTTP request or script | One URL and one closest result |
| Memento | Querying snapshots through time-oriented interfaces | Developer knowledge | Additional snapshot discovery |
| CDX | Filtering and analyzing capture records | Advanced developer workflow | Many captures and metadata conditions |
Troubleshoot the common failure modes
“No captures found”
- Search the full page URL and the bare domain.
- Try both HTTP and HTTPS, and remove or add a trailing slash.
- Check old links, sitemaps or published references for an earlier URL.
- Consider discovery, password protection, robots exclusion, outages and owner removal as possible explanations.
“The wrong date loaded”
- Read the replay timestamp rather than trusting the calendar page you came from.
- Search the destination URL directly for a capture near your target date.
- Record the actual timestamp you used in your notes or citation.
“The layout is broken”
- Search missing CSS, fonts and images by their original URLs.
- Try another capture of the same page; one crawl may have saved more dependencies.
- Expect modern JavaScript applications, embedded video, maps and authenticated areas to be incomplete.
“I need a complete downloadable copy”
Wayback’s public page-saving feature is not a whole-site backup. Build a verified list of URLs and assets, retrieve each available replay, and label gaps explicitly. If the requirement is a regularly maintained organizational crawl rather than one historical lookup, the Internet Archive describes Archive-It as a paid subscription service for recurring web-crawl projects.
Or skip the browser setup
If your actual goal is to create a current screenshot of a page for documentation, testing or an archive workflow, ScreenshotNeo returns an image or PDF from one GET request. It is not a substitute for finding a historical Wayback capture; it is a simpler way to capture an accessible page now.
Use the ScreenshotNeo API documentation for options and authentication. cURL:
curl -G "https://api.screenshotneo.com/v1/shot" -d access_key=YOUR_API_KEY --data-urlencode url=https://stripe.com -o shot.webp
Python:
import requests

r = requests.get("https://api.screenshotneo.com/v1/shot", params={"access_key": "YOUR_API_KEY", "url": "https://stripe.com"}, timeout=90)

open("shot.webp", "wb").write(r.content)
What’s actually slowing this PC down?
Pick the symptom - the matching free tool is one click away.
Node.js:
const q = new URLSearchParams({ access_key: 'YOUR_API_KEY', url: 'https://stripe.com' });

const res = await fetch(`https://api.screenshotneo.com/v1/shot?${q}`);
Before capture, ScreenshotNeo can accept cookie or consent banners and remove more than 60 known consent platforms, newsletter popups and chat widgets; each step can be disabled. Bot checks or CAPTCHAs, blank pages, timeouts, failed loads and cache hits are not billed, and response headers identify the page verdict and billing status. Its MCP server provides take_screenshot, get_page_info and capture_pdf tools for Claude, Cursor and other MCP clients. The Free plan includes 1,000 screenshots per month without a card; paid plans start at $5 for 3,000 screenshots. Every feature is available on every plan. Create a free ScreenshotNeo account.
Use archived evidence responsibly
- Cite the replay URL and its embedded timestamp, not only the modern destination URL.
- Keep the original URL, capture date and any downloaded files together.
- Mark missing assets and non-functional interactions instead of reconstructing them silently.
- Distinguish a historical capture from a present-day ScreenshotNeo screenshot or any other new capture.
- Do not treat a blank calendar as proof that a page never existed.
Frequently Asked Questions
How do I find an old version of a page when I only know its domain?
Enter the domain at https://web.archive.org/, choose Browse History, then use the timeline and calendar to locate a dated capture. Search the complete page URL once you discover it.
What does the timestamp in a Wayback URL mean?
The timestamp is formatted as YYYYMMDDhhmmss and identifies the replay date and time. Verify it after following links because a nearby capture or the live page may be returned.
Does Save Page Now archive links from the page?
No. It saves the submitted page, with images and CSS where available, but not its outlinks, directories or an entire site.
Why can an archived page have missing images?
The image may not have been captured, may be hosted under another URL, or may depend on an unavailable original resource. Search the image URL separately in Wayback.
Quick Recap
Product prices and availability are accurate as of the date/time indicated and are subject to change. Any price and availability information displayed on Amazon at the time of purchase will apply.

